





























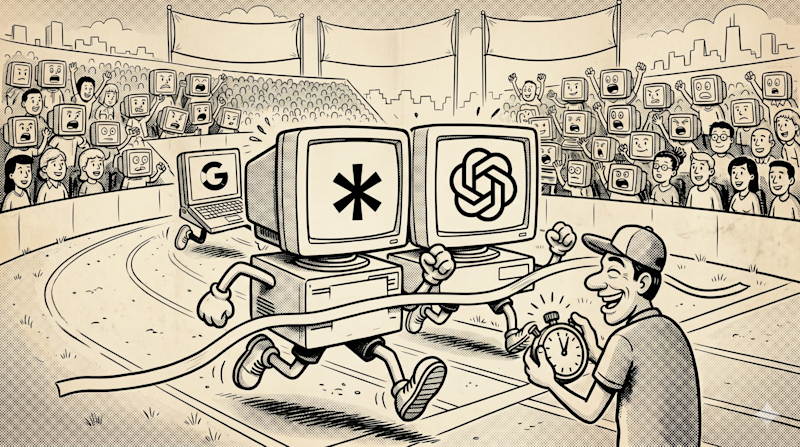
Anthropic is publicly releasing its most powerful large language model yet, Claude Opus 4.7, today — as it continues to keep an even more powerful successor, Mythos, restricted to a small number of external enterprise partners for cybersecurity testing and patching vulnerabilities in the software said enterprises use (which Mythos exposed rapidly).
The big headlines are that Opus 4.7 exceeds its most direct rivals — OpenAI’s GPT-5.4, released in early March 2026, scarcely more than a month ago; and Google’s latest flagship model Gemini 3.1 Pro from February — on key benchmarks including agentic coding, scaled tool-use, agentic computer use, and financial analysis.
But also, it’s notable how tight the race is getting: on directly comparable benchmarks, Opus 4.7 only leads GPT-5.4 by 7-4.
It currently leads the market on the GDPVal-AA knowledge work evaluation with an Elo score of 1753, surpassing both GPT-5.4 (1674) and Gemini 3.1 Pro (1314).

Yet, the model does not represent a «clean sweep» across all categories.
Competitors like GPT-5.4 and Gemini 3.1 Pro still hold the lead in specific domains such as agentic search, where GPT-5.4 scores 89.3% compared to Opus 4.7’s 79.3%, as well as in multilingual Q&A and raw terminal-based coding.
This positioning defines Opus 4.7 not as a unilateral victor in all AI tasks, but as a specialized powerhouse optimized for the reliability and long-horizon autonomy required by the burgeoning agentic economy.
Claude Opus 4.7 is available today across all major cloud platforms, including Amazon Bedrock, Google Cloud’s Vertex AI, and Microsoft Foundry, with API pricing held steady at $5/$25 per million tokens.
Improvement in hard sciences and agentic workflows
Claude Opus 4.7 is a direct evolution of the Opus 4.6 architecture, but its performance delta is most visible in the «hard» sciences of agentic workflows: software engineering and complex document reasoning.
At its core, the model has been re-tuned to exhibit what Anthropic describes as «rigor». This isn’t just marketing parlance; it refers to the model’s new ability to devise its own verification steps before reporting a task as complete.
For example, in internal tests, the model was observed building a Rust-based text-to-speech engine from scratch and then independently feeding its own generated audio through a separate speech recognizer to verify the output against a Python reference.
This level of autonomous self-correction is designed to reduce the «hallucination loops» that often plague earlier iterations of agentic software.
The most significant architectural upgrade is the move to high-resolution multimodal support. Opus 4.7 can now process images up to 2,576 pixels on their longest edge—roughly 3.75 megapixels.
This represents a three-fold increase in resolution compared to previous iterations. For developers building «computer-use» agents that must navigate dense, high-DPI interfaces or for analysts extracting data from intricate technical diagrams, this change effectively removes the «blurry vision» ceiling that previously limited autonomous navigation.
This visual acuity is reflected in benchmarks from XBOW, where the model jumped from a 54.5% success rate in visual-acuity tests to 98.5%.
On the benchmark front, Opus 4.7 has claimed the top spot in several critical categories:
-
Knowledge Work (GDPVal-AA): It achieved an Elo score of 1753, notably outperforming GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
-
Agentic Coding (SWE-bench Pro): The model resolved 64.3% of tasks, compared to 53.4% for its predecessor.
-
Graduate-Level Reasoning (GPQA Diamond): It reached 94.2%, maintaining parity with the industry’s most advanced models while improving on its internal consistency.
-
Visual Reasoning (arXiv Reasoning): With tools, the model scored 91.0%, a meaningful jump from the 84.7% seen in Opus 4.6.
Crucially, Anthropic warns that this increased precision requires a shift in how users approach prompting. Opus 4.7 follows instructions literally. While older models might «read between the lines» and interpret ambiguous prompts loosely, Opus 4.7 executes the exact text provided. This means that legacy prompt libraries may require re-tuning to avoid unexpected results caused by the model’s strict adherence to the letter of the request.
Controlling the ‘thinking’ budget
The «agentic» nature of Opus 4.7—its tendency to pause, plan, and verify—comes with a trade-off in token consumption and latency.
To address this, Anthropic is introducing a new «effort» parameter. Users can now select an xhigh (extra high) effort level, positioned between high and max, allowing for more granular control over the depth of reasoning the model applies to a specific problem.
Internal data shows that while max effort yields the highest scores (approaching 75% on coding tasks), the xhigh setting provides a compelling sweet spot between performance and token expenditure.
To manage the costs associated with these more «thoughtful» runs, the Claude API is introducing «task budgets» in public beta. This allows developers to set a hard ceiling on token spend for autonomous agents, ensuring that a long-running debugging session doesn’t result in an unexpected bill.
These product changes signal a maturing market where AI is no longer a novelty but a production line item that requires fiscal and operational guardrails.
Furthermore, Opus 4.7 utilizes an updated tokenizer that improves text processing efficiency, though it can increase the token count of certain inputs by 1.0–1.35x.
Within the Claude Code environment, the update brings a new /ultrareview command. Unlike standard code reviews that look for syntax errors, /ultrareview is designed to simulate a senior human reviewer, flagging subtle design flaws and logic gaps.
Additionally, «auto mode»—a setting where Claude can make autonomous decisions without constant permission prompts—has been extended to Max plan users.
Licensing, safety, and the «cyber» divide
Anthropic continues to walk a narrow line regarding cybersecurity. The recent announcement of the aforementioend cybersecurity partnership around Mythos with external industry partners — known as «Project Glasswing» — highlighted the dual-use risks of high-capability models.
Consequently, while the flagship Mythos Preview model remains restricted, Opus 4.7 serves as the testbed for new automated safeguards. The model includes systems designed to detect and block requests that suggest high-risk cyberattacks, such as automated vulnerability exploitation.
To bridge the gap for the security industry, Anthropic is launching the Cyber Verification Program. This allows legitimate professionals—vulnerability researchers, penetration testers, and red-teamers—to apply for access to use Opus 4.7’s capabilities for defensive purposes.
This «verified user» model suggests a future where the most capable AI features are not universally available, but gated behind professional credentials and compliance frameworks.
In cybersecurity vulnerability reproduction (CyberGym), Opus 4.7 maintains a 73.1% success rate, trailing Mythos Preview’s 83.1% but leading GPT-5.4’s 66.3%.
Initial reactions from industry partners reveal quantifiable improvements in production enterprise workflows
Early testimonials from enterprise customers shared by Anthropic indicate there has been a tangible shift in model perception of Opus 4.7 from 4.6, going from «impressed by the tech» to «relying on the output».
Clarence Huang, VP of Technology at Intuit, noted that the model’s ability to «catch its own logical faults during the planning phase» is a game-changer for velocity.
This sentiment was echoed by Replit President Michele Catasta, who stated that the model achieved higher quality at a lower cost for tasks like log analysis and bug hunting, adding, «It really feels like a better coworker».
Other specific reactions included:
-
Cognition (Devin): CEO Scott Wu reported that Opus 4.7 can work coherently «for hours» and pushes through difficult problems that previously caused models to stall.
-
Notion: Sarah Sachs, AI Lead, highlighted a 14% improvement in multi-step workflows and a 66% reduction in tool-calling errors, making the agent feel like a «true teammate».
-
Factory Droids: Leo Tchourakov observed that the model carries work through to validation steps rather than «stopping halfway,» a common complaint with previous frontier models.
-
Harvey: Niko Grupen, Head of Applied Research, noted the model’s 90.9% score on BigLaw Bench, highlighting its «noticeably smarter handling of ambiguous document editing tasks».
Perhaps the most telling reaction came from Aj Orbach, CEO of a dashboard-building firm, who remarked on the model’s «design taste,» noting that its choices for data-rich interfaces were of a quality he would «actually ship».
Should enterprises immediately upgrade to Opus 4.7?
For enterprise leaders, Claude Opus 4.7 represents a shift from generative AI as a «creative assistant» to a «reliable operative.»
But importantly, it is not a «clean win» for every use case.
Instead, it is a decisive upgrade for teams building autonomous agents or complex software systems. The primary value proposition is the model’s new capability for self-verification and rigor; it no longer just generates an answer but creates internal tests to verify that the answer is correct before responding. This reliability makes it a superior choice for long-horizon engineering tasks where the cost of human supervision is the primary bottleneck.
However, an immediate, wholesale migration from Opus 4.6 requires caution. The model’s increased literalism in instruction following means that prompts engineered to be «loose» or conversational with previous versions may now produce unexpected or overly rigid results.
Furthermore, enterprises must prepare for a significant increase in operational costs. Opus 4.7 uses an updated tokenizer that can increase input token counts by 1.0–1.35x, and its tendency to «think harder» at high effort levels results in higher output token consumption.
For legacy applications where prompts are fragile and margins are thin, a phased rollout with significant re-tuning is recommended.
Where it puts Anthropic in the AI race
This release arrives at a paradoxical moment for Anthropic. Financially, the company is an undisputed juggernaut, with venture capital firms reportedly extending investment offers at a staggering $800 billion valuation—more than double its $380 billion Series G valuation from February 2026.
This momentum is fueled by explosive growth, with the company’s annual run-rate revenue skyrocketing to $30 billion in April 2026, driven largely by enterprise adoption and the success of Claude Code.
Yet, this commercial success is being contested by intense regulatory and technical friction. Anthropic is currently embroiled in a high-stakes legal battle with the U.S. Department of War (DoW), which recently labeled the company a «supply chain risk» after Anthropic refused to allow its models to be used for mass surveillance or fully autonomous lethal weapons.
While a San Francisco judge initially blocked the designation, a federal appeals panel recently denied Anthropic’s bid to stay the blacklisting, leaving the company excluded from lucrative defense contracts during an active military conflict.
Simultaneously, Anthropic is fending off a growing rebellion from its most loyal power users. Despite the company’s «market leader» status, developers have flooded GitHub and X with accusations of «AI shrinkflation,» claiming that the preceding Opus 4.6 model and Claude Code product have been quietly degraded.
Users report that recent versions are more prone to exploration loops, memory loss, and ignored instructions, leading some to describe the newly released Claude Code desktop app as «unpolished» and unbefitting a firm with a near-trillion-dollar valuation. Opus 4.7 is Anthropic’s attempt to silence these critics by proving that «deep thinking» can be paired with the rigorous execution that its enterprise clients now demand.
Ultimately, Opus 4.7 is a model defined by its discipline. In a market where models are often incentivized to be «helpful» to a fault—sometimes hallucinating answers to please the user—Opus 4.7 marks a return to rigor. By allowing users to control effort, set budgets, and verify outputs, Anthropic is moving closer to the goal of a truly autonomous digital labor force. For the engineering teams at Replit, Notion, and beyond, the shift from «watching the AI work» to «managing the AI’s results» has officially begun.

Anthropic is publicly releasing its most powerful large language model yet, Claude Opus 4.7, today — as it continues to keep an even more powerful successor, Mythos, restricted to a small number of external enterprise partners for cybersecurity testing and patching vulnerabilities in the software said enterprises use (which Mythos exposed rapidly).
The big headlines are that Opus 4.7 exceeds its most direct rivals — OpenAI’s GPT-5.4, released in early March 2026, scarcely more than a month ago; and Google’s latest flagship model Gemini 3.1 Pro from February — on key benchmarks including agentic coding, scaled tool-use, agentic computer use, and financial analysis.
But also, it’s notable how tight the race is getting: on directly comparable benchmarks, Opus 4.7 only leads GPT-5.4 by 7-4.
It currently leads the market on the GDPVal-AA knowledge work evaluation with an Elo score of 1753, surpassing both GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
Yet, the model does not represent a «clean sweep» across all categories.
Competitors like GPT-5.4 and Gemini 3.1 Pro still hold the lead in specific domains such as agentic search, where GPT-5.4 scores 89.3% compared to Opus 4.7’s 79.3%, as well as in multilingual Q&A and raw terminal-based coding.
This positioning defines Opus 4.7 not as a unilateral victor in all AI tasks, but as a specialized powerhouse optimized for the reliability and long-horizon autonomy required by the burgeoning agentic economy.
Claude Opus 4.7 is available today across all major cloud platforms, including Amazon Bedrock, Google Cloud’s Vertex AI, and Microsoft Foundry, with API pricing held steady at $5/$25 per million tokens.
Improvement in hard sciences and agentic workflows
Claude Opus 4.7 is a direct evolution of the Opus 4.6 architecture, but its performance delta is most visible in the «hard» sciences of agentic workflows: software engineering and complex document reasoning.
At its core, the model has been re-tuned to exhibit what Anthropic describes as «rigor». This isn’t just marketing parlance; it refers to the model’s new ability to devise its own verification steps before reporting a task as complete.
For example, in internal tests, the model was observed building a Rust-based text-to-speech engine from scratch and then independently feeding its own generated audio through a separate speech recognizer to verify the output against a Python reference.
This level of autonomous self-correction is designed to reduce the «hallucination loops» that often plague earlier iterations of agentic software.
The most significant architectural upgrade is the move to high-resolution multimodal support. Opus 4.7 can now process images up to 2,576 pixels on their longest edge—roughly 3.75 megapixels.
This represents a three-fold increase in resolution compared to previous iterations. For developers building «computer-use» agents that must navigate dense, high-DPI interfaces or for analysts extracting data from intricate technical diagrams, this change effectively removes the «blurry vision» ceiling that previously limited autonomous navigation.
This visual acuity is reflected in benchmarks from XBOW, where the model jumped from a 54.5% success rate in visual-acuity tests to 98.5%.
On the benchmark front, Opus 4.7 has claimed the top spot in several critical categories:
-
Knowledge Work (GDPVal-AA): It achieved an Elo score of 1753, notably outperforming GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
-
Agentic Coding (SWE-bench Pro): The model resolved 64.3% of tasks, compared to 53.4% for its predecessor.
-
Graduate-Level Reasoning (GPQA Diamond): It reached 94.2%, maintaining parity with the industry’s most advanced models while improving on its internal consistency.
-
Visual Reasoning (arXiv Reasoning): With tools, the model scored 91.0%, a meaningful jump from the 84.7% seen in Opus 4.6.
Crucially, Anthropic warns that this increased precision requires a shift in how users approach prompting. Opus 4.7 follows instructions literally. While older models might «read between the lines» and interpret ambiguous prompts loosely, Opus 4.7 executes the exact text provided. This means that legacy prompt libraries may require re-tuning to avoid unexpected results caused by the model’s strict adherence to the letter of the request.
Controlling the ‘thinking’ budget
The «agentic» nature of Opus 4.7—its tendency to pause, plan, and verify—comes with a trade-off in token consumption and latency.
To address this, Anthropic is introducing a new «effort» parameter. Users can now select an xhigh (extra high) effort level, positioned between high and max, allowing for more granular control over the depth of reasoning the model applies to a specific problem.
Internal data shows that while max effort yields the highest scores (approaching 75% on coding tasks), the xhigh setting provides a compelling sweet spot between performance and token expenditure.
To manage the costs associated with these more «thoughtful» runs, the Claude API is introducing «task budgets» in public beta. This allows developers to set a hard ceiling on token spend for autonomous agents, ensuring that a long-running debugging session doesn’t result in an unexpected bill.
These product changes signal a maturing market where AI is no longer a novelty but a production line item that requires fiscal and operational guardrails.
Furthermore, Opus 4.7 utilizes an updated tokenizer that improves text processing efficiency, though it can increase the token count of certain inputs by 1.0–1.35x.
Within the Claude Code environment, the update brings a new /ultrareview command. Unlike standard code reviews that look for syntax errors, /ultrareview is designed to simulate a senior human reviewer, flagging subtle design flaws and logic gaps.
Additionally, «auto mode»—a setting where Claude can make autonomous decisions without constant permission prompts—has been extended to Max plan users.
Licensing, safety, and the «cyber» divide
Anthropic continues to walk a narrow line regarding cybersecurity. The recent announcement of the aforementioend cybersecurity partnership around Mythos with external industry partners — known as «Project Glasswing» — highlighted the dual-use risks of high-capability models.
Consequently, while the flagship Mythos Preview model remains restricted, Opus 4.7 serves as the testbed for new automated safeguards. The model includes systems designed to detect and block requests that suggest high-risk cyberattacks, such as automated vulnerability exploitation.
To bridge the gap for the security industry, Anthropic is launching the Cyber Verification Program. This allows legitimate professionals—vulnerability researchers, penetration testers, and red-teamers—to apply for access to use Opus 4.7’s capabilities for defensive purposes.
This «verified user» model suggests a future where the most capable AI features are not universally available, but gated behind professional credentials and compliance frameworks.
In cybersecurity vulnerability reproduction (CyberGym), Opus 4.7 maintains a 73.1% success rate, trailing Mythos Preview’s 83.1% but leading GPT-5.4’s 66.3%.
Initial reactions from industry partners reveal quantifiable improvements in production enterprise workflows
Early testimonials from enterprise customers shared by Anthropic indicate there has been a tangible shift in model perception of Opus 4.7 from 4.6, going from «impressed by the tech» to «relying on the output».
Clarence Huang, VP of Technology at Intuit, noted that the model’s ability to «catch its own logical faults during the planning phase» is a game-changer for velocity.
This sentiment was echoed by Replit President Michele Catasta, who stated that the model achieved higher quality at a lower cost for tasks like log analysis and bug hunting, adding, «It really feels like a better coworker».
Other specific reactions included:
-
Cognition (Devin): CEO Scott Wu reported that Opus 4.7 can work coherently «for hours» and pushes through difficult problems that previously caused models to stall.
-
Notion: Sarah Sachs, AI Lead, highlighted a 14% improvement in multi-step workflows and a 66% reduction in tool-calling errors, making the agent feel like a «true teammate».
-
Factory Droids: Leo Tchourakov observed that the model carries work through to validation steps rather than «stopping halfway,» a common complaint with previous frontier models.
-
Harvey: Niko Grupen, Head of Applied Research, noted the model’s 90.9% score on BigLaw Bench, highlighting its «noticeably smarter handling of ambiguous document editing tasks».
Perhaps the most telling reaction came from Aj Orbach, CEO of a dashboard-building firm, who remarked on the model’s «design taste,» noting that its choices for data-rich interfaces were of a quality he would «actually ship».
Should enterprises immediately upgrade to Opus 4.7?
For enterprise leaders, Claude Opus 4.7 represents a shift from generative AI as a «creative assistant» to a «reliable operative.»
But importantly, it is not a «clean win» for every use case.
Instead, it is a decisive upgrade for teams building autonomous agents or complex software systems. The primary value proposition is the model’s new capability for self-verification and rigor; it no longer just generates an answer but creates internal tests to verify that the answer is correct before responding. This reliability makes it a superior choice for long-horizon engineering tasks where the cost of human supervision is the primary bottleneck.
However, an immediate, wholesale migration from Opus 4.6 requires caution. The model’s increased literalism in instruction following means that prompts engineered to be «loose» or conversational with previous versions may now produce unexpected or overly rigid results.
Furthermore, enterprises must prepare for a significant increase in operational costs. Opus 4.7 uses an updated tokenizer that can increase input token counts by 1.0–1.35x, and its tendency to «think harder» at high effort levels results in higher output token consumption.
For legacy applications where prompts are fragile and margins are thin, a phased rollout with significant re-tuning is recommended.
Where it puts Anthropic in the AI race
This release arrives at a paradoxical moment for Anthropic. Financially, the company is an undisputed juggernaut, with venture capital firms reportedly extending investment offers at a staggering $800 billion valuation—more than double its $380 billion Series G valuation from February 2026.
This momentum is fueled by explosive growth, with the company’s annual run-rate revenue skyrocketing to $30 billion in April 2026, driven largely by enterprise adoption and the success of Claude Code.
Yet, this commercial success is being contested by intense regulatory and technical friction. Anthropic is currently embroiled in a high-stakes legal battle with the U.S. Department of War (DoW), which recently labeled the company a «supply chain risk» after Anthropic refused to allow its models to be used for mass surveillance or fully autonomous lethal weapons.
While a San Francisco judge initially blocked the designation, a federal appeals panel recently denied Anthropic’s bid to stay the blacklisting, leaving the company excluded from lucrative defense contracts during an active military conflict.
Simultaneously, Anthropic is fending off a growing rebellion from its most loyal power users. Despite the company’s «market leader» status, developers have flooded GitHub and X with accusations of «AI shrinkflation,» claiming that the preceding Opus 4.6 model and Claude Code product have been quietly degraded.
Users report that recent versions are more prone to exploration loops, memory loss, and ignored instructions, leading some to describe the newly released Claude Code desktop app as «unpolished» and unbefitting a firm with a near-trillion-dollar valuation. Opus 4.7 is Anthropic’s attempt to silence these critics by proving that «deep thinking» can be paired with the rigorous execution that its enterprise clients now demand.
Ultimately, Opus 4.7 is a model defined by its discipline. In a market where models are often incentivized to be «helpful» to a fault—sometimes hallucinating answers to please the user—Opus 4.7 marks a return to rigor. By allowing users to control effort, set budgets, and verify outputs, Anthropic is moving closer to the goal of a truly autonomous digital labor force. For the engineering teams at Replit, Notion, and beyond, the shift from «watching the AI work» to «managing the AI’s results» has officially begun.

Anthropic is publicly releasing its most powerful large language model yet, Claude Opus 4.7, today — as it continues to keep an even more powerful successor, Mythos, restricted to a small number of external enterprise partners for cybersecurity testing and patching vulnerabilities in the software said enterprises use (which Mythos exposed rapidly).
The big headlines are that Opus 4.7 exceeds its most direct rivals — OpenAI’s GPT-5.4, released in early March 2026, scarcely more than a month ago; and Google’s latest flagship model Gemini 3.1 Pro from February — on key benchmarks including agentic coding, scaled tool-use, agentic computer use, and financial analysis.
But also, it’s notable how tight the race is getting: on directly comparable benchmarks, Opus 4.7 only leads GPT-5.4 by 7-4.
It currently leads the market on the GDPVal-AA knowledge work evaluation with an Elo score of 1753, surpassing both GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
Yet, the model does not represent a «clean sweep» across all categories.
Competitors like GPT-5.4 and Gemini 3.1 Pro still hold the lead in specific domains such as agentic search, where GPT-5.4 scores 89.3% compared to Opus 4.7’s 79.3%, as well as in multilingual Q&A and raw terminal-based coding.
This positioning defines Opus 4.7 not as a unilateral victor in all AI tasks, but as a specialized powerhouse optimized for the reliability and long-horizon autonomy required by the burgeoning agentic economy.
Claude Opus 4.7 is available today across all major cloud platforms, including Amazon Bedrock, Google Cloud’s Vertex AI, and Microsoft Foundry, with API pricing held steady at $5/$25 per million tokens.
Improvement in hard sciences and agentic workflows
Claude Opus 4.7 is a direct evolution of the Opus 4.6 architecture, but its performance delta is most visible in the «hard» sciences of agentic workflows: software engineering and complex document reasoning.
At its core, the model has been re-tuned to exhibit what Anthropic describes as «rigor». This isn’t just marketing parlance; it refers to the model’s new ability to devise its own verification steps before reporting a task as complete.
For example, in internal tests, the model was observed building a Rust-based text-to-speech engine from scratch and then independently feeding its own generated audio through a separate speech recognizer to verify the output against a Python reference.
This level of autonomous self-correction is designed to reduce the «hallucination loops» that often plague earlier iterations of agentic software.
The most significant architectural upgrade is the move to high-resolution multimodal support. Opus 4.7 can now process images up to 2,576 pixels on their longest edge—roughly 3.75 megapixels.
This represents a three-fold increase in resolution compared to previous iterations. For developers building «computer-use» agents that must navigate dense, high-DPI interfaces or for analysts extracting data from intricate technical diagrams, this change effectively removes the «blurry vision» ceiling that previously limited autonomous navigation.
This visual acuity is reflected in benchmarks from XBOW, where the model jumped from a 54.5% success rate in visual-acuity tests to 98.5%.
On the benchmark front, Opus 4.7 has claimed the top spot in several critical categories:
-
Knowledge Work (GDPVal-AA): It achieved an Elo score of 1753, notably outperforming GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
-
Agentic Coding (SWE-bench Pro): The model resolved 64.3% of tasks, compared to 53.4% for its predecessor.
-
Graduate-Level Reasoning (GPQA Diamond): It reached 94.2%, maintaining parity with the industry’s most advanced models while improving on its internal consistency.
-
Visual Reasoning (arXiv Reasoning): With tools, the model scored 91.0%, a meaningful jump from the 84.7% seen in Opus 4.6.
Crucially, Anthropic warns that this increased precision requires a shift in how users approach prompting. Opus 4.7 follows instructions literally. While older models might «read between the lines» and interpret ambiguous prompts loosely, Opus 4.7 executes the exact text provided. This means that legacy prompt libraries may require re-tuning to avoid unexpected results caused by the model’s strict adherence to the letter of the request.
Controlling the ‘thinking’ budget
The «agentic» nature of Opus 4.7—its tendency to pause, plan, and verify—comes with a trade-off in token consumption and latency.
To address this, Anthropic is introducing a new «effort» parameter. Users can now select an xhigh (extra high) effort level, positioned between high and max, allowing for more granular control over the depth of reasoning the model applies to a specific problem.
Internal data shows that while max effort yields the highest scores (approaching 75% on coding tasks), the xhigh setting provides a compelling sweet spot between performance and token expenditure.
To manage the costs associated with these more «thoughtful» runs, the Claude API is introducing «task budgets» in public beta. This allows developers to set a hard ceiling on token spend for autonomous agents, ensuring that a long-running debugging session doesn’t result in an unexpected bill.
These product changes signal a maturing market where AI is no longer a novelty but a production line item that requires fiscal and operational guardrails.
Furthermore, Opus 4.7 utilizes an updated tokenizer that improves text processing efficiency, though it can increase the token count of certain inputs by 1.0–1.35x.
Within the Claude Code environment, the update brings a new /ultrareview command. Unlike standard code reviews that look for syntax errors, /ultrareview is designed to simulate a senior human reviewer, flagging subtle design flaws and logic gaps.
Additionally, «auto mode»—a setting where Claude can make autonomous decisions without constant permission prompts—has been extended to Max plan users.
Licensing, safety, and the «cyber» divide
Anthropic continues to walk a narrow line regarding cybersecurity. The recent announcement of the aforementioend cybersecurity partnership around Mythos with external industry partners — known as «Project Glasswing» — highlighted the dual-use risks of high-capability models.
Consequently, while the flagship Mythos Preview model remains restricted, Opus 4.7 serves as the testbed for new automated safeguards. The model includes systems designed to detect and block requests that suggest high-risk cyberattacks, such as automated vulnerability exploitation.
To bridge the gap for the security industry, Anthropic is launching the Cyber Verification Program. This allows legitimate professionals—vulnerability researchers, penetration testers, and red-teamers—to apply for access to use Opus 4.7’s capabilities for defensive purposes.
This «verified user» model suggests a future where the most capable AI features are not universally available, but gated behind professional credentials and compliance frameworks.
In cybersecurity vulnerability reproduction (CyberGym), Opus 4.7 maintains a 73.1% success rate, trailing Mythos Preview’s 83.1% but leading GPT-5.4’s 66.3%.
Initial reactions from industry partners reveal quantifiable improvements in production enterprise workflows
Early testimonials from enterprise customers shared by Anthropic indicate there has been a tangible shift in model perception of Opus 4.7 from 4.6, going from «impressed by the tech» to «relying on the output».
Clarence Huang, VP of Technology at Intuit, noted that the model’s ability to «catch its own logical faults during the planning phase» is a game-changer for velocity.
This sentiment was echoed by Replit President Michele Catasta, who stated that the model achieved higher quality at a lower cost for tasks like log analysis and bug hunting, adding, «It really feels like a better coworker».
Other specific reactions included:
-
Cognition (Devin): CEO Scott Wu reported that Opus 4.7 can work coherently «for hours» and pushes through difficult problems that previously caused models to stall.
-
Notion: Sarah Sachs, AI Lead, highlighted a 14% improvement in multi-step workflows and a 66% reduction in tool-calling errors, making the agent feel like a «true teammate».
-
Factory Droids: Leo Tchourakov observed that the model carries work through to validation steps rather than «stopping halfway,» a common complaint with previous frontier models.
-
Harvey: Niko Grupen, Head of Applied Research, noted the model’s 90.9% score on BigLaw Bench, highlighting its «noticeably smarter handling of ambiguous document editing tasks».
Perhaps the most telling reaction came from Aj Orbach, CEO of a dashboard-building firm, who remarked on the model’s «design taste,» noting that its choices for data-rich interfaces were of a quality he would «actually ship».
Should enterprises immediately upgrade to Opus 4.7?
For enterprise leaders, Claude Opus 4.7 represents a shift from generative AI as a «creative assistant» to a «reliable operative.»
But importantly, it is not a «clean win» for every use case.
Instead, it is a decisive upgrade for teams building autonomous agents or complex software systems. The primary value proposition is the model’s new capability for self-verification and rigor; it no longer just generates an answer but creates internal tests to verify that the answer is correct before responding. This reliability makes it a superior choice for long-horizon engineering tasks where the cost of human supervision is the primary bottleneck.
However, an immediate, wholesale migration from Opus 4.6 requires caution. The model’s increased literalism in instruction following means that prompts engineered to be «loose» or conversational with previous versions may now produce unexpected or overly rigid results.
Furthermore, enterprises must prepare for a significant increase in operational costs. Opus 4.7 uses an updated tokenizer that can increase input token counts by 1.0–1.35x, and its tendency to «think harder» at high effort levels results in higher output token consumption.
For legacy applications where prompts are fragile and margins are thin, a phased rollout with significant re-tuning is recommended.
Where it puts Anthropic in the AI race
This release arrives at a paradoxical moment for Anthropic. Financially, the company is an undisputed juggernaut, with venture capital firms reportedly extending investment offers at a staggering $800 billion valuation—more than double its $380 billion Series G valuation from February 2026.
This momentum is fueled by explosive growth, with the company’s annual run-rate revenue skyrocketing to $30 billion in April 2026, driven largely by enterprise adoption and the success of Claude Code.
Yet, this commercial success is being contested by intense regulatory and technical friction. Anthropic is currently embroiled in a high-stakes legal battle with the U.S. Department of War (DoW), which recently labeled the company a «supply chain risk» after Anthropic refused to allow its models to be used for mass surveillance or fully autonomous lethal weapons.
While a San Francisco judge initially blocked the designation, a federal appeals panel recently denied Anthropic’s bid to stay the blacklisting, leaving the company excluded from lucrative defense contracts during an active military conflict.
Simultaneously, Anthropic is fending off a growing rebellion from its most loyal power users. Despite the company’s «market leader» status, developers have flooded GitHub and X with accusations of «AI shrinkflation,» claiming that the preceding Opus 4.6 model and Claude Code product have been quietly degraded.
Users report that recent versions are more prone to exploration loops, memory loss, and ignored instructions, leading some to describe the newly released Claude Code desktop app as «unpolished» and unbefitting a firm with a near-trillion-dollar valuation. Opus 4.7 is Anthropic’s attempt to silence these critics by proving that «deep thinking» can be paired with the rigorous execution that its enterprise clients now demand.
Ultimately, Opus 4.7 is a model defined by its discipline. In a market where models are often incentivized to be «helpful» to a fault—sometimes hallucinating answers to please the user—Opus 4.7 marks a return to rigor. By allowing users to control effort, set budgets, and verify outputs, Anthropic is moving closer to the goal of a truly autonomous digital labor force. For the engineering teams at Replit, Notion, and beyond, the shift from «watching the AI work» to «managing the AI’s results» has officially begun.
Anthropic is publicly releasing its most powerful large language model yet, Claude Opus 4.7, today — as it continues to keep an even more powerful successor, Mythos, restricted to a small number of external enterprise partners for cybersecurity testing and patching vulnerabilities in the software said enterprises use (which Mythos exposed rapidly).
The big headlines are that Opus 4.7 exceeds its most direct rivals — OpenAI’s GPT-5.4, released in early March 2026, scarcely more than a month ago; and Google’s latest flagship model Gemini 3.1 Pro from February — on key benchmarks including agentic coding, scaled tool-use, agentic computer use, and financial analysis.
But also, it’s notable how tight the race is getting: on directly comparable benchmarks, Opus 4.7 only leads GPT-5.4 by 7-4.
It currently leads the market on the GDPVal-AA knowledge work evaluation with an Elo score of 1753, surpassing both GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
Yet, the model does not represent a «clean sweep» across all categories.
Competitors like GPT-5.4 and Gemini 3.1 Pro still hold the lead in specific domains such as agentic search, where GPT-5.4 scores 89.3% compared to Opus 4.7’s 79.3%, as well as in multilingual Q&A and raw terminal-based coding.
This positioning defines Opus 4.7 not as a unilateral victor in all AI tasks, but as a specialized powerhouse optimized for the reliability and long-horizon autonomy required by the burgeoning agentic economy.
Claude Opus 4.7 is available today across all major cloud platforms, including Amazon Bedrock, Google Cloud’s Vertex AI, and Microsoft Foundry, with API pricing held steady at $5/$25 per million tokens.
Improvement in hard sciences and agentic workflows
Claude Opus 4.7 is a direct evolution of the Opus 4.6 architecture, but its performance delta is most visible in the «hard» sciences of agentic workflows: software engineering and complex document reasoning.
At its core, the model has been re-tuned to exhibit what Anthropic describes as «rigor». This isn’t just marketing parlance; it refers to the model’s new ability to devise its own verification steps before reporting a task as complete.
For example, in internal tests, the model was observed building a Rust-based text-to-speech engine from scratch and then independently feeding its own generated audio through a separate speech recognizer to verify the output against a Python reference.
This level of autonomous self-correction is designed to reduce the «hallucination loops» that often plague earlier iterations of agentic software.
The most significant architectural upgrade is the move to high-resolution multimodal support. Opus 4.7 can now process images up to 2,576 pixels on their longest edge—roughly 3.75 megapixels.
This represents a three-fold increase in resolution compared to previous iterations. For developers building «computer-use» agents that must navigate dense, high-DPI interfaces or for analysts extracting data from intricate technical diagrams, this change effectively removes the «blurry vision» ceiling that previously limited autonomous navigation.
This visual acuity is reflected in benchmarks from XBOW, where the model jumped from a 54.5% success rate in visual-acuity tests to 98.5%.
On the benchmark front, Opus 4.7 has claimed the top spot in several critical categories:
-
Knowledge Work (GDPVal-AA): It achieved an Elo score of 1753, notably outperforming GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
-
Agentic Coding (SWE-bench Pro): The model resolved 64.3% of tasks, compared to 53.4% for its predecessor.
-
Graduate-Level Reasoning (GPQA Diamond): It reached 94.2%, maintaining parity with the industry’s most advanced models while improving on its internal consistency.
-
Visual Reasoning (arXiv Reasoning): With tools, the model scored 91.0%, a meaningful jump from the 84.7% seen in Opus 4.6.
Crucially, Anthropic warns that this increased precision requires a shift in how users approach prompting. Opus 4.7 follows instructions literally. While older models might «read between the lines» and interpret ambiguous prompts loosely, Opus 4.7 executes the exact text provided. This means that legacy prompt libraries may require re-tuning to avoid unexpected results caused by the model’s strict adherence to the letter of the request.
Controlling the ‘thinking’ budget
The «agentic» nature of Opus 4.7—its tendency to pause, plan, and verify—comes with a trade-off in token consumption and latency.
To address this, Anthropic is introducing a new «effort» parameter. Users can now select an xhigh (extra high) effort level, positioned between high and max, allowing for more granular control over the depth of reasoning the model applies to a specific problem.
Internal data shows that while max effort yields the highest scores (approaching 75% on coding tasks), the xhigh setting provides a compelling sweet spot between performance and token expenditure.
To manage the costs associated with these more «thoughtful» runs, the Claude API is introducing «task budgets» in public beta. This allows developers to set a hard ceiling on token spend for autonomous agents, ensuring that a long-running debugging session doesn’t result in an unexpected bill.
These product changes signal a maturing market where AI is no longer a novelty but a production line item that requires fiscal and operational guardrails.
Furthermore, Opus 4.7 utilizes an updated tokenizer that improves text processing efficiency, though it can increase the token count of certain inputs by 1.0–1.35x.
Within the Claude Code environment, the update brings a new /ultrareview command. Unlike standard code reviews that look for syntax errors, /ultrareview is designed to simulate a senior human reviewer, flagging subtle design flaws and logic gaps.
Additionally, «auto mode»—a setting where Claude can make autonomous decisions without constant permission prompts—has been extended to Max plan users.
Licensing, safety, and the «cyber» divide
Anthropic continues to walk a narrow line regarding cybersecurity. The recent announcement of the aforementioend cybersecurity partnership around Mythos with external industry partners — known as «Project Glasswing» — highlighted the dual-use risks of high-capability models.
Consequently, while the flagship Mythos Preview model remains restricted, Opus 4.7 serves as the testbed for new automated safeguards. The model includes systems designed to detect and block requests that suggest high-risk cyberattacks, such as automated vulnerability exploitation.
To bridge the gap for the security industry, Anthropic is launching the Cyber Verification Program. This allows legitimate professionals—vulnerability researchers, penetration testers, and red-teamers—to apply for access to use Opus 4.7’s capabilities for defensive purposes.
This «verified user» model suggests a future where the most capable AI features are not universally available, but gated behind professional credentials and compliance frameworks.
In cybersecurity vulnerability reproduction (CyberGym), Opus 4.7 maintains a 73.1% success rate, trailing Mythos Preview’s 83.1% but leading GPT-5.4’s 66.3%.
Initial reactions from industry partners reveal quantifiable improvements in production enterprise workflows
Early testimonials from enterprise customers shared by Anthropic indicate there has been a tangible shift in model perception of Opus 4.7 from 4.6, going from «impressed by the tech» to «relying on the output».
Clarence Huang, VP of Technology at Intuit, noted that the model’s ability to «catch its own logical faults during the planning phase» is a game-changer for velocity.
This sentiment was echoed by Replit President Michele Catasta, who stated that the model achieved higher quality at a lower cost for tasks like log analysis and bug hunting, adding, «It really feels like a better coworker».
Other specific reactions included:
-
Cognition (Devin): CEO Scott Wu reported that Opus 4.7 can work coherently «for hours» and pushes through difficult problems that previously caused models to stall.
-
Notion: Sarah Sachs, AI Lead, highlighted a 14% improvement in multi-step workflows and a 66% reduction in tool-calling errors, making the agent feel like a «true teammate».
-
Factory Droids: Leo Tchourakov observed that the model carries work through to validation steps rather than «stopping halfway,» a common complaint with previous frontier models.
-
Harvey: Niko Grupen, Head of Applied Research, noted the model’s 90.9% score on BigLaw Bench, highlighting its «noticeably smarter handling of ambiguous document editing tasks».
Perhaps the most telling reaction came from Aj Orbach, CEO of a dashboard-building firm, who remarked on the model’s «design taste,» noting that its choices for data-rich interfaces were of a quality he would «actually ship».
Should enterprises immediately upgrade to Opus 4.7?
For enterprise leaders, Claude Opus 4.7 represents a shift from generative AI as a «creative assistant» to a «reliable operative.»
But importantly, it is not a «clean win» for every use case.
Instead, it is a decisive upgrade for teams building autonomous agents or complex software systems. The primary value proposition is the model’s new capability for self-verification and rigor; it no longer just generates an answer but creates internal tests to verify that the answer is correct before responding. This reliability makes it a superior choice for long-horizon engineering tasks where the cost of human supervision is the primary bottleneck.
However, an immediate, wholesale migration from Opus 4.6 requires caution. The model’s increased literalism in instruction following means that prompts engineered to be «loose» or conversational with previous versions may now produce unexpected or overly rigid results.
Furthermore, enterprises must prepare for a significant increase in operational costs. Opus 4.7 uses an updated tokenizer that can increase input token counts by 1.0–1.35x, and its tendency to «think harder» at high effort levels results in higher output token consumption.
For legacy applications where prompts are fragile and margins are thin, a phased rollout with significant re-tuning is recommended.
Where it puts Anthropic in the AI race
This release arrives at a paradoxical moment for Anthropic. Financially, the company is an undisputed juggernaut, with venture capital firms reportedly extending investment offers at a staggering $800 billion valuation—more than double its $380 billion Series G valuation from February 2026.
This momentum is fueled by explosive growth, with the company’s annual run-rate revenue skyrocketing to $30 billion in April 2026, driven largely by enterprise adoption and the success of Claude Code.
Yet, this commercial success is being contested by intense regulatory and technical friction. Anthropic is currently embroiled in a high-stakes legal battle with the U.S. Department of War (DoW), which recently labeled the company a «supply chain risk» after Anthropic refused to allow its models to be used for mass surveillance or fully autonomous lethal weapons.
While a San Francisco judge initially blocked the designation, a federal appeals panel recently denied Anthropic’s bid to stay the blacklisting, leaving the company excluded from lucrative defense contracts during an active military conflict.
Simultaneously, Anthropic is fending off a growing rebellion from its most loyal power users. Despite the company’s «market leader» status, developers have flooded GitHub and X with accusations of «AI shrinkflation,» claiming that the preceding Opus 4.6 model and Claude Code product have been quietly degraded.
Users report that recent versions are more prone to exploration loops, memory loss, and ignored instructions, leading some to describe the newly released Claude Code desktop app as «unpolished» and unbefitting a firm with a near-trillion-dollar valuation. Opus 4.7 is Anthropic’s attempt to silence these critics by proving that «deep thinking» can be paired with the rigorous execution that its enterprise clients now demand.
Ultimately, Opus 4.7 is a model defined by its discipline. In a market where models are often incentivized to be «helpful» to a fault—sometimes hallucinating answers to please the user—Opus 4.7 marks a return to rigor. By allowing users to control effort, set budgets, and verify outputs, Anthropic is moving closer to the goal of a truly autonomous digital labor force. For the engineering teams at Replit, Notion, and beyond, the shift from «watching the AI work» to «managing the AI’s results» has officially begun.
Suscríbete y recibe las historias más importantes del día.
Al suscribirte aceptas nuestros términos y condiciones y política de privacidad.
Anthropic is publicly releasing its most powerful large language model yet, Claude Opus 4.7, today — as it continues to keep an even more powerful successor, Mythos, restricted to a small number of external enterprise partners for cybersecurity testing and patching vulnerabilities in the software said enterprises use (which Mythos exposed rapidly).
The big headlines are that Opus 4.7 exceeds its most direct rivals — OpenAI’s GPT-5.4, released in early March 2026, scarcely more than a month ago; and Google’s latest flagship model Gemini 3.1 Pro from February — on key benchmarks including agentic coding, scaled tool-use, agentic computer use, and financial analysis.
But also, it’s notable how tight the race is getting: on directly comparable benchmarks, Opus 4.7 only leads GPT-5.4 by 7-4.
It currently leads the market on the GDPVal-AA knowledge work evaluation with an Elo score of 1753, surpassing both GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
Yet, the model does not represent a «clean sweep» across all categories.
Competitors like GPT-5.4 and Gemini 3.1 Pro still hold the lead in specific domains such as agentic search, where GPT-5.4 scores 89.3% compared to Opus 4.7’s 79.3%, as well as in multilingual Q&A and raw terminal-based coding.
This positioning defines Opus 4.7 not as a unilateral victor in all AI tasks, but as a specialized powerhouse optimized for the reliability and long-horizon autonomy required by the burgeoning agentic economy.
Claude Opus 4.7 is available today across all major cloud platforms, including Amazon Bedrock, Google Cloud’s Vertex AI, and Microsoft Foundry, with API pricing held steady at $5/$25 per million tokens.
Improvement in hard sciences and agentic workflows
Claude Opus 4.7 is a direct evolution of the Opus 4.6 architecture, but its performance delta is most visible in the «hard» sciences of agentic workflows: software engineering and complex document reasoning.
At its core, the model has been re-tuned to exhibit what Anthropic describes as «rigor». This isn’t just marketing parlance; it refers to the model’s new ability to devise its own verification steps before reporting a task as complete.
For example, in internal tests, the model was observed building a Rust-based text-to-speech engine from scratch and then independently feeding its own generated audio through a separate speech recognizer to verify the output against a Python reference.
This level of autonomous self-correction is designed to reduce the «hallucination loops» that often plague earlier iterations of agentic software.
The most significant architectural upgrade is the move to high-resolution multimodal support. Opus 4.7 can now process images up to 2,576 pixels on their longest edge—roughly 3.75 megapixels.
This represents a three-fold increase in resolution compared to previous iterations. For developers building «computer-use» agents that must navigate dense, high-DPI interfaces or for analysts extracting data from intricate technical diagrams, this change effectively removes the «blurry vision» ceiling that previously limited autonomous navigation.
This visual acuity is reflected in benchmarks from XBOW, where the model jumped from a 54.5% success rate in visual-acuity tests to 98.5%.
On the benchmark front, Opus 4.7 has claimed the top spot in several critical categories:
-
Knowledge Work (GDPVal-AA): It achieved an Elo score of 1753, notably outperforming GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
-
Agentic Coding (SWE-bench Pro): The model resolved 64.3% of tasks, compared to 53.4% for its predecessor.
-
Graduate-Level Reasoning (GPQA Diamond): It reached 94.2%, maintaining parity with the industry’s most advanced models while improving on its internal consistency.
-
Visual Reasoning (arXiv Reasoning): With tools, the model scored 91.0%, a meaningful jump from the 84.7% seen in Opus 4.6.
Crucially, Anthropic warns that this increased precision requires a shift in how users approach prompting. Opus 4.7 follows instructions literally. While older models might «read between the lines» and interpret ambiguous prompts loosely, Opus 4.7 executes the exact text provided. This means that legacy prompt libraries may require re-tuning to avoid unexpected results caused by the model’s strict adherence to the letter of the request.
Controlling the ‘thinking’ budget
The «agentic» nature of Opus 4.7—its tendency to pause, plan, and verify—comes with a trade-off in token consumption and latency.
To address this, Anthropic is introducing a new «effort» parameter. Users can now select an xhigh (extra high) effort level, positioned between high and max, allowing for more granular control over the depth of reasoning the model applies to a specific problem.
Internal data shows that while max effort yields the highest scores (approaching 75% on coding tasks), the xhigh setting provides a compelling sweet spot between performance and token expenditure.
To manage the costs associated with these more «thoughtful» runs, the Claude API is introducing «task budgets» in public beta. This allows developers to set a hard ceiling on token spend for autonomous agents, ensuring that a long-running debugging session doesn’t result in an unexpected bill.
These product changes signal a maturing market where AI is no longer a novelty but a production line item that requires fiscal and operational guardrails.
Furthermore, Opus 4.7 utilizes an updated tokenizer that improves text processing efficiency, though it can increase the token count of certain inputs by 1.0–1.35x.
Within the Claude Code environment, the update brings a new /ultrareview command. Unlike standard code reviews that look for syntax errors, /ultrareview is designed to simulate a senior human reviewer, flagging subtle design flaws and logic gaps.
Additionally, «auto mode»—a setting where Claude can make autonomous decisions without constant permission prompts—has been extended to Max plan users.
Licensing, safety, and the «cyber» divide
Anthropic continues to walk a narrow line regarding cybersecurity. The recent announcement of the aforementioend cybersecurity partnership around Mythos with external industry partners — known as «Project Glasswing» — highlighted the dual-use risks of high-capability models.
Consequently, while the flagship Mythos Preview model remains restricted, Opus 4.7 serves as the testbed for new automated safeguards. The model includes systems designed to detect and block requests that suggest high-risk cyberattacks, such as automated vulnerability exploitation.
To bridge the gap for the security industry, Anthropic is launching the Cyber Verification Program. This allows legitimate professionals—vulnerability researchers, penetration testers, and red-teamers—to apply for access to use Opus 4.7’s capabilities for defensive purposes.
This «verified user» model suggests a future where the most capable AI features are not universally available, but gated behind professional credentials and compliance frameworks.
In cybersecurity vulnerability reproduction (CyberGym), Opus 4.7 maintains a 73.1% success rate, trailing Mythos Preview’s 83.1% but leading GPT-5.4’s 66.3%.
Initial reactions from industry partners reveal quantifiable improvements in production enterprise workflows
Early testimonials from enterprise customers shared by Anthropic indicate there has been a tangible shift in model perception of Opus 4.7 from 4.6, going from «impressed by the tech» to «relying on the output».
Clarence Huang, VP of Technology at Intuit, noted that the model’s ability to «catch its own logical faults during the planning phase» is a game-changer for velocity.
This sentiment was echoed by Replit President Michele Catasta, who stated that the model achieved higher quality at a lower cost for tasks like log analysis and bug hunting, adding, «It really feels like a better coworker».
Other specific reactions included:
-
Cognition (Devin): CEO Scott Wu reported that Opus 4.7 can work coherently «for hours» and pushes through difficult problems that previously caused models to stall.
-
Notion: Sarah Sachs, AI Lead, highlighted a 14% improvement in multi-step workflows and a 66% reduction in tool-calling errors, making the agent feel like a «true teammate».
-
Factory Droids: Leo Tchourakov observed that the model carries work through to validation steps rather than «stopping halfway,» a common complaint with previous frontier models.
-
Harvey: Niko Grupen, Head of Applied Research, noted the model’s 90.9% score on BigLaw Bench, highlighting its «noticeably smarter handling of ambiguous document editing tasks».
Perhaps the most telling reaction came from Aj Orbach, CEO of a dashboard-building firm, who remarked on the model’s «design taste,» noting that its choices for data-rich interfaces were of a quality he would «actually ship».
Should enterprises immediately upgrade to Opus 4.7?
For enterprise leaders, Claude Opus 4.7 represents a shift from generative AI as a «creative assistant» to a «reliable operative.»
But importantly, it is not a «clean win» for every use case.
Instead, it is a decisive upgrade for teams building autonomous agents or complex software systems. The primary value proposition is the model’s new capability for self-verification and rigor; it no longer just generates an answer but creates internal tests to verify that the answer is correct before responding. This reliability makes it a superior choice for long-horizon engineering tasks where the cost of human supervision is the primary bottleneck.
However, an immediate, wholesale migration from Opus 4.6 requires caution. The model’s increased literalism in instruction following means that prompts engineered to be «loose» or conversational with previous versions may now produce unexpected or overly rigid results.
Furthermore, enterprises must prepare for a significant increase in operational costs. Opus 4.7 uses an updated tokenizer that can increase input token counts by 1.0–1.35x, and its tendency to «think harder» at high effort levels results in higher output token consumption.
For legacy applications where prompts are fragile and margins are thin, a phased rollout with significant re-tuning is recommended.
Where it puts Anthropic in the AI race
This release arrives at a paradoxical moment for Anthropic. Financially, the company is an undisputed juggernaut, with venture capital firms reportedly extending investment offers at a staggering $800 billion valuation—more than double its $380 billion Series G valuation from February 2026.
This momentum is fueled by explosive growth, with the company’s annual run-rate revenue skyrocketing to $30 billion in April 2026, driven largely by enterprise adoption and the success of Claude Code.
Yet, this commercial success is being contested by intense regulatory and technical friction. Anthropic is currently embroiled in a high-stakes legal battle with the U.S. Department of War (DoW), which recently labeled the company a «supply chain risk» after Anthropic refused to allow its models to be used for mass surveillance or fully autonomous lethal weapons.
While a San Francisco judge initially blocked the designation, a federal appeals panel recently denied Anthropic’s bid to stay the blacklisting, leaving the company excluded from lucrative defense contracts during an active military conflict.
Simultaneously, Anthropic is fending off a growing rebellion from its most loyal power users. Despite the company’s «market leader» status, developers have flooded GitHub and X with accusations of «AI shrinkflation,» claiming that the preceding Opus 4.6 model and Claude Code product have been quietly degraded.
Users report that recent versions are more prone to exploration loops, memory loss, and ignored instructions, leading some to describe the newly released Claude Code desktop app as «unpolished» and unbefitting a firm with a near-trillion-dollar valuation. Opus 4.7 is Anthropic’s attempt to silence these critics by proving that «deep thinking» can be paired with the rigorous execution that its enterprise clients now demand.
Ultimately, Opus 4.7 is a model defined by its discipline. In a market where models are often incentivized to be «helpful» to a fault—sometimes hallucinating answers to please the user—Opus 4.7 marks a return to rigor. By allowing users to control effort, set budgets, and verify outputs, Anthropic is moving closer to the goal of a truly autonomous digital labor force. For the engineering teams at Replit, Notion, and beyond, the shift from «watching the AI work» to «managing the AI’s results» has officially begun.
Anthropic is publicly releasing its most powerful large language model yet, Claude Opus 4.7, today — as it continues to keep an even more powerful successor, Mythos, restricted to a small number of external enterprise partners for cybersecurity testing and patching vulnerabilities in the software said enterprises use (which Mythos exposed rapidly).
The big headlines are that Opus 4.7 exceeds its most direct rivals — OpenAI’s GPT-5.4, released in early March 2026, scarcely more than a month ago; and Google’s latest flagship model Gemini 3.1 Pro from February — on key benchmarks including agentic coding, scaled tool-use, agentic computer use, and financial analysis.
But also, it’s notable how tight the race is getting: on directly comparable benchmarks, Opus 4.7 only leads GPT-5.4 by 7-4.
It currently leads the market on the GDPVal-AA knowledge work evaluation with an Elo score of 1753, surpassing both GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
Yet, the model does not represent a «clean sweep» across all categories.
Competitors like GPT-5.4 and Gemini 3.1 Pro still hold the lead in specific domains such as agentic search, where GPT-5.4 scores 89.3% compared to Opus 4.7’s 79.3%, as well as in multilingual Q&A and raw terminal-based coding.
This positioning defines Opus 4.7 not as a unilateral victor in all AI tasks, but as a specialized powerhouse optimized for the reliability and long-horizon autonomy required by the burgeoning agentic economy.
Claude Opus 4.7 is available today across all major cloud platforms, including Amazon Bedrock, Google Cloud’s Vertex AI, and Microsoft Foundry, with API pricing held steady at $5/$25 per million tokens.
Improvement in hard sciences and agentic workflows
Claude Opus 4.7 is a direct evolution of the Opus 4.6 architecture, but its performance delta is most visible in the «hard» sciences of agentic workflows: software engineering and complex document reasoning.
At its core, the model has been re-tuned to exhibit what Anthropic describes as «rigor». This isn’t just marketing parlance; it refers to the model’s new ability to devise its own verification steps before reporting a task as complete.
For example, in internal tests, the model was observed building a Rust-based text-to-speech engine from scratch and then independently feeding its own generated audio through a separate speech recognizer to verify the output against a Python reference.
This level of autonomous self-correction is designed to reduce the «hallucination loops» that often plague earlier iterations of agentic software.
The most significant architectural upgrade is the move to high-resolution multimodal support. Opus 4.7 can now process images up to 2,576 pixels on their longest edge—roughly 3.75 megapixels.
This represents a three-fold increase in resolution compared to previous iterations. For developers building «computer-use» agents that must navigate dense, high-DPI interfaces or for analysts extracting data from intricate technical diagrams, this change effectively removes the «blurry vision» ceiling that previously limited autonomous navigation.
This visual acuity is reflected in benchmarks from XBOW, where the model jumped from a 54.5% success rate in visual-acuity tests to 98.5%.
On the benchmark front, Opus 4.7 has claimed the top spot in several critical categories:
-
Knowledge Work (GDPVal-AA): It achieved an Elo score of 1753, notably outperforming GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
-
Agentic Coding (SWE-bench Pro): The model resolved 64.3% of tasks, compared to 53.4% for its predecessor.
-
Graduate-Level Reasoning (GPQA Diamond): It reached 94.2%, maintaining parity with the industry’s most advanced models while improving on its internal consistency.
-
Visual Reasoning (arXiv Reasoning): With tools, the model scored 91.0%, a meaningful jump from the 84.7% seen in Opus 4.6.
Crucially, Anthropic warns that this increased precision requires a shift in how users approach prompting. Opus 4.7 follows instructions literally. While older models might «read between the lines» and interpret ambiguous prompts loosely, Opus 4.7 executes the exact text provided. This means that legacy prompt libraries may require re-tuning to avoid unexpected results caused by the model’s strict adherence to the letter of the request.
Controlling the ‘thinking’ budget
The «agentic» nature of Opus 4.7—its tendency to pause, plan, and verify—comes with a trade-off in token consumption and latency.
To address this, Anthropic is introducing a new «effort» parameter. Users can now select an xhigh (extra high) effort level, positioned between high and max, allowing for more granular control over the depth of reasoning the model applies to a specific problem.
Internal data shows that while max effort yields the highest scores (approaching 75% on coding tasks), the xhigh setting provides a compelling sweet spot between performance and token expenditure.
To manage the costs associated with these more «thoughtful» runs, the Claude API is introducing «task budgets» in public beta. This allows developers to set a hard ceiling on token spend for autonomous agents, ensuring that a long-running debugging session doesn’t result in an unexpected bill.
These product changes signal a maturing market where AI is no longer a novelty but a production line item that requires fiscal and operational guardrails.
Furthermore, Opus 4.7 utilizes an updated tokenizer that improves text processing efficiency, though it can increase the token count of certain inputs by 1.0–1.35x.
Within the Claude Code environment, the update brings a new /ultrareview command. Unlike standard code reviews that look for syntax errors, /ultrareview is designed to simulate a senior human reviewer, flagging subtle design flaws and logic gaps.
Additionally, «auto mode»—a setting where Claude can make autonomous decisions without constant permission prompts—has been extended to Max plan users.
Licensing, safety, and the «cyber» divide
Anthropic continues to walk a narrow line regarding cybersecurity. The recent announcement of the aforementioend cybersecurity partnership around Mythos with external industry partners — known as «Project Glasswing» — highlighted the dual-use risks of high-capability models.
Consequently, while the flagship Mythos Preview model remains restricted, Opus 4.7 serves as the testbed for new automated safeguards. The model includes systems designed to detect and block requests that suggest high-risk cyberattacks, such as automated vulnerability exploitation.
To bridge the gap for the security industry, Anthropic is launching the Cyber Verification Program. This allows legitimate professionals—vulnerability researchers, penetration testers, and red-teamers—to apply for access to use Opus 4.7’s capabilities for defensive purposes.
This «verified user» model suggests a future where the most capable AI features are not universally available, but gated behind professional credentials and compliance frameworks.
In cybersecurity vulnerability reproduction (CyberGym), Opus 4.7 maintains a 73.1% success rate, trailing Mythos Preview’s 83.1% but leading GPT-5.4’s 66.3%.
Initial reactions from industry partners reveal quantifiable improvements in production enterprise workflows
Early testimonials from enterprise customers shared by Anthropic indicate there has been a tangible shift in model perception of Opus 4.7 from 4.6, going from «impressed by the tech» to «relying on the output».
Clarence Huang, VP of Technology at Intuit, noted that the model’s ability to «catch its own logical faults during the planning phase» is a game-changer for velocity.
This sentiment was echoed by Replit President Michele Catasta, who stated that the model achieved higher quality at a lower cost for tasks like log analysis and bug hunting, adding, «It really feels like a better coworker».
Other specific reactions included:
-
Cognition (Devin): CEO Scott Wu reported that Opus 4.7 can work coherently «for hours» and pushes through difficult problems that previously caused models to stall.
-
Notion: Sarah Sachs, AI Lead, highlighted a 14% improvement in multi-step workflows and a 66% reduction in tool-calling errors, making the agent feel like a «true teammate».
-
Factory Droids: Leo Tchourakov observed that the model carries work through to validation steps rather than «stopping halfway,» a common complaint with previous frontier models.
-
Harvey: Niko Grupen, Head of Applied Research, noted the model’s 90.9% score on BigLaw Bench, highlighting its «noticeably smarter handling of ambiguous document editing tasks».
Perhaps the most telling reaction came from Aj Orbach, CEO of a dashboard-building firm, who remarked on the model’s «design taste,» noting that its choices for data-rich interfaces were of a quality he would «actually ship».
Should enterprises immediately upgrade to Opus 4.7?
For enterprise leaders, Claude Opus 4.7 represents a shift from generative AI as a «creative assistant» to a «reliable operative.»
But importantly, it is not a «clean win» for every use case.
Instead, it is a decisive upgrade for teams building autonomous agents or complex software systems. The primary value proposition is the model’s new capability for self-verification and rigor; it no longer just generates an answer but creates internal tests to verify that the answer is correct before responding. This reliability makes it a superior choice for long-horizon engineering tasks where the cost of human supervision is the primary bottleneck.
However, an immediate, wholesale migration from Opus 4.6 requires caution. The model’s increased literalism in instruction following means that prompts engineered to be «loose» or conversational with previous versions may now produce unexpected or overly rigid results.
Furthermore, enterprises must prepare for a significant increase in operational costs. Opus 4.7 uses an updated tokenizer that can increase input token counts by 1.0–1.35x, and its tendency to «think harder» at high effort levels results in higher output token consumption.
For legacy applications where prompts are fragile and margins are thin, a phased rollout with significant re-tuning is recommended.
Where it puts Anthropic in the AI race
This release arrives at a paradoxical moment for Anthropic. Financially, the company is an undisputed juggernaut, with venture capital firms reportedly extending investment offers at a staggering $800 billion valuation—more than double its $380 billion Series G valuation from February 2026.
This momentum is fueled by explosive growth, with the company’s annual run-rate revenue skyrocketing to $30 billion in April 2026, driven largely by enterprise adoption and the success of Claude Code.
Yet, this commercial success is being contested by intense regulatory and technical friction. Anthropic is currently embroiled in a high-stakes legal battle with the U.S. Department of War (DoW), which recently labeled the company a «supply chain risk» after Anthropic refused to allow its models to be used for mass surveillance or fully autonomous lethal weapons.
While a San Francisco judge initially blocked the designation, a federal appeals panel recently denied Anthropic’s bid to stay the blacklisting, leaving the company excluded from lucrative defense contracts during an active military conflict.
Simultaneously, Anthropic is fending off a growing rebellion from its most loyal power users. Despite the company’s «market leader» status, developers have flooded GitHub and X with accusations of «AI shrinkflation,» claiming that the preceding Opus 4.6 model and Claude Code product have been quietly degraded.
Users report that recent versions are more prone to exploration loops, memory loss, and ignored instructions, leading some to describe the newly released Claude Code desktop app as «unpolished» and unbefitting a firm with a near-trillion-dollar valuation. Opus 4.7 is Anthropic’s attempt to silence these critics by proving that «deep thinking» can be paired with the rigorous execution that its enterprise clients now demand.
Ultimately, Opus 4.7 is a model defined by its discipline. In a market where models are often incentivized to be «helpful» to a fault—sometimes hallucinating answers to please the user—Opus 4.7 marks a return to rigor. By allowing users to control effort, set budgets, and verify outputs, Anthropic is moving closer to the goal of a truly autonomous digital labor force. For the engineering teams at Replit, Notion, and beyond, the shift from «watching the AI work» to «managing the AI’s results» has officially begun.
Anthropic is publicly releasing its most powerful large language model yet, Claude Opus 4.7, today — as it continues to keep an even more powerful successor, Mythos, restricted to a small number of external enterprise partners for cybersecurity testing and patching vulnerabilities in the software said enterprises use (which Mythos exposed rapidly).
The big headlines are that Opus 4.7 exceeds its most direct rivals — OpenAI’s GPT-5.4, released in early March 2026, scarcely more than a month ago; and Google’s latest flagship model Gemini 3.1 Pro from February — on key benchmarks including agentic coding, scaled tool-use, agentic computer use, and financial analysis.
But also, it’s notable how tight the race is getting: on directly comparable benchmarks, Opus 4.7 only leads GPT-5.4 by 7-4.
It currently leads the market on the GDPVal-AA knowledge work evaluation with an Elo score of 1753, surpassing both GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
Yet, the model does not represent a «clean sweep» across all categories.
Competitors like GPT-5.4 and Gemini 3.1 Pro still hold the lead in specific domains such as agentic search, where GPT-5.4 scores 89.3% compared to Opus 4.7’s 79.3%, as well as in multilingual Q&A and raw terminal-based coding.
This positioning defines Opus 4.7 not as a unilateral victor in all AI tasks, but as a specialized powerhouse optimized for the reliability and long-horizon autonomy required by the burgeoning agentic economy.
Claude Opus 4.7 is available today across all major cloud platforms, including Amazon Bedrock, Google Cloud’s Vertex AI, and Microsoft Foundry, with API pricing held steady at $5/$25 per million tokens.
Improvement in hard sciences and agentic workflows
Claude Opus 4.7 is a direct evolution of the Opus 4.6 architecture, but its performance delta is most visible in the «hard» sciences of agentic workflows: software engineering and complex document reasoning.
At its core, the model has been re-tuned to exhibit what Anthropic describes as «rigor». This isn’t just marketing parlance; it refers to the model’s new ability to devise its own verification steps before reporting a task as complete.
For example, in internal tests, the model was observed building a Rust-based text-to-speech engine from scratch and then independently feeding its own generated audio through a separate speech recognizer to verify the output against a Python reference.
This level of autonomous self-correction is designed to reduce the «hallucination loops» that often plague earlier iterations of agentic software.
The most significant architectural upgrade is the move to high-resolution multimodal support. Opus 4.7 can now process images up to 2,576 pixels on their longest edge—roughly 3.75 megapixels.
This represents a three-fold increase in resolution compared to previous iterations. For developers building «computer-use» agents that must navigate dense, high-DPI interfaces or for analysts extracting data from intricate technical diagrams, this change effectively removes the «blurry vision» ceiling that previously limited autonomous navigation.
This visual acuity is reflected in benchmarks from XBOW, where the model jumped from a 54.5% success rate in visual-acuity tests to 98.5%.
On the benchmark front, Opus 4.7 has claimed the top spot in several critical categories:
-
Knowledge Work (GDPVal-AA): It achieved an Elo score of 1753, notably outperforming GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
-
Agentic Coding (SWE-bench Pro): The model resolved 64.3% of tasks, compared to 53.4% for its predecessor.
-
Graduate-Level Reasoning (GPQA Diamond): It reached 94.2%, maintaining parity with the industry’s most advanced models while improving on its internal consistency.
-
Visual Reasoning (arXiv Reasoning): With tools, the model scored 91.0%, a meaningful jump from the 84.7% seen in Opus 4.6.
Crucially, Anthropic warns that this increased precision requires a shift in how users approach prompting. Opus 4.7 follows instructions literally. While older models might «read between the lines» and interpret ambiguous prompts loosely, Opus 4.7 executes the exact text provided. This means that legacy prompt libraries may require re-tuning to avoid unexpected results caused by the model’s strict adherence to the letter of the request.
Controlling the ‘thinking’ budget
The «agentic» nature of Opus 4.7—its tendency to pause, plan, and verify—comes with a trade-off in token consumption and latency.
To address this, Anthropic is introducing a new «effort» parameter. Users can now select an xhigh (extra high) effort level, positioned between high and max, allowing for more granular control over the depth of reasoning the model applies to a specific problem.
Internal data shows that while max effort yields the highest scores (approaching 75% on coding tasks), the xhigh setting provides a compelling sweet spot between performance and token expenditure.
To manage the costs associated with these more «thoughtful» runs, the Claude API is introducing «task budgets» in public beta. This allows developers to set a hard ceiling on token spend for autonomous agents, ensuring that a long-running debugging session doesn’t result in an unexpected bill.
These product changes signal a maturing market where AI is no longer a novelty but a production line item that requires fiscal and operational guardrails.
Furthermore, Opus 4.7 utilizes an updated tokenizer that improves text processing efficiency, though it can increase the token count of certain inputs by 1.0–1.35x.
Within the Claude Code environment, the update brings a new /ultrareview command. Unlike standard code reviews that look for syntax errors, /ultrareview is designed to simulate a senior human reviewer, flagging subtle design flaws and logic gaps.
Additionally, «auto mode»—a setting where Claude can make autonomous decisions without constant permission prompts—has been extended to Max plan users.
Licensing, safety, and the «cyber» divide
Anthropic continues to walk a narrow line regarding cybersecurity. The recent announcement of the aforementioend cybersecurity partnership around Mythos with external industry partners — known as «Project Glasswing» — highlighted the dual-use risks of high-capability models.
Consequently, while the flagship Mythos Preview model remains restricted, Opus 4.7 serves as the testbed for new automated safeguards. The model includes systems designed to detect and block requests that suggest high-risk cyberattacks, such as automated vulnerability exploitation.
To bridge the gap for the security industry, Anthropic is launching the Cyber Verification Program. This allows legitimate professionals—vulnerability researchers, penetration testers, and red-teamers—to apply for access to use Opus 4.7’s capabilities for defensive purposes.
This «verified user» model suggests a future where the most capable AI features are not universally available, but gated behind professional credentials and compliance frameworks.
In cybersecurity vulnerability reproduction (CyberGym), Opus 4.7 maintains a 73.1% success rate, trailing Mythos Preview’s 83.1% but leading GPT-5.4’s 66.3%.
Initial reactions from industry partners reveal quantifiable improvements in production enterprise workflows
Early testimonials from enterprise customers shared by Anthropic indicate there has been a tangible shift in model perception of Opus 4.7 from 4.6, going from «impressed by the tech» to «relying on the output».
Clarence Huang, VP of Technology at Intuit, noted that the model’s ability to «catch its own logical faults during the planning phase» is a game-changer for velocity.
This sentiment was echoed by Replit President Michele Catasta, who stated that the model achieved higher quality at a lower cost for tasks like log analysis and bug hunting, adding, «It really feels like a better coworker».
Other specific reactions included:
-
Cognition (Devin): CEO Scott Wu reported that Opus 4.7 can work coherently «for hours» and pushes through difficult problems that previously caused models to stall.
-
Notion: Sarah Sachs, AI Lead, highlighted a 14% improvement in multi-step workflows and a 66% reduction in tool-calling errors, making the agent feel like a «true teammate».
-
Factory Droids: Leo Tchourakov observed that the model carries work through to validation steps rather than «stopping halfway,» a common complaint with previous frontier models.
-
Harvey: Niko Grupen, Head of Applied Research, noted the model’s 90.9% score on BigLaw Bench, highlighting its «noticeably smarter handling of ambiguous document editing tasks».
Perhaps the most telling reaction came from Aj Orbach, CEO of a dashboard-building firm, who remarked on the model’s «design taste,» noting that its choices for data-rich interfaces were of a quality he would «actually ship».
Should enterprises immediately upgrade to Opus 4.7?
For enterprise leaders, Claude Opus 4.7 represents a shift from generative AI as a «creative assistant» to a «reliable operative.»
But importantly, it is not a «clean win» for every use case.
Instead, it is a decisive upgrade for teams building autonomous agents or complex software systems. The primary value proposition is the model’s new capability for self-verification and rigor; it no longer just generates an answer but creates internal tests to verify that the answer is correct before responding. This reliability makes it a superior choice for long-horizon engineering tasks where the cost of human supervision is the primary bottleneck.
However, an immediate, wholesale migration from Opus 4.6 requires caution. The model’s increased literalism in instruction following means that prompts engineered to be «loose» or conversational with previous versions may now produce unexpected or overly rigid results.
Furthermore, enterprises must prepare for a significant increase in operational costs. Opus 4.7 uses an updated tokenizer that can increase input token counts by 1.0–1.35x, and its tendency to «think harder» at high effort levels results in higher output token consumption.
For legacy applications where prompts are fragile and margins are thin, a phased rollout with significant re-tuning is recommended.
Where it puts Anthropic in the AI race
This release arrives at a paradoxical moment for Anthropic. Financially, the company is an undisputed juggernaut, with venture capital firms reportedly extending investment offers at a staggering $800 billion valuation—more than double its $380 billion Series G valuation from February 2026.
This momentum is fueled by explosive growth, with the company’s annual run-rate revenue skyrocketing to $30 billion in April 2026, driven largely by enterprise adoption and the success of Claude Code.
Yet, this commercial success is being contested by intense regulatory and technical friction. Anthropic is currently embroiled in a high-stakes legal battle with the U.S. Department of War (DoW), which recently labeled the company a «supply chain risk» after Anthropic refused to allow its models to be used for mass surveillance or fully autonomous lethal weapons.
While a San Francisco judge initially blocked the designation, a federal appeals panel recently denied Anthropic’s bid to stay the blacklisting, leaving the company excluded from lucrative defense contracts during an active military conflict.
Simultaneously, Anthropic is fending off a growing rebellion from its most loyal power users. Despite the company’s «market leader» status, developers have flooded GitHub and X with accusations of «AI shrinkflation,» claiming that the preceding Opus 4.6 model and Claude Code product have been quietly degraded.
Users report that recent versions are more prone to exploration loops, memory loss, and ignored instructions, leading some to describe the newly released Claude Code desktop app as «unpolished» and unbefitting a firm with a near-trillion-dollar valuation. Opus 4.7 is Anthropic’s attempt to silence these critics by proving that «deep thinking» can be paired with the rigorous execution that its enterprise clients now demand.
Ultimately, Opus 4.7 is a model defined by its discipline. In a market where models are often incentivized to be «helpful» to a fault—sometimes hallucinating answers to please the user—Opus 4.7 marks a return to rigor. By allowing users to control effort, set budgets, and verify outputs, Anthropic is moving closer to the goal of a truly autonomous digital labor force. For the engineering teams at Replit, Notion, and beyond, the shift from «watching the AI work» to «managing the AI’s results» has officially begun.
Anthropic is publicly releasing its most powerful large language model yet, Claude Opus 4.7, today — as it continues to keep an even more powerful successor, Mythos, restricted to a small number of external enterprise partners for cybersecurity testing and patching vulnerabilities in the software said enterprises use (which Mythos exposed rapidly).
The big headlines are that Opus 4.7 exceeds its most direct rivals — OpenAI’s GPT-5.4, released in early March 2026, scarcely more than a month ago; and Google’s latest flagship model Gemini 3.1 Pro from February — on key benchmarks including agentic coding, scaled tool-use, agentic computer use, and financial analysis.
But also, it’s notable how tight the race is getting: on directly comparable benchmarks, Opus 4.7 only leads GPT-5.4 by 7-4.
It currently leads the market on the GDPVal-AA knowledge work evaluation with an Elo score of 1753, surpassing both GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
Yet, the model does not represent a «clean sweep» across all categories.
Competitors like GPT-5.4 and Gemini 3.1 Pro still hold the lead in specific domains such as agentic search, where GPT-5.4 scores 89.3% compared to Opus 4.7’s 79.3%, as well as in multilingual Q&A and raw terminal-based coding.
This positioning defines Opus 4.7 not as a unilateral victor in all AI tasks, but as a specialized powerhouse optimized for the reliability and long-horizon autonomy required by the burgeoning agentic economy.
Claude Opus 4.7 is available today across all major cloud platforms, including Amazon Bedrock, Google Cloud’s Vertex AI, and Microsoft Foundry, with API pricing held steady at $5/$25 per million tokens.
Improvement in hard sciences and agentic workflows
Claude Opus 4.7 is a direct evolution of the Opus 4.6 architecture, but its performance delta is most visible in the «hard» sciences of agentic workflows: software engineering and complex document reasoning.
At its core, the model has been re-tuned to exhibit what Anthropic describes as «rigor». This isn’t just marketing parlance; it refers to the model’s new ability to devise its own verification steps before reporting a task as complete.
For example, in internal tests, the model was observed building a Rust-based text-to-speech engine from scratch and then independently feeding its own generated audio through a separate speech recognizer to verify the output against a Python reference.
This level of autonomous self-correction is designed to reduce the «hallucination loops» that often plague earlier iterations of agentic software.
The most significant architectural upgrade is the move to high-resolution multimodal support. Opus 4.7 can now process images up to 2,576 pixels on their longest edge—roughly 3.75 megapixels.
This represents a three-fold increase in resolution compared to previous iterations. For developers building «computer-use» agents that must navigate dense, high-DPI interfaces or for analysts extracting data from intricate technical diagrams, this change effectively removes the «blurry vision» ceiling that previously limited autonomous navigation.
This visual acuity is reflected in benchmarks from XBOW, where the model jumped from a 54.5% success rate in visual-acuity tests to 98.5%.
On the benchmark front, Opus 4.7 has claimed the top spot in several critical categories:
-
Knowledge Work (GDPVal-AA): It achieved an Elo score of 1753, notably outperforming GPT-5.4 (1674) and Gemini 3.1 Pro (1314).
-
Agentic Coding (SWE-bench Pro): The model resolved 64.3% of tasks, compared to 53.4% for its predecessor.
-
Graduate-Level Reasoning (GPQA Diamond): It reached 94.2%, maintaining parity with the industry’s most advanced models while improving on its internal consistency.
-
Visual Reasoning (arXiv Reasoning): With tools, the model scored 91.0%, a meaningful jump from the 84.7% seen in Opus 4.6.
Crucially, Anthropic warns that this increased precision requires a shift in how users approach prompting. Opus 4.7 follows instructions literally. While older models might «read between the lines» and interpret ambiguous prompts loosely, Opus 4.7 executes the exact text provided. This means that legacy prompt libraries may require re-tuning to avoid unexpected results caused by the model’s strict adherence to the letter of the request.
Controlling the ‘thinking’ budget
The «agentic» nature of Opus 4.7—its tendency to pause, plan, and verify—comes with a trade-off in token consumption and latency.
To address this, Anthropic is introducing a new «effort» parameter. Users can now select an xhigh (extra high) effort level, positioned between high and max, allowing for more granular control over the depth of reasoning the model applies to a specific problem.
Internal data shows that while max effort yields the highest scores (approaching 75% on coding tasks), the xhigh setting provides a compelling sweet spot between performance and token expenditure.
To manage the costs associated with these more «thoughtful» runs, the Claude API is introducing «task budgets» in public beta. This allows developers to set a hard ceiling on token spend for autonomous agents, ensuring that a long-running debugging session doesn’t result in an unexpected bill.
These product changes signal a maturing market where AI is no longer a novelty but a production line item that requires fiscal and operational guardrails.
Furthermore, Opus 4.7 utilizes an updated tokenizer that improves text processing efficiency, though it can increase the token count of certain inputs by 1.0–1.35x.
Within the Claude Code environment, the update brings a new /ultrareview command. Unlike standard code reviews that look for syntax errors, /ultrareview is designed to simulate a senior human reviewer, flagging subtle design flaws and logic gaps.
Additionally, «auto mode»—a setting where Claude can make autonomous decisions without constant permission prompts—has been extended to Max plan users.
Licensing, safety, and the «cyber» divide
Anthropic continues to walk a narrow line regarding cybersecurity. The recent announcement of the aforementioend cybersecurity partnership around Mythos with external industry partners — known as «Project Glasswing» — highlighted the dual-use risks of high-capability models.
Consequently, while the flagship Mythos Preview model remains restricted, Opus 4.7 serves as the testbed for new automated safeguards. The model includes systems designed to detect and block requests that suggest high-risk cyberattacks, such as automated vulnerability exploitation.
To bridge the gap for the security industry, Anthropic is launching the Cyber Verification Program. This allows legitimate professionals—vulnerability researchers, penetration testers, and red-teamers—to apply for access to use Opus 4.7’s capabilities for defensive purposes.
This «verified user» model suggests a future where the most capable AI features are not universally available, but gated behind professional credentials and compliance frameworks.
In cybersecurity vulnerability reproduction (CyberGym), Opus 4.7 maintains a 73.1% success rate, trailing Mythos Preview’s 83.1% but leading GPT-5.4’s 66.3%.
Initial reactions from industry partners reveal quantifiable improvements in production enterprise workflows
Early testimonials from enterprise customers shared by Anthropic indicate there has been a tangible shift in model perception of Opus 4.7 from 4.6, going from «impressed by the tech» to «relying on the output».
Clarence Huang, VP of Technology at Intuit, noted that the model’s ability to «catch its own logical faults during the planning phase» is a game-changer for velocity.
This sentiment was echoed by Replit President Michele Catasta, who stated that the model achieved higher quality at a lower cost for tasks like log analysis and bug hunting, adding, «It really feels like a better coworker».
Other specific reactions included:
-
Cognition (Devin): CEO Scott Wu reported that Opus 4.7 can work coherently «for hours» and pushes through difficult problems that previously caused models to stall.
-
Notion: Sarah Sachs, AI Lead, highlighted a 14% improvement in multi-step workflows and a 66% reduction in tool-calling errors, making the agent feel like a «true teammate».
-
Factory Droids: Leo Tchourakov observed that the model carries work through to validation steps rather than «stopping halfway,» a common complaint with previous frontier models.
-
Harvey: Niko Grupen, Head of Applied Research, noted the model’s 90.9% score on BigLaw Bench, highlighting its «noticeably smarter handling of ambiguous document editing tasks».
Perhaps the most telling reaction came from Aj Orbach, CEO of a dashboard-building firm, who remarked on the model’s «design taste,» noting that its choices for data-rich interfaces were of a quality he would «actually ship».
Should enterprises immediately upgrade to Opus 4.7?
For enterprise leaders, Claude Opus 4.7 represents a shift from generative AI as a «creative assistant» to a «reliable operative.»
But importantly, it is not a «clean win» for every use case.
Instead, it is a decisive upgrade for teams building autonomous agents or complex software systems. The primary value proposition is the model’s new capability for self-verification and rigor; it no longer just generates an answer but creates internal tests to verify that the answer is correct before responding. This reliability makes it a superior choice for long-horizon engineering tasks where the cost of human supervision is the primary bottleneck.
However, an immediate, wholesale migration from Opus 4.6 requires caution. The model’s increased literalism in instruction following means that prompts engineered to be «loose» or conversational with previous versions may now produce unexpected or overly rigid results.
Furthermore, enterprises must prepare for a significant increase in operational costs. Opus 4.7 uses an updated tokenizer that can increase input token counts by 1.0–1.35x, and its tendency to «think harder» at high effort levels results in higher output token consumption.
For legacy applications where prompts are fragile and margins are thin, a phased rollout with significant re-tuning is recommended.
Where it puts Anthropic in the AI race
This release arrives at a paradoxical moment for Anthropic. Financially, the company is an undisputed juggernaut, with venture capital firms reportedly extending investment offers at a staggering $800 billion valuation—more than double its $380 billion Series G valuation from February 2026.
This momentum is fueled by explosive growth, with the company’s annual run-rate revenue skyrocketing to $30 billion in April 2026, driven largely by enterprise adoption and the success of Claude Code.
Yet, this commercial success is being contested by intense regulatory and technical friction. Anthropic is currently embroiled in a high-stakes legal battle with the U.S. Department of War (DoW), which recently labeled the company a «supply chain risk» after Anthropic refused to allow its models to be used for mass surveillance or fully autonomous lethal weapons.
While a San Francisco judge initially blocked the designation, a federal appeals panel recently denied Anthropic’s bid to stay the blacklisting, leaving the company excluded from lucrative defense contracts during an active military conflict.
Simultaneously, Anthropic is fending off a growing rebellion from its most loyal power users. Despite the company’s «market leader» status, developers have flooded GitHub and X with accusations of «AI shrinkflation,» claiming that the preceding Opus 4.6 model and Claude Code product have been quietly degraded.
Users report that recent versions are more prone to exploration loops, memory loss, and ignored instructions, leading some to describe the newly released Claude Code desktop app as «unpolished» and unbefitting a firm with a near-trillion-dollar valuation. Opus 4.7 is Anthropic’s attempt to silence these critics by proving that «deep thinking» can be paired with the rigorous execution that its enterprise clients now demand.
Ultimately, Opus 4.7 is a model defined by its discipline. In a market where models are often incentivized to be «helpful» to a fault—sometimes hallucinating answers to please the user—Opus 4.7 marks a return to rigor. By allowing users to control effort, set budgets, and verify outputs, Anthropic is moving closer to the goal of a truly autonomous digital labor force. For the engineering teams at Replit, Notion, and beyond, the shift from «watching the AI work» to «managing the AI’s results» has officially begun.