• Nosotros
  • Publicidad
  • Trabaja con nosotros
  • Contactos
lunes, septiembre 28, 2026
  • Login
No Result
View All Result
NEWSLETTER
Despertar Matinal
  • Titulares del Día
    • All
    • En Portada
    Leonel afirma que la labor de las iglesias es “imprescindible” y asegura que “es necesario volver el rostro hacia Dios”

    Leonel afirma que la labor de las iglesias es “imprescindible” y asegura que “es necesario volver el rostro hacia Dios”

    Director Autoridad Portuaria supervisa el Puerto de La Romana y anuncia inicio de su remodelación para reforzar la seguridad nacional

    Director Autoridad Portuaria supervisa el Puerto de La Romana y anuncia inicio de su remodelación para reforzar la seguridad nacional

    Danilo Medina en Higuey: “El 80 % de la población dice que el país va por el camino equivocado”; acusa al Gobierno de fallarle al pueblo

    Danilo Medina en Higuey: “El 80 % de la población dice que el país va por el camino equivocado”; acusa al Gobierno de fallarle al pueblo

    Video- CONEP advierte que el proselitismo fuera de tiempo propicia la infiltración de fondos del crimen organizado

    Video- CONEP advierte que el proselitismo fuera de tiempo propicia la infiltración de fondos del crimen organizado

    VIDEO- La calidad educativa y el sector eléctrico son los principales obstáculos que enfrenta la RD para convertirse en un país de renta alta

    VIDEO- La calidad educativa y el sector eléctrico son los principales obstáculos que enfrenta la RD para convertirse en un país de renta alta

    Fuerza del Pueblo fortalece su estructura nacional de Medio Ambiente y acredita a más de 60 vicesecretarios

    Fuerza del Pueblo fortalece su estructura nacional de Medio Ambiente y acredita a más de 60 vicesecretarios

    Alejandrina responde a Francisco Javier: Asegura la CONAP no tiene candidato

    Alejandrina responde a Francisco Javier: Asegura la CONAP no tiene candidato

    Gobierno aumenta nueva vez los precios de las gasolinas y el gasoil

    Gobierno aumenta nueva vez los precios de las gasolinas y el gasoil

    Presidente Abinader anuncia 300 becas para jóvenes dominicanos residentes en Nueva York

    Presidente Abinader anuncia 300 becas para jóvenes dominicanos residentes en Nueva York

    Trending Tags

    • Mundo
      • All
      • América Latina
      • Conflictos Internacionales
      • Estados Unidos
      • Europa
      • Geopolítica
      • Haití
      • Medio Oriente
      GTA 6: Rockstar reveló cómo funcionarán las redes sociales y qué se podrá hacer con el celular

      GTA 6: Rockstar reveló cómo funcionarán las redes sociales y qué se podrá hacer con el celular

      Aleksandar Vučic renunció a la presidencia de Serbia y abre el camino a elecciones anticipadas

      Aleksandar Vučic renunció a la presidencia de Serbia y abre el camino a elecciones anticipadas

      Autoridades de Países Bajos revisaron a los pasajeros de Tel Aviv en busca de productos israelíes

      Autoridades de Países Bajos revisaron a los pasajeros de Tel Aviv en busca de productos israelíes

      El dictador Lula destinará millones para comprar deudas de las familias a días de las elecciones

      El dictador Lula destinará millones para comprar deudas de las familias a días de las elecciones

      Mauricio Macri intentó relanzar el PRO en Jujuy pero no fue nadie

      Mauricio Macri intentó relanzar el PRO en Jujuy pero no fue nadie

      Detuvieron a tres inmigrantes ilegales chinos en Formosa y serán deportados por el Gobierno de Milei

      Detuvieron a tres inmigrantes ilegales chinos en Formosa y serán deportados por el Gobierno de Milei

      A casi diez años de la tragedia aérea, Atlético Nacional y Chapecoense se reencontraron en un emotivo amistoso

      A casi diez años de la tragedia aérea, Atlético Nacional y Chapecoense se reencontraron en un emotivo amistoso

      Un referente de la Fórmula 1 salió a bancar a Franco Colapinto tras su accidente en Bakú: "Tienes que admirarlo"

      Un referente de la Fórmula 1 salió a bancar a Franco Colapinto tras su accidente en Bakú: «Tienes que admirarlo»

      Colombia extraditó a EEUU a un líder de la disidencia de las FARC acusado de narcotráfico

      Colombia extraditó a EEUU a un líder de la disidencia de las FARC acusado de narcotráfico

      Trending Tags

      • Nacionales
        • All
        • Bávaro Punta Cana
        • Educación
        • Gobierno
        • Infraestructura
        • Justicia
        • Obras Públicas
        • Opinión
        • Provincias
        • Seguridad Ciudadana
        • semana santa 2026
        • Sociedad
        • Transporte
        Leonel afirma que la labor de las iglesias es “imprescindible” y asegura que “es necesario volver el rostro hacia Dios”

        Leonel afirma que la labor de las iglesias es “imprescindible” y asegura que “es necesario volver el rostro hacia Dios”

        Director Autoridad Portuaria supervisa el Puerto de La Romana y anuncia inicio de su remodelación para reforzar la seguridad nacional

        Director Autoridad Portuaria supervisa el Puerto de La Romana y anuncia inicio de su remodelación para reforzar la seguridad nacional

        Luis Abinader y Xiomara Guante inauguran CAIPI República de Colombia

        Luis Abinader y Xiomara Guante inauguran CAIPI República de Colombia

        Danilo Medina en Higuey: “El 80 % de la población dice que el país va por el camino equivocado”; acusa al Gobierno de fallarle al pueblo

        Danilo Medina en Higuey: “El 80 % de la población dice que el país va por el camino equivocado”; acusa al Gobierno de fallarle al pueblo

        Instituto Duartiano denuncia en algunas escuelas la matrícula haitiana alcanza hasta un 70 %

        Instituto Duartiano denuncia en algunas escuelas la matrícula haitiana alcanza hasta un 70 %

        Video- CONEP advierte que el proselitismo fuera de tiempo propicia la infiltración de fondos del crimen organizado

        Video- CONEP advierte que el proselitismo fuera de tiempo propicia la infiltración de fondos del crimen organizado

        Conep advierte proselitismo fuera de tiempo propicia infiltración fondos del crimen organizado

        Conep advierte proselitismo fuera de tiempo propicia infiltración fondos del crimen organizado

        VIDEO- La calidad educativa y el sector eléctrico son los principales obstáculos que enfrenta la RD para convertirse en un país de renta alta

        VIDEO- La calidad educativa y el sector eléctrico son los principales obstáculos que enfrenta la RD para convertirse en un país de renta alta

        Ministerio de Salud conmemora el Día Mundial de la Salud...

        Ministerio de Salud conmemora el Día Mundial de la Salud…

        Trending Tags

        • Política
          • All
          • Congreso
          • Opinión Política
          • Partidos Políticos
          • Poder Municipal
          • Transparencia y Corrupción
          Leonel afirma labor de las iglesias es "imprescindible” y asegura que "es necesario volver el rostro hacia Dios”

          Leonel afirma labor de las iglesias es «imprescindible” y asegura que «es necesario volver el rostro hacia Dios”

          Danilo Medina en Higüey: “El 80 % de la población dice que el país va por el camino equivocado”

          Danilo Medina en Higüey: “El 80 % de la población dice que el país va por el camino equivocado”

          PRD endurece oposición al Gobierno e impulsa concertación...

          PRD endurece oposición al Gobierno e impulsa concertación…

          Francisco Javier García denuncia “cacería” contra sus seguidores y cuestiona retiro de 523 mil personas del padrón del PLD

          Francisco Javier García denuncia “cacería” contra sus seguidores y cuestiona retiro de 523 mil personas del padrón del PLD

          (VIDEO) EN SAN JUAN: La Fuerza del Pueblo incorpora a Alejandro Tejada en un multitudinario encuentro en El Batey

          (VIDEO) EN SAN JUAN: La Fuerza del Pueblo incorpora a Alejandro Tejada en un multitudinario encuentro en El Batey

          Gonzalo Castillo: “Me pueden meter preso, nadie va a evitar que sea presidente de la República Dominicana”

          Gonzalo Castillo: “Me pueden meter preso, nadie va a evitar que sea presidente de la República Dominicana”

          Exministro de Haciendas advierte fuga de ahorros en dólares si...

          Exministro de Haciendas advierte fuga de ahorros en dólares si…

          Robert Polanco revela respaldo a David Collado y descarta...

          Robert Polanco revela respaldo a David Collado y descarta…

          TSE dispone suspensión provisional celebración VII Convención...

          TSE dispone suspensión provisional celebración VII Convención…

          Trending Tags

          • Deportes
            • All
            • Atletas Dominicanos
            • Béisbol
            DR Open Kiteboarding Championship reúne atletas de 15 países y reafirma a Cabarete como capital del kitesurf del Caribe

            Cabarete se corona como capital histórica del kitesurf con el DR Open Championship 2026

            El impulso olímpico del billar recibe un impulso de los dos campeones mundiales consecutivos de China

            El impulso olímpico del billar recibe un impulso de los dos campeones mundiales consecutivos de China

            La reboteadora líder de todos los tiempos de la WNBA, Tina Charles, se retira del baloncesto

            La reboteadora líder de todos los tiempos de la WNBA, Tina Charles, se retira del baloncesto

            Sabalenka pide boicot si los jugadores no obtienen una mayor parte de los ingresos del Grand Slam

            Sabalenka pide boicot si los jugadores no obtienen una mayor parte de los ingresos del Grand Slam

            Los 76ers tienen un cambio breve y luego una noche larga con una derrota aplastante en el Juego 1

            Los 76ers tienen un cambio breve y luego una noche larga con una derrota aplastante en el Juego 1

            Ex empleado de Stefon Diggs subirá al estrado por segundo día en el juicio por agresión a un jugador de la NFL

            Ex empleado de Stefon Diggs subirá al estrado por segundo día en el juicio por agresión a un jugador de la NFL

            Kansas City es la sede central de la Copa del Mundo y alberga a Inglaterra, Argentina y Holanda, además de 6 partidos.

            Kansas City es la sede central de la Copa del Mundo y alberga a Inglaterra, Argentina y Holanda, además de 6 partidos.

            30 pasajeros son evacuados después de que un crucero encallara en un arrecife en Fiji

            Buffalo recibe a Montreal para abrir la segunda ronda

            Judge quiere una nueva tradición del Bronx: “¡Los Yankees ganan!” de Sterling. antes de la canción de Sinatra

            Judge quiere una nueva tradición del Bronx: “¡Los Yankees ganan!” de Sterling. antes de la canción de Sinatra

            Trending Tags

            • Economía
              • All
              • Combustibles
              • Energía
              • Indicadores Económicos
              • Sector Energético
              • Turismo
              Aerodom anuncia nuevas rutas aéreas, pero la pregunta de fondo es quién fiscaliza la concesión

              Aerodom anuncia nuevas rutas aéreas, pero la pregunta de fondo es quién fiscaliza la concesión

              Aventúrate RD 2026

              Aventúrate RD 2026 revela agenda oficial y consolida el turismo de aventura dominicano

              WTTC: Una inversión de más de un billón de dólares en viajes y turismo es una muestra de confianza en el futuro del sector

              WTTC: Una inversión de más de un billón de dólares en viajes y turismo es una muestra de confianza en el futuro del sector

              Una semana para crear en Samaná: Atelier Yubarta busca conectar arte, naturaleza y turismo en Cayo Levantado Resort

              Una semana para crear en Samaná: Atelier Yubarta busca conectar arte, naturaleza y turismo en Cayo Levantado Resort

              Meta RD 2036: el plan turístico que el Gobierno aplaude sin fiscalización

              Meta RD 2036: el plan turístico que el Gobierno aplaude sin fiscalización

              Viva Resorts impulsa el turismo interno en República Dominicana con jornada exclusiva en Bayahibe

              Viva Resorts impulsa el turismo interno en República Dominicana con jornada exclusiva en Bayahibe

              El ministerio de Turismo cierra con éxito festival gastronómico “Saborea el Paraíso” en Sánchez, Samaná

              El Ministerio de Turismo celebra un exitoso cierre del festival gastronómico «Saborea el Paraíso» en Sánchez, Samaná

              El Consejo Mundial de Viajes y Turismo (WTTC) informa la incorporación de Piñero como miembro global

              El Consejo Mundial de Viajes y Turismo (WTTC) informa la incorporación de Piñero como miembro global

              Más allá del comercio: los efectos del arancel estadounidense sobre el turismo dominicano

              Arancel de EE.UU. pone a prueba al turismo dominicano y al silencio oficial del gobierno

              Trending Tags

              • Ciencia
                • All
                • Energía
                • Innovación
                • Investigación Científica
                • Salud y Medicina
                • Tecnología Médica
                El voto evangélico para Lula da Silva en las elecciones de Brasil

                El voto evangélico para Lula da Silva en las elecciones de Brasil

                CONAP PLD niega maniobra para sacar 523 mil de padrón

                CONAP PLD niega maniobra para sacar 523 mil de padrón

                Piden ampliar presencia de la JCE en el Medio Oeste de EE. UU.

                Piden ampliar presencia de la JCE en el Medio Oeste de EE. UU.

                Estos son los cinco hombres de mayor confianza de De la Espriella

                Estos son los cinco hombres de mayor confianza de De la Espriella

                Duelo de limusinas entre Bestia’ de Trump y Bandera Roja’ de Xi

                Duelo de limusinas entre Bestia’ de Trump y Bandera Roja’ de Xi

                Leonel afirma que la Fuerza del Pueblo se posiciona como una alternativa ante la “frustración” actual de la sociedad

                Leonel afirma que la Fuerza del Pueblo se posiciona como una alternativa ante la “frustración” actual de la sociedad

                Meloni limita al 30% los alumnos por aula que no sepan italiano

                Meloni limita al 30% los alumnos por aula que no sepan italiano

                El PAM gana elecciones marcadas por la abstención en Marruecos

                El PAM gana elecciones marcadas por la abstención en Marruecos

                Periodistas de CNN, MS NOW y Politico entran en la Casa Blanca

                Periodistas de CNN, MS NOW y Politico entran en la Casa Blanca

                Trending Tags

                • Tecnología
                  • All
                  • Aplicaciones
                  • Inteligencia Artificial
                  Un jurado de Nuevo México declara a Facebook responsable de engañar a los usuarios sobre la protección de la privacidad

                  Un jurado de Nuevo México declara a Facebook responsable de engañar a los usuarios sobre la protección de la privacidad

                  Nave espacial privada regresa a la Tierra después de no poder rescatar el viejo telescopio de la NASA

                  Nave espacial privada regresa a la Tierra después de no poder rescatar el viejo telescopio de la NASA

                  La UE promete defender su postura contra X después de que Estados Unidos respalde una impugnación judicial de Elon Musk

                  La UE promete defender su postura contra X después de que Estados Unidos respalde una impugnación judicial de Elon Musk

                  A 40 días de las elecciones intermedias, los funcionarios electorales dicen que el nuevo plan cibernético de EE. UU. llega demasiado tarde

                  A 40 días de las elecciones intermedias, los funcionarios electorales dicen que el nuevo plan cibernético de EE. UU. llega demasiado tarde

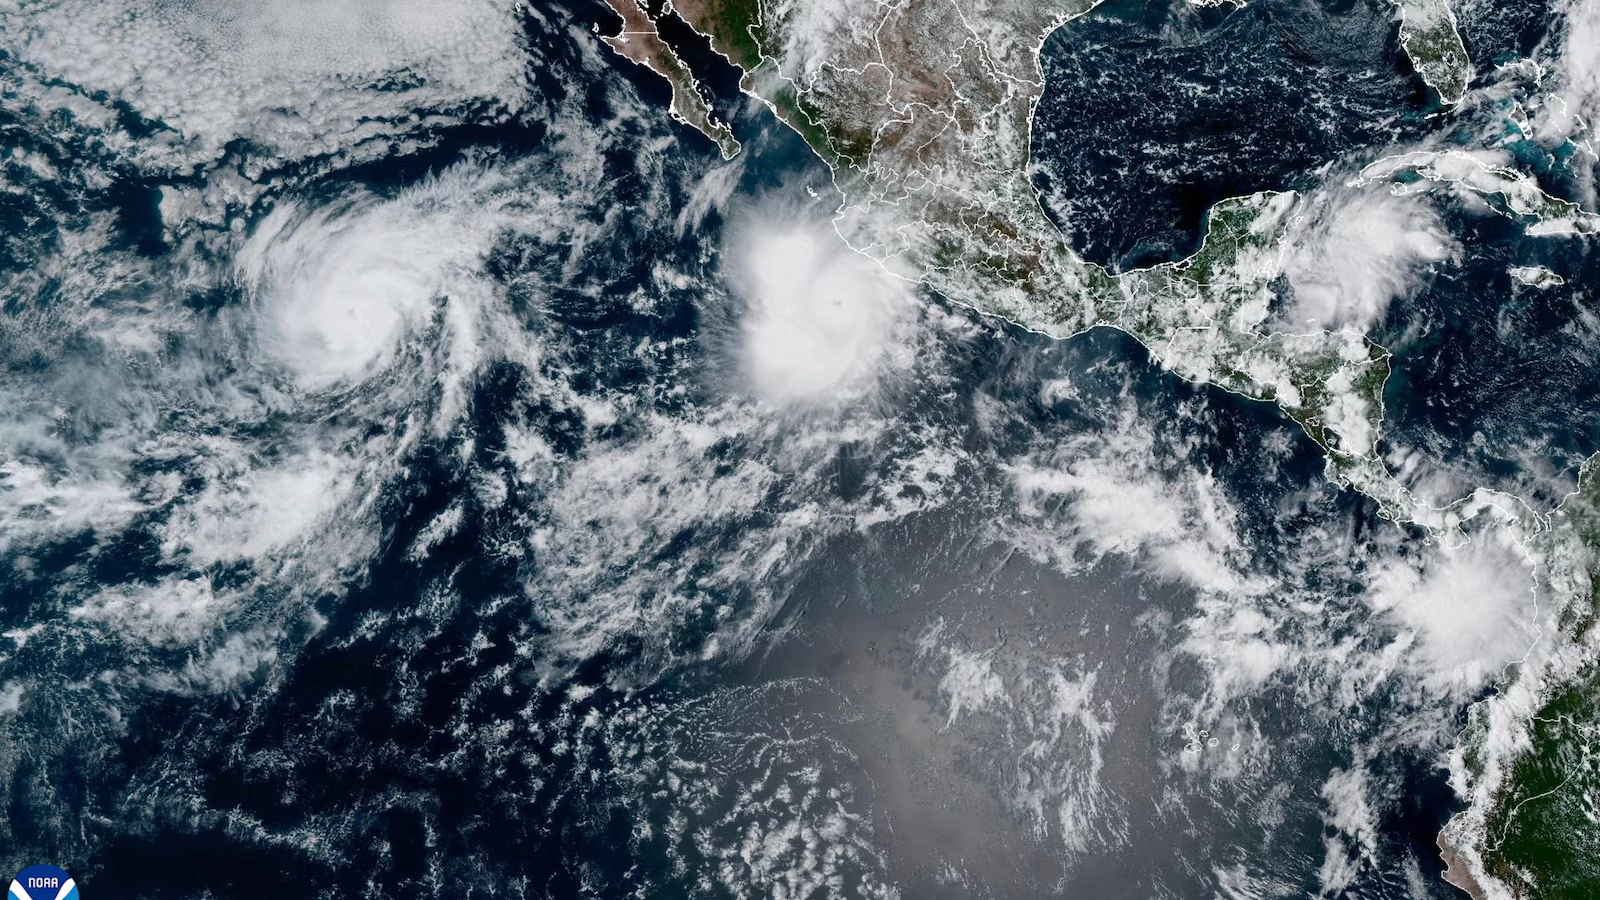
                  Ha sido una intensa temporada de huracanes en el Pacífico y aún queda mucho camino por recorrer

                  Ha sido una intensa temporada de huracanes en el Pacífico y aún queda mucho camino por recorrer

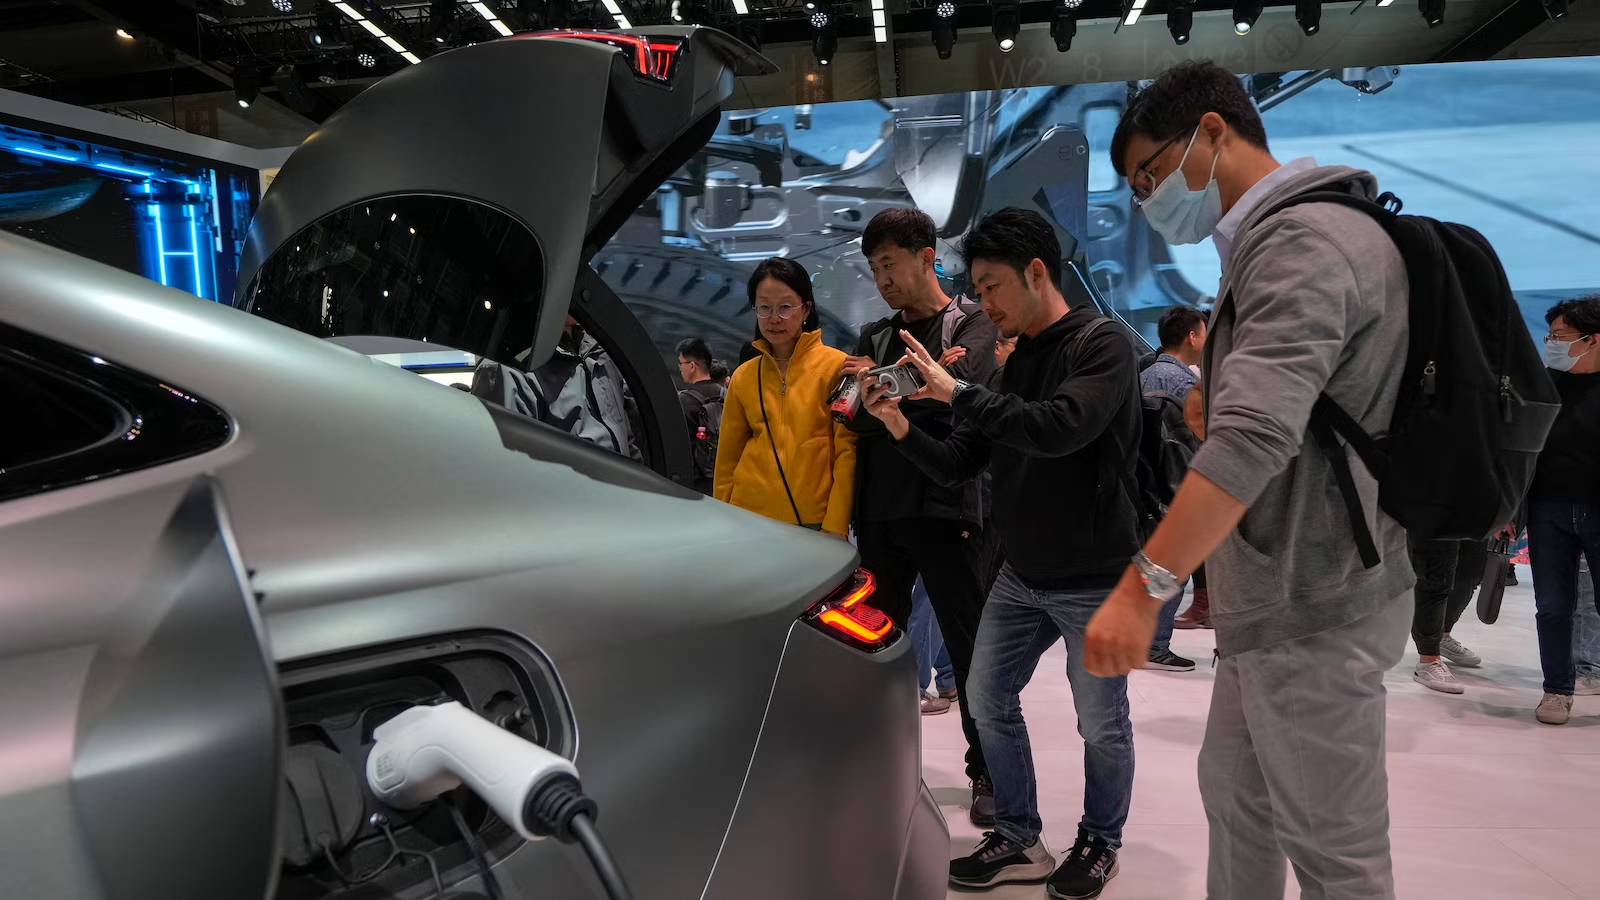
                  Las empresas automotrices chinas avanzan en la tecnología de vehículos eléctricos y logran una carga ultrarrápida en cinco minutos

                  Las empresas automotrices chinas avanzan en la tecnología de vehículos eléctricos y logran una carga ultrarrápida en cinco minutos

                  Los hacks autónomos de IA plantean cuestiones espinosas sobre la responsabilidad legal

                  Los hacks autónomos de IA plantean cuestiones espinosas sobre la responsabilidad legal

                  Panel de la FDA respalda el primer análisis de sangre para cáncer de Grail

                  Panel de la FDA respalda el primer análisis de sangre para cáncer de Grail

                  Líderes tecnológicos a la ONU: Por el bien de la humanidad, controlen la tecnología de inteligencia artificial que creamos

                  Líderes tecnológicos a la ONU: Por el bien de la humanidad, controlen la tecnología de inteligencia artificial que creamos

                  Trending Tags

                  • Entretenimiento
                    • All
                    • Cine y Series
                    • Cultura Digital
                    • Cultura Popular
                    • Gastronomía
                    • Música
                    Celine Dion está de regreso en París, pero su primera canción sigue siendo "un gran secreto"

                    Celine Dion está de regreso en París, pero su primera canción sigue siendo «un gran secreto»

                    30 pasajeros son evacuados después de que un crucero encallara en un arrecife en Fiji

                    La ‘Odisea’ de Emily Wilson se convirtió en un punto de inflamación cultural. Ahora ella está retraduciendo todo.

                    Editor, editor y reportero de Stars and Stripes demandan al Pentágono para impugnar sus despidos

                    Editor, editor y reportero de Stars and Stripes demandan al Pentágono para impugnar sus despidos

                    Muere Peter Cullen, el prolífico actor de doblaje que le dio a Optimus Prime su autoritario barítono

                    Muere Peter Cullen, el prolífico actor de doblaje que le dio a Optimus Prime su autoritario barítono

                    Juez pregunta por qué el Kennedy Center se está moviendo tan rápido para devolver el nombre de Trump al edificio

                    Juez pregunta por qué el Kennedy Center se está moviendo tan rápido para devolver el nombre de Trump al edificio

                    En el conflictivo norte de Nigeria, una animada vida nocturna convive con una policía moral e inseguridad.

                    En el conflictivo norte de Nigeria, una animada vida nocturna convive con una policía moral e inseguridad.

                    Un teatro reinventa la Odisea de Homero a través de la agonía de la guerra de Ucrania

                    Un teatro reinventa la Odisea de Homero a través de la agonía de la guerra de Ucrania

                    El rapero Yung Filly regresará a Gran Bretaña antes del juicio por violación en Australia el próximo año

                    El rapero Yung Filly regresará a Gran Bretaña antes del juicio por violación en Australia el próximo año

                    30 pasajeros son evacuados después de que un crucero encallara en un arrecife en Fiji

                    Los británicos tienen la oportunidad de leer las memorias de Jason Arday en las librerías del Reino Unido

                    Trending Tags

                    • Titulares del Día
                      • All
                      • En Portada
                      Leonel afirma que la labor de las iglesias es “imprescindible” y asegura que “es necesario volver el rostro hacia Dios”

                      Leonel afirma que la labor de las iglesias es “imprescindible” y asegura que “es necesario volver el rostro hacia Dios”

                      Director Autoridad Portuaria supervisa el Puerto de La Romana y anuncia inicio de su remodelación para reforzar la seguridad nacional

                      Director Autoridad Portuaria supervisa el Puerto de La Romana y anuncia inicio de su remodelación para reforzar la seguridad nacional

                      Danilo Medina en Higuey: “El 80 % de la población dice que el país va por el camino equivocado”; acusa al Gobierno de fallarle al pueblo

                      Danilo Medina en Higuey: “El 80 % de la población dice que el país va por el camino equivocado”; acusa al Gobierno de fallarle al pueblo

                      Video- CONEP advierte que el proselitismo fuera de tiempo propicia la infiltración de fondos del crimen organizado

                      Video- CONEP advierte que el proselitismo fuera de tiempo propicia la infiltración de fondos del crimen organizado

                      VIDEO- La calidad educativa y el sector eléctrico son los principales obstáculos que enfrenta la RD para convertirse en un país de renta alta

                      VIDEO- La calidad educativa y el sector eléctrico son los principales obstáculos que enfrenta la RD para convertirse en un país de renta alta

                      Fuerza del Pueblo fortalece su estructura nacional de Medio Ambiente y acredita a más de 60 vicesecretarios

                      Fuerza del Pueblo fortalece su estructura nacional de Medio Ambiente y acredita a más de 60 vicesecretarios

                      Alejandrina responde a Francisco Javier: Asegura la CONAP no tiene candidato

                      Alejandrina responde a Francisco Javier: Asegura la CONAP no tiene candidato

                      Gobierno aumenta nueva vez los precios de las gasolinas y el gasoil

                      Gobierno aumenta nueva vez los precios de las gasolinas y el gasoil

                      Presidente Abinader anuncia 300 becas para jóvenes dominicanos residentes en Nueva York

                      Presidente Abinader anuncia 300 becas para jóvenes dominicanos residentes en Nueva York

                      Trending Tags

                      • Mundo
                        • All
                        • América Latina
                        • Conflictos Internacionales
                        • Estados Unidos
                        • Europa
                        • Geopolítica
                        • Haití
                        • Medio Oriente
                        GTA 6: Rockstar reveló cómo funcionarán las redes sociales y qué se podrá hacer con el celular

                        GTA 6: Rockstar reveló cómo funcionarán las redes sociales y qué se podrá hacer con el celular

                        Aleksandar Vučic renunció a la presidencia de Serbia y abre el camino a elecciones anticipadas

                        Aleksandar Vučic renunció a la presidencia de Serbia y abre el camino a elecciones anticipadas

                        Autoridades de Países Bajos revisaron a los pasajeros de Tel Aviv en busca de productos israelíes

                        Autoridades de Países Bajos revisaron a los pasajeros de Tel Aviv en busca de productos israelíes

                        El dictador Lula destinará millones para comprar deudas de las familias a días de las elecciones

                        El dictador Lula destinará millones para comprar deudas de las familias a días de las elecciones

                        Mauricio Macri intentó relanzar el PRO en Jujuy pero no fue nadie

                        Mauricio Macri intentó relanzar el PRO en Jujuy pero no fue nadie

                        Detuvieron a tres inmigrantes ilegales chinos en Formosa y serán deportados por el Gobierno de Milei

                        Detuvieron a tres inmigrantes ilegales chinos en Formosa y serán deportados por el Gobierno de Milei

                        A casi diez años de la tragedia aérea, Atlético Nacional y Chapecoense se reencontraron en un emotivo amistoso

                        A casi diez años de la tragedia aérea, Atlético Nacional y Chapecoense se reencontraron en un emotivo amistoso

                        Un referente de la Fórmula 1 salió a bancar a Franco Colapinto tras su accidente en Bakú: "Tienes que admirarlo"

                        Un referente de la Fórmula 1 salió a bancar a Franco Colapinto tras su accidente en Bakú: «Tienes que admirarlo»

                        Colombia extraditó a EEUU a un líder de la disidencia de las FARC acusado de narcotráfico

                        Colombia extraditó a EEUU a un líder de la disidencia de las FARC acusado de narcotráfico

                        Trending Tags

                        • Nacionales
                          • All
                          • Bávaro Punta Cana
                          • Educación
                          • Gobierno
                          • Infraestructura
                          • Justicia
                          • Obras Públicas
                          • Opinión
                          • Provincias
                          • Seguridad Ciudadana
                          • semana santa 2026
                          • Sociedad
                          • Transporte
                          Leonel afirma que la labor de las iglesias es “imprescindible” y asegura que “es necesario volver el rostro hacia Dios”

                          Leonel afirma que la labor de las iglesias es “imprescindible” y asegura que “es necesario volver el rostro hacia Dios”

                          Director Autoridad Portuaria supervisa el Puerto de La Romana y anuncia inicio de su remodelación para reforzar la seguridad nacional

                          Director Autoridad Portuaria supervisa el Puerto de La Romana y anuncia inicio de su remodelación para reforzar la seguridad nacional

                          Luis Abinader y Xiomara Guante inauguran CAIPI República de Colombia

                          Luis Abinader y Xiomara Guante inauguran CAIPI República de Colombia

                          Danilo Medina en Higuey: “El 80 % de la población dice que el país va por el camino equivocado”; acusa al Gobierno de fallarle al pueblo

                          Danilo Medina en Higuey: “El 80 % de la población dice que el país va por el camino equivocado”; acusa al Gobierno de fallarle al pueblo

                          Instituto Duartiano denuncia en algunas escuelas la matrícula haitiana alcanza hasta un 70 %

                          Instituto Duartiano denuncia en algunas escuelas la matrícula haitiana alcanza hasta un 70 %

                          Video- CONEP advierte que el proselitismo fuera de tiempo propicia la infiltración de fondos del crimen organizado

                          Video- CONEP advierte que el proselitismo fuera de tiempo propicia la infiltración de fondos del crimen organizado

                          Conep advierte proselitismo fuera de tiempo propicia infiltración fondos del crimen organizado

                          Conep advierte proselitismo fuera de tiempo propicia infiltración fondos del crimen organizado

                          VIDEO- La calidad educativa y el sector eléctrico son los principales obstáculos que enfrenta la RD para convertirse en un país de renta alta

                          VIDEO- La calidad educativa y el sector eléctrico son los principales obstáculos que enfrenta la RD para convertirse en un país de renta alta

                          Ministerio de Salud conmemora el Día Mundial de la Salud...

                          Ministerio de Salud conmemora el Día Mundial de la Salud…

                          Trending Tags

                          • Política
                            • All
                            • Congreso
                            • Opinión Política
                            • Partidos Políticos
                            • Poder Municipal
                            • Transparencia y Corrupción
                            Leonel afirma labor de las iglesias es "imprescindible” y asegura que "es necesario volver el rostro hacia Dios”

                            Leonel afirma labor de las iglesias es «imprescindible” y asegura que «es necesario volver el rostro hacia Dios”

                            Danilo Medina en Higüey: “El 80 % de la población dice que el país va por el camino equivocado”

                            Danilo Medina en Higüey: “El 80 % de la población dice que el país va por el camino equivocado”

                            PRD endurece oposición al Gobierno e impulsa concertación...

                            PRD endurece oposición al Gobierno e impulsa concertación…

                            Francisco Javier García denuncia “cacería” contra sus seguidores y cuestiona retiro de 523 mil personas del padrón del PLD

                            Francisco Javier García denuncia “cacería” contra sus seguidores y cuestiona retiro de 523 mil personas del padrón del PLD

                            (VIDEO) EN SAN JUAN: La Fuerza del Pueblo incorpora a Alejandro Tejada en un multitudinario encuentro en El Batey

                            (VIDEO) EN SAN JUAN: La Fuerza del Pueblo incorpora a Alejandro Tejada en un multitudinario encuentro en El Batey

                            Gonzalo Castillo: “Me pueden meter preso, nadie va a evitar que sea presidente de la República Dominicana”

                            Gonzalo Castillo: “Me pueden meter preso, nadie va a evitar que sea presidente de la República Dominicana”

                            Exministro de Haciendas advierte fuga de ahorros en dólares si...

                            Exministro de Haciendas advierte fuga de ahorros en dólares si…

                            Robert Polanco revela respaldo a David Collado y descarta...

                            Robert Polanco revela respaldo a David Collado y descarta…

                            TSE dispone suspensión provisional celebración VII Convención...

                            TSE dispone suspensión provisional celebración VII Convención…

                            Trending Tags

                            • Deportes
                              • All
                              • Atletas Dominicanos
                              • Béisbol
                              DR Open Kiteboarding Championship reúne atletas de 15 países y reafirma a Cabarete como capital del kitesurf del Caribe

                              Cabarete se corona como capital histórica del kitesurf con el DR Open Championship 2026

                              El impulso olímpico del billar recibe un impulso de los dos campeones mundiales consecutivos de China

                              El impulso olímpico del billar recibe un impulso de los dos campeones mundiales consecutivos de China

                              La reboteadora líder de todos los tiempos de la WNBA, Tina Charles, se retira del baloncesto

                              La reboteadora líder de todos los tiempos de la WNBA, Tina Charles, se retira del baloncesto

                              Sabalenka pide boicot si los jugadores no obtienen una mayor parte de los ingresos del Grand Slam

                              Sabalenka pide boicot si los jugadores no obtienen una mayor parte de los ingresos del Grand Slam

                              Los 76ers tienen un cambio breve y luego una noche larga con una derrota aplastante en el Juego 1

                              Los 76ers tienen un cambio breve y luego una noche larga con una derrota aplastante en el Juego 1

                              Ex empleado de Stefon Diggs subirá al estrado por segundo día en el juicio por agresión a un jugador de la NFL

                              Ex empleado de Stefon Diggs subirá al estrado por segundo día en el juicio por agresión a un jugador de la NFL

                              Kansas City es la sede central de la Copa del Mundo y alberga a Inglaterra, Argentina y Holanda, además de 6 partidos.

                              Kansas City es la sede central de la Copa del Mundo y alberga a Inglaterra, Argentina y Holanda, además de 6 partidos.

                              30 pasajeros son evacuados después de que un crucero encallara en un arrecife en Fiji

                              Buffalo recibe a Montreal para abrir la segunda ronda

                              Judge quiere una nueva tradición del Bronx: “¡Los Yankees ganan!” de Sterling. antes de la canción de Sinatra

                              Judge quiere una nueva tradición del Bronx: “¡Los Yankees ganan!” de Sterling. antes de la canción de Sinatra

                              Trending Tags

                              • Economía
                                • All
                                • Combustibles
                                • Energía
                                • Indicadores Económicos
                                • Sector Energético
                                • Turismo
                                Aerodom anuncia nuevas rutas aéreas, pero la pregunta de fondo es quién fiscaliza la concesión

                                Aerodom anuncia nuevas rutas aéreas, pero la pregunta de fondo es quién fiscaliza la concesión

                                Aventúrate RD 2026

                                Aventúrate RD 2026 revela agenda oficial y consolida el turismo de aventura dominicano

                                WTTC: Una inversión de más de un billón de dólares en viajes y turismo es una muestra de confianza en el futuro del sector

                                WTTC: Una inversión de más de un billón de dólares en viajes y turismo es una muestra de confianza en el futuro del sector

                                Una semana para crear en Samaná: Atelier Yubarta busca conectar arte, naturaleza y turismo en Cayo Levantado Resort

                                Una semana para crear en Samaná: Atelier Yubarta busca conectar arte, naturaleza y turismo en Cayo Levantado Resort

                                Meta RD 2036: el plan turístico que el Gobierno aplaude sin fiscalización

                                Meta RD 2036: el plan turístico que el Gobierno aplaude sin fiscalización

                                Viva Resorts impulsa el turismo interno en República Dominicana con jornada exclusiva en Bayahibe

                                Viva Resorts impulsa el turismo interno en República Dominicana con jornada exclusiva en Bayahibe

                                El ministerio de Turismo cierra con éxito festival gastronómico “Saborea el Paraíso” en Sánchez, Samaná

                                El Ministerio de Turismo celebra un exitoso cierre del festival gastronómico «Saborea el Paraíso» en Sánchez, Samaná

                                El Consejo Mundial de Viajes y Turismo (WTTC) informa la incorporación de Piñero como miembro global

                                El Consejo Mundial de Viajes y Turismo (WTTC) informa la incorporación de Piñero como miembro global

                                Más allá del comercio: los efectos del arancel estadounidense sobre el turismo dominicano

                                Arancel de EE.UU. pone a prueba al turismo dominicano y al silencio oficial del gobierno

                                Trending Tags

                                • Ciencia
                                  • All
                                  • Energía
                                  • Innovación
                                  • Investigación Científica
                                  • Salud y Medicina
                                  • Tecnología Médica
                                  El voto evangélico para Lula da Silva en las elecciones de Brasil

                                  El voto evangélico para Lula da Silva en las elecciones de Brasil

                                  CONAP PLD niega maniobra para sacar 523 mil de padrón

                                  CONAP PLD niega maniobra para sacar 523 mil de padrón

                                  Piden ampliar presencia de la JCE en el Medio Oeste de EE. UU.

                                  Piden ampliar presencia de la JCE en el Medio Oeste de EE. UU.

                                  Estos son los cinco hombres de mayor confianza de De la Espriella

                                  Estos son los cinco hombres de mayor confianza de De la Espriella

                                  Duelo de limusinas entre Bestia’ de Trump y Bandera Roja’ de Xi

                                  Duelo de limusinas entre Bestia’ de Trump y Bandera Roja’ de Xi

                                  Leonel afirma que la Fuerza del Pueblo se posiciona como una alternativa ante la “frustración” actual de la sociedad

                                  Leonel afirma que la Fuerza del Pueblo se posiciona como una alternativa ante la “frustración” actual de la sociedad

                                  Meloni limita al 30% los alumnos por aula que no sepan italiano

                                  Meloni limita al 30% los alumnos por aula que no sepan italiano

                                  El PAM gana elecciones marcadas por la abstención en Marruecos

                                  El PAM gana elecciones marcadas por la abstención en Marruecos

                                  Periodistas de CNN, MS NOW y Politico entran en la Casa Blanca

                                  Periodistas de CNN, MS NOW y Politico entran en la Casa Blanca

                                  Trending Tags

                                  • Tecnología
                                    • All
                                    • Aplicaciones
                                    • Inteligencia Artificial
                                    Un jurado de Nuevo México declara a Facebook responsable de engañar a los usuarios sobre la protección de la privacidad

                                    Un jurado de Nuevo México declara a Facebook responsable de engañar a los usuarios sobre la protección de la privacidad

                                    Nave espacial privada regresa a la Tierra después de no poder rescatar el viejo telescopio de la NASA

                                    Nave espacial privada regresa a la Tierra después de no poder rescatar el viejo telescopio de la NASA

                                    La UE promete defender su postura contra X después de que Estados Unidos respalde una impugnación judicial de Elon Musk

                                    La UE promete defender su postura contra X después de que Estados Unidos respalde una impugnación judicial de Elon Musk

                                    A 40 días de las elecciones intermedias, los funcionarios electorales dicen que el nuevo plan cibernético de EE. UU. llega demasiado tarde

                                    A 40 días de las elecciones intermedias, los funcionarios electorales dicen que el nuevo plan cibernético de EE. UU. llega demasiado tarde

                                    Ha sido una intensa temporada de huracanes en el Pacífico y aún queda mucho camino por recorrer

                                    Ha sido una intensa temporada de huracanes en el Pacífico y aún queda mucho camino por recorrer

                                    Las empresas automotrices chinas avanzan en la tecnología de vehículos eléctricos y logran una carga ultrarrápida en cinco minutos

                                    Las empresas automotrices chinas avanzan en la tecnología de vehículos eléctricos y logran una carga ultrarrápida en cinco minutos

                                    Los hacks autónomos de IA plantean cuestiones espinosas sobre la responsabilidad legal

                                    Los hacks autónomos de IA plantean cuestiones espinosas sobre la responsabilidad legal

                                    Panel de la FDA respalda el primer análisis de sangre para cáncer de Grail

                                    Panel de la FDA respalda el primer análisis de sangre para cáncer de Grail

                                    Líderes tecnológicos a la ONU: Por el bien de la humanidad, controlen la tecnología de inteligencia artificial que creamos

                                    Líderes tecnológicos a la ONU: Por el bien de la humanidad, controlen la tecnología de inteligencia artificial que creamos

                                    Trending Tags

                                    • Entretenimiento
                                      • All
                                      • Cine y Series
                                      • Cultura Digital
                                      • Cultura Popular
                                      • Gastronomía
                                      • Música
                                      Celine Dion está de regreso en París, pero su primera canción sigue siendo "un gran secreto"

                                      Celine Dion está de regreso en París, pero su primera canción sigue siendo «un gran secreto»

                                      30 pasajeros son evacuados después de que un crucero encallara en un arrecife en Fiji

                                      La ‘Odisea’ de Emily Wilson se convirtió en un punto de inflamación cultural. Ahora ella está retraduciendo todo.

                                      Editor, editor y reportero de Stars and Stripes demandan al Pentágono para impugnar sus despidos

                                      Editor, editor y reportero de Stars and Stripes demandan al Pentágono para impugnar sus despidos

                                      Muere Peter Cullen, el prolífico actor de doblaje que le dio a Optimus Prime su autoritario barítono

                                      Muere Peter Cullen, el prolífico actor de doblaje que le dio a Optimus Prime su autoritario barítono

                                      Juez pregunta por qué el Kennedy Center se está moviendo tan rápido para devolver el nombre de Trump al edificio

                                      Juez pregunta por qué el Kennedy Center se está moviendo tan rápido para devolver el nombre de Trump al edificio

                                      En el conflictivo norte de Nigeria, una animada vida nocturna convive con una policía moral e inseguridad.

                                      En el conflictivo norte de Nigeria, una animada vida nocturna convive con una policía moral e inseguridad.

                                      Un teatro reinventa la Odisea de Homero a través de la agonía de la guerra de Ucrania

                                      Un teatro reinventa la Odisea de Homero a través de la agonía de la guerra de Ucrania

                                      El rapero Yung Filly regresará a Gran Bretaña antes del juicio por violación en Australia el próximo año

                                      El rapero Yung Filly regresará a Gran Bretaña antes del juicio por violación en Australia el próximo año

                                      30 pasajeros son evacuados después de que un crucero encallara en un arrecife en Fiji

                                      Los británicos tienen la oportunidad de leer las memorias de Jason Arday en las librerías del Reino Unido

                                      Trending Tags

                                      No Result
                                      View All Result
                                      Despertar Matinal
                                      No Result
                                      View All Result

                                      OpenAI’s GPT-5.5 is here, and it’s no potato: narrowly beats Anthropic’s Claude Mythos Preview on Terminal-Bench 2.0

                                      by — Redacción Despertar Matinal
                                      23 de abril de 2026
                                      in Tecnología
                                      0
                                      OpenAI's GPT-5.5 is here, and it's no potato: narrowly beats Anthropic's Claude Mythos Preview on Terminal-Bench 2.0
                                      0
                                      SHARES
                                      13
                                      VIEWS
                                      Share on FacebookShare on Twitter

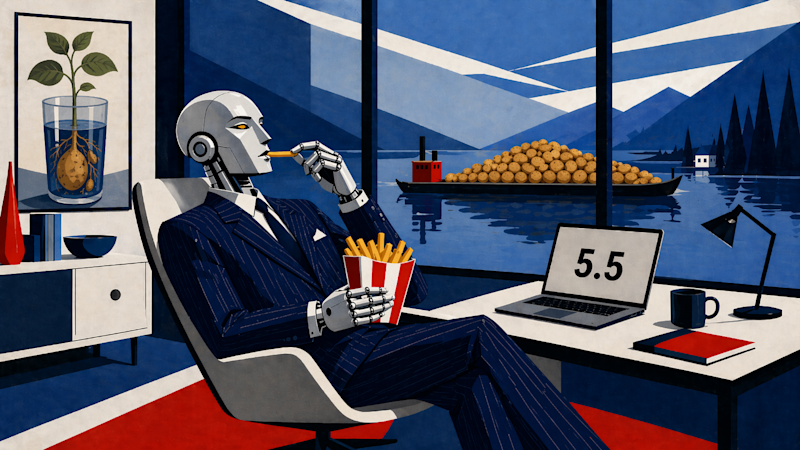
                                      After months of rumors and reports that OpenAI was developing a new, more powerful AI large language model for use in ChatGPT and through its application programming interface (API), allegedly codenamed «Spud» internally, the company has today unveiled its latest offering under the more formal name GPT-5.5.

                                      And to likely no one’s surprise, it’s hardly a «potato» in the disparaging sense of the word: GPT-5.5 retakes the lead for OpenAI in generally available LLMs, coming ahead of rivals Anthropic’s and Google’s latest public offerings, and even beating the private Anthropic Claude Mythos Preview model narrowly on one benchmark (essentially a statistical tie).

                                      «It’s definitely our strongest model yet on coding, both measured by benchmarks and based on the feedback that we’ve gotten from trusted partners, as well as our own experience,» explained Amelia «Mia» Glaese, VP of Research at OpenAI, in a video call with journalists ahead of the launch earlier today.

                                      OpenAI positions GPT-5.5 as a fundamental redesign of how intelligence interacts with a computer’s operating system and professional software stacks.

                                      «What is really special about this model is how much more it can do with less guidance,» said OpenAI co-founder and president Greg Brockman on the same call. «It’s way more intuitive to use. It can look at an unclear problem and figure out what needs to happen next.»

                                      Brockman proceeded to emphasize the areas in which users can expect to see gains from using GPT-5.5 compared to OpenAI’s prior state-of-the-art model, GPT-5.4, which remains available (for now) to users and enterprises at half the API cost of its new successor.

                                      «It’s extremely good at coding,» Brockman said of GPT-5.5. «It’s also great at broader computer work, computer use, scientific research—these kinds of applications that are very intelligent bottlenecks.»

                                      OpenAI CEO and-cofounder Sam Altman also weighed in on the launch and the company’s philosophy in a post on X, writing, in part: «We want our users to have access to the best technology and for everyone to have equal opportunity.»

                                      The model is available in two variants: GPT-5.5 and GPT-5.5 Pro, distinguished by the latter offering enhanced precision and specialized logic for handling the most rigorous cognitive demands.

                                      While the standard version serves as the versatile flagship for general intelligence tasks, the Pro model is architected specifically for high-stakes environments such as legal research, data science, and advanced business analytics where accuracy is paramount. This premium tier provides noticeably more comprehensive and better-structured responses, supported by specialized latency optimizations that ensure high-quality performance during complex, multi-step workflows.

                                      Unfortunately for third-party software developers, API access is not yet available for either GPT-5.5 nor GPT-5.5 Pro and will be coming «very soon,» according to the company’s announcement blog post.

                                      «API deployments require different safeguards and we are working closely with partners and customers on the safety and security requirements for serving it at scale,» OpenAI writes.

                                      For the time being, GPT-5.5 is available only to paying subscribers of the ChatGPT Plus ($20 monthly), Pro ($100-$200 monthly), Business, and Enterprise users, with GPT-5.5 Pro access starting at the Pro tier and upwards.

                                      A focus on agency

                                      At the core of GPT-5.5 is a focus on «agentic» performance—specifically in coding, computer use, and scientific research.

                                      Unlike its predecessors, which often required granular, step-by-step prompting to avoid «hallucinating» a path forward, GPT-5.5 is designed to handle messy, multi-part tasks autonomously.

                                      It excels at researching online, debugging complex codebases, and moving between documents and spreadsheets without human intervention.

                                      One of the most significant technical leaps is the model’s efficiency. While larger models typically suffer from increased latency, GPT-5.5 matches the per-token latency of the previous GPT-5.4 while delivering a higher level of intelligence.

                                      This was achieved through a deep hardware-software co-design. OpenAI served GPT-5.5 on NVIDIA GB200 and GB300 NVL72 systems, utilizing custom heuristic algorithms—written by the AI itself—to partition and balance work across GPU cores.

                                      This optimization reportedly increased token generation speeds by over 20%.For high-stakes reasoning, the «GPT-5.5 Thinking» mode in ChatGPT provides smarter, more concise answers by allowing the model more internal «compute time» to verify its own assumptions before responding.

                                      This capability is particularly visible in the model’s performance on «Expert-SWE,» an internal OpenAI benchmark for long-horizon coding tasks with a median human completion time of 20 hours. GPT-5.5 notably outperformed GPT-5.4 on this metric while using significantly fewer tokens.

                                      Benchmarks show OpenAI has retaken the lead in most powerful publicly available LLM over Claude Opus 4.7 (but the unreleased Mythos still outperforms it)

                                      The market for leading U.S.-made frontier models has become an increasingly tight race between OpenAI, Anthropic, and Google.

                                      Literally a week ago to the date, OpenAI rival Anthropic released Opus 4.7, its most powerful generally available model, to the public, taking over the leaderboard in terms of the number of third-party benchmark tests in which it has the lead.

                                      Yet today, GPT-5.5 has surpassed it and even Anthropic’s heavily restricted, more powerful model Claude Mythos Preview, albeit only on one benchmark, Terminal-Bench 2.0, which tests «a model’s ability to navigate and complete tasks in a sandboxed terminal environment.»

                                      GPT-5.5 achieved 82.7% accuracy on Terminal-Bench 2.0, easily surpassing Opus 4.7 (69.4%) and narrowly beating the Mythos Preview (82.0%).

                                      OpenAI GPT-5.5 benchmark comparison table. Credit: OpenAI

                                      However, in multidisciplinary reasoning without tools, the landscape is more competitive. On Humanity’s Last Exam without tools, GPT-5.5 Pro scored 43.1%, trailing behind Opus 4.7 (46.9%) and Mythos Preview (56.8%).

                                      Benchmark

                                      GPT-5.5

                                      Claude Opus 4.7

                                      Gemini 3.1 Pro

                                      Mythos Preview*

                                      Terminal-Bench 2.0

                                      82.7

                                      69.4

                                      68.5

                                      82.0

                                      Expert-SWE (Internal)

                                      73.1

                                      —

                                      —

                                      —

                                      GDPval (wins or ties)

                                      84.9

                                      80.3

                                      67.3

                                      —

                                      OSWorld-Verified

                                      78.7

                                      78.0

                                      —

                                      79.6

                                      Toolathlon

                                      55.6

                                      —

                                      48.8

                                      —

                                      BrowseComp

                                      84.4

                                      79.3

                                      85.9

                                      86.9

                                      FrontierMath Tier 1–3

                                      51.7

                                      43.8

                                      36.9

                                      —

                                      FrontierMath Tier 4

                                      35.4

                                      22.9

                                      16.7

                                      —

                                      CyberGym

                                      81.8

                                      73.1

                                      —

                                      83.1

                                      Tau2-bench Telecom (original prompts)

                                      98.0

                                      —

                                      —

                                      —

                                      OfficeQA Pro

                                      54.1

                                      43.6

                                      18.1

                                      —

                                      Investment Banking Modeling Tasks (Internal)

                                      88.5

                                      —

                                      —

                                      —

                                      MMMU Pro (no tools)

                                      81.2

                                      —

                                      80.5

                                      —

                                      MMMU Pro (with tools)

                                      83.2

                                      —

                                      —

                                      —

                                      GeneBench

                                      25.0

                                      —

                                      —

                                      —

                                      BixBench

                                      80.5

                                      —

                                      —

                                      —

                                      Capture-the-Flags challenge tasks (Internal)

                                      88.1

                                      —

                                      —

                                      —

                                      ARC-AGI-2 (Verified)

                                      85.0

                                      75.8

                                      77.1

                                      —

                                      SWE-bench Pro (Public)

                                      58.6

                                      64.3

                                      54.2

                                      77.8

                                      This suggests that while OpenAI is winning on «computer use» and «agency,» other models may still hold an edge in pure, zero-shot academic knowledge.

                                      It is important to clarify that Mythos Preview is not a generally available product; Anthropic has classified it as a strategic defensive asset due to its high cybersecurity risks, restricting its access to a small, limited audience of trusted partners and government agencies.

                                      Because Mythos is excluded from broad commercial use, the primary market competition remains between GPT-5.5, Gemini 3.1 Pro, and Claude Opus 4.7.

                                      So when it comes to models that the general public can access, GPT-5.5 has retaken the crown for OpenAI, achieving the state-of-the-art across 14 benchmarks compared to 4 for Claude Opus 4.7 and 2 for Google Gemini 3.1 Pro.

                                      It dominates in agentic computer use, economic knowledge work (GDPval), specialized cybersecurity (CyberGym), and complex mathematics (Frontier Math).

                                      In comparison, Claude Opus 4.7 leads on software engineering and reasoning without tools, while Gemini 3.1 Pro leads in three categories, specifically excelling in academic reasoning and financial analysis.

                                      Increased costs for users

                                      The shift in intelligence comes with a significant price increase for API developers, according to material OpenAI shared ahead of the model’s public release.

                                      OpenAI has effectively doubled the entry price for its flagship model compared to the previous generation, and again double it from there for the most-cutting edge variant of the model, GPT-5.5 Pro:

                                      Model

                                      Input Price (per 1M tokens)

                                      Output Price (per 1M tokens)

                                      GPT-5.4

                                      $2.50

                                      $15.00

                                      GPT-5.5

                                      $5.00

                                      $30.00

                                      GPT-5.5 Pro

                                      $30.00

                                      $180.00

                                      To mitigate these costs, OpenAI emphasizes that GPT-5.5 is more «token efficient,» meaning it uses fewer tokens to complete the same task compared to GPT-5.4.

                                      For users requiring speed over depth, OpenAI also introduced a Fast mode in Codex, which generates tokens 1.5x faster but at a 2.5x price premium.

                                      The «mini» and «nano» tiers seen in the GPT-5.4 era (priced at $0.75 and $0.20 per 1M input tokens respectively) currently have no GPT-5.5 equivalent, though the company notes that GPT-5.5 is rolling out to all subscription tiers, including Plus, Pro, and Enterprise.

                                      Licensing and the ‘cyber-permissive’ frontier

                                      OpenAI’s approach to safety and licensing for GPT-5.5 introduces a novel concept: Trusted Access for Cyber. Because the model is now capable of identifying and patching advanced security vulnerabilities, OpenAI has implemented stricter «cyber-risk classifiers» for general users.

                                      For legitimate security professionals, however, OpenAI is offering a specialized «cyber-permissive» license. This program allows verified defenders—those responsible for critical infrastructure like power grids or water supplies—to use models like GPT-5.4-Cyber or unrestricted versions of GPT-5.5 with fewer refusals for security-related prompts.

                                      This dual-use framework acknowledges that while AI can accelerate cyber defense, it can also be weaponized. Under OpenAI’s Preparedness Framework, GPT-5.5 is classified as «High» risk for biological and cybersecurity capabilities.

                                      To manage this, API deployments currently require different safeguards than the consumer-facing ChatGPT, and OpenAI is working with government partners to ensure these tools are used to strengthen—not undermine—digital resilience.

                                      Initial reactions: losing access feels like having a ‘limp amputated’

                                      The early feedback from power users and engineers suggests that GPT-5.5 has crossed a psychological threshold in AI utility. For developers, the model’s ability to maintain «conceptual clarity» across massive codebases is its standout feature.

                                      «The first coding model I’ve used that has serious conceptual clarity,» noted Dan Shipper, CEO of Every.

                                      Shipper tested the model by asking it to debug a complex system failure that had previously required a team of human engineers to rewrite; GPT-5.5 produced the same fix autonomously. Similarly, Pietro Schirano, CEO of MagicPath, described a «step change» in performance when the model successfully merged a branch with hundreds of refactor changes into a main branch in a single, 20-minute pass.Perhaps the most visceral reaction came from an anonymous engineer at NVIDIA, who had early access to the model:

                                      «Losing access to GPT-5.5 feels like I’ve had a limb amputated».

                                      This sentiment is echoed in the scientific community. Derya Unutmaz, a professor at the Jackson Laboratory for Genomic Medicine, used GPT-5.5 Pro to analyze a dataset of 28,000 genes, producing a report in minutes that would have normally taken his team months.

                                      Brandon White, CEO of Axiom Bio, went further, stating that if OpenAI continues this pace, «the foundations of drug discovery will change by the end of the year».

                                      GPT-5.5 is more than an incremental update; it is a tool designed for a world where humans delegate entire workflows rather than single prompts. While the costs are higher and the safety guardrails tighter, the performance gains in agentic work suggest that AI is finally moving from the chat box and into the operating system.

                                      Perhaps most astonishingly of all, it’s not even hearing the end of the scaling limits — whereupon models are trained on more and more GPUs — according to researchers at the company.

                                      «We actually still have headroom to train significantly smarter models than this,» said OpenAI chief scientist Jakub Pachocki.

                                      Tour Cayo Arena Día Feriado Tour Cayo Arena Día Feriado Tour Cayo Arena Día Feriado

                                      After months of rumors and reports that OpenAI was developing a new, more powerful AI large language model for use in ChatGPT and through its application programming interface (API), allegedly codenamed «Spud» internally, the company has today unveiled its latest offering under the more formal name GPT-5.5.

                                      And to likely no one’s surprise, it’s hardly a «potato» in the disparaging sense of the word: GPT-5.5 retakes the lead for OpenAI in generally available LLMs, coming ahead of rivals Anthropic’s and Google’s latest public offerings, and even beating the private Anthropic Claude Mythos Preview model narrowly on one benchmark (essentially a statistical tie).

                                      «It’s definitely our strongest model yet on coding, both measured by benchmarks and based on the feedback that we’ve gotten from trusted partners, as well as our own experience,» explained Amelia «Mia» Glaese, VP of Research at OpenAI, in a video call with journalists ahead of the launch earlier today.

                                      OpenAI positions GPT-5.5 as a fundamental redesign of how intelligence interacts with a computer’s operating system and professional software stacks.

                                      «What is really special about this model is how much more it can do with less guidance,» said OpenAI co-founder and president Greg Brockman on the same call. «It’s way more intuitive to use. It can look at an unclear problem and figure out what needs to happen next.»

                                      Brockman proceeded to emphasize the areas in which users can expect to see gains from using GPT-5.5 compared to OpenAI’s prior state-of-the-art model, GPT-5.4, which remains available (for now) to users and enterprises at half the API cost of its new successor.

                                      «It’s extremely good at coding,» Brockman said of GPT-5.5. «It’s also great at broader computer work, computer use, scientific research—these kinds of applications that are very intelligent bottlenecks.»

                                      OpenAI CEO and-cofounder Sam Altman also weighed in on the launch and the company’s philosophy in a post on X, writing, in part: «We want our users to have access to the best technology and for everyone to have equal opportunity.»

                                      The model is available in two variants: GPT-5.5 and GPT-5.5 Pro, distinguished by the latter offering enhanced precision and specialized logic for handling the most rigorous cognitive demands.

                                      While the standard version serves as the versatile flagship for general intelligence tasks, the Pro model is architected specifically for high-stakes environments such as legal research, data science, and advanced business analytics where accuracy is paramount. This premium tier provides noticeably more comprehensive and better-structured responses, supported by specialized latency optimizations that ensure high-quality performance during complex, multi-step workflows.

                                      Unfortunately for third-party software developers, API access is not yet available for either GPT-5.5 nor GPT-5.5 Pro and will be coming «very soon,» according to the company’s announcement blog post.

                                      «API deployments require different safeguards and we are working closely with partners and customers on the safety and security requirements for serving it at scale,» OpenAI writes.

                                      For the time being, GPT-5.5 is available only to paying subscribers of the ChatGPT Plus ($20 monthly), Pro ($100-$200 monthly), Business, and Enterprise users, with GPT-5.5 Pro access starting at the Pro tier and upwards.

                                      A focus on agency

                                      At the core of GPT-5.5 is a focus on «agentic» performance—specifically in coding, computer use, and scientific research.

                                      Unlike its predecessors, which often required granular, step-by-step prompting to avoid «hallucinating» a path forward, GPT-5.5 is designed to handle messy, multi-part tasks autonomously.

                                      It excels at researching online, debugging complex codebases, and moving between documents and spreadsheets without human intervention.

                                      One of the most significant technical leaps is the model’s efficiency. While larger models typically suffer from increased latency, GPT-5.5 matches the per-token latency of the previous GPT-5.4 while delivering a higher level of intelligence.

                                      This was achieved through a deep hardware-software co-design. OpenAI served GPT-5.5 on NVIDIA GB200 and GB300 NVL72 systems, utilizing custom heuristic algorithms—written by the AI itself—to partition and balance work across GPU cores.

                                      This optimization reportedly increased token generation speeds by over 20%.For high-stakes reasoning, the «GPT-5.5 Thinking» mode in ChatGPT provides smarter, more concise answers by allowing the model more internal «compute time» to verify its own assumptions before responding.

                                      This capability is particularly visible in the model’s performance on «Expert-SWE,» an internal OpenAI benchmark for long-horizon coding tasks with a median human completion time of 20 hours. GPT-5.5 notably outperformed GPT-5.4 on this metric while using significantly fewer tokens.

                                      Benchmarks show OpenAI has retaken the lead in most powerful publicly available LLM over Claude Opus 4.7 (but the unreleased Mythos still outperforms it)

                                      The market for leading U.S.-made frontier models has become an increasingly tight race between OpenAI, Anthropic, and Google.

                                      Literally a week ago to the date, OpenAI rival Anthropic released Opus 4.7, its most powerful generally available model, to the public, taking over the leaderboard in terms of the number of third-party benchmark tests in which it has the lead.

                                      Yet today, GPT-5.5 has surpassed it and even Anthropic’s heavily restricted, more powerful model Claude Mythos Preview, albeit only on one benchmark, Terminal-Bench 2.0, which tests «a model’s ability to navigate and complete tasks in a sandboxed terminal environment.»

                                      GPT-5.5 achieved 82.7% accuracy on Terminal-Bench 2.0, easily surpassing Opus 4.7 (69.4%) and narrowly beating the Mythos Preview (82.0%).

                                      OpenAI GPT-5.5 benchmark comparison table. Credit: OpenAI

                                      However, in multidisciplinary reasoning without tools, the landscape is more competitive. On Humanity’s Last Exam without tools, GPT-5.5 Pro scored 43.1%, trailing behind Opus 4.7 (46.9%) and Mythos Preview (56.8%).

                                      Benchmark

                                      GPT-5.5

                                      Claude Opus 4.7

                                      Gemini 3.1 Pro

                                      Mythos Preview*

                                      Terminal-Bench 2.0

                                      82.7

                                      69.4

                                      68.5

                                      82.0

                                      Expert-SWE (Internal)

                                      73.1

                                      —

                                      —

                                      —

                                      GDPval (wins or ties)

                                      84.9

                                      80.3

                                      67.3

                                      —

                                      OSWorld-Verified

                                      78.7

                                      78.0

                                      —

                                      79.6

                                      Toolathlon

                                      55.6

                                      —

                                      48.8

                                      —

                                      BrowseComp

                                      84.4

                                      79.3

                                      85.9

                                      86.9

                                      FrontierMath Tier 1–3

                                      51.7

                                      43.8

                                      36.9

                                      —

                                      FrontierMath Tier 4

                                      35.4

                                      22.9

                                      16.7

                                      —

                                      CyberGym

                                      81.8

                                      73.1

                                      —

                                      83.1

                                      Tau2-bench Telecom (original prompts)

                                      98.0

                                      —

                                      —

                                      —

                                      OfficeQA Pro

                                      54.1

                                      43.6

                                      18.1

                                      —

                                      Investment Banking Modeling Tasks (Internal)

                                      88.5

                                      —

                                      —

                                      —

                                      MMMU Pro (no tools)

                                      81.2

                                      —

                                      80.5

                                      —

                                      MMMU Pro (with tools)

                                      83.2

                                      —

                                      —

                                      —

                                      GeneBench

                                      25.0

                                      —

                                      —

                                      —

                                      BixBench

                                      80.5

                                      —

                                      —

                                      —

                                      Capture-the-Flags challenge tasks (Internal)

                                      88.1

                                      —

                                      —

                                      —

                                      ARC-AGI-2 (Verified)

                                      85.0

                                      75.8

                                      77.1

                                      —

                                      SWE-bench Pro (Public)

                                      58.6

                                      64.3

                                      54.2

                                      77.8

                                      This suggests that while OpenAI is winning on «computer use» and «agency,» other models may still hold an edge in pure, zero-shot academic knowledge.

                                      It is important to clarify that Mythos Preview is not a generally available product; Anthropic has classified it as a strategic defensive asset due to its high cybersecurity risks, restricting its access to a small, limited audience of trusted partners and government agencies.

                                      Because Mythos is excluded from broad commercial use, the primary market competition remains between GPT-5.5, Gemini 3.1 Pro, and Claude Opus 4.7.

                                      So when it comes to models that the general public can access, GPT-5.5 has retaken the crown for OpenAI, achieving the state-of-the-art across 14 benchmarks compared to 4 for Claude Opus 4.7 and 2 for Google Gemini 3.1 Pro.

                                      It dominates in agentic computer use, economic knowledge work (GDPval), specialized cybersecurity (CyberGym), and complex mathematics (Frontier Math).

                                      In comparison, Claude Opus 4.7 leads on software engineering and reasoning without tools, while Gemini 3.1 Pro leads in three categories, specifically excelling in academic reasoning and financial analysis.

                                      Increased costs for users

                                      The shift in intelligence comes with a significant price increase for API developers, according to material OpenAI shared ahead of the model’s public release.

                                      OpenAI has effectively doubled the entry price for its flagship model compared to the previous generation, and again double it from there for the most-cutting edge variant of the model, GPT-5.5 Pro:

                                      Model

                                      Input Price (per 1M tokens)

                                      Output Price (per 1M tokens)

                                      GPT-5.4

                                      $2.50

                                      $15.00

                                      GPT-5.5

                                      $5.00

                                      $30.00

                                      GPT-5.5 Pro

                                      $30.00

                                      $180.00

                                      To mitigate these costs, OpenAI emphasizes that GPT-5.5 is more «token efficient,» meaning it uses fewer tokens to complete the same task compared to GPT-5.4.

                                      For users requiring speed over depth, OpenAI also introduced a Fast mode in Codex, which generates tokens 1.5x faster but at a 2.5x price premium.

                                      The «mini» and «nano» tiers seen in the GPT-5.4 era (priced at $0.75 and $0.20 per 1M input tokens respectively) currently have no GPT-5.5 equivalent, though the company notes that GPT-5.5 is rolling out to all subscription tiers, including Plus, Pro, and Enterprise.

                                      Licensing and the ‘cyber-permissive’ frontier

                                      OpenAI’s approach to safety and licensing for GPT-5.5 introduces a novel concept: Trusted Access for Cyber. Because the model is now capable of identifying and patching advanced security vulnerabilities, OpenAI has implemented stricter «cyber-risk classifiers» for general users.

                                      For legitimate security professionals, however, OpenAI is offering a specialized «cyber-permissive» license. This program allows verified defenders—those responsible for critical infrastructure like power grids or water supplies—to use models like GPT-5.4-Cyber or unrestricted versions of GPT-5.5 with fewer refusals for security-related prompts.

                                      This dual-use framework acknowledges that while AI can accelerate cyber defense, it can also be weaponized. Under OpenAI’s Preparedness Framework, GPT-5.5 is classified as «High» risk for biological and cybersecurity capabilities.

                                      To manage this, API deployments currently require different safeguards than the consumer-facing ChatGPT, and OpenAI is working with government partners to ensure these tools are used to strengthen—not undermine—digital resilience.

                                      Initial reactions: losing access feels like having a ‘limp amputated’

                                      The early feedback from power users and engineers suggests that GPT-5.5 has crossed a psychological threshold in AI utility. For developers, the model’s ability to maintain «conceptual clarity» across massive codebases is its standout feature.

                                      «The first coding model I’ve used that has serious conceptual clarity,» noted Dan Shipper, CEO of Every.

                                      Shipper tested the model by asking it to debug a complex system failure that had previously required a team of human engineers to rewrite; GPT-5.5 produced the same fix autonomously. Similarly, Pietro Schirano, CEO of MagicPath, described a «step change» in performance when the model successfully merged a branch with hundreds of refactor changes into a main branch in a single, 20-minute pass.Perhaps the most visceral reaction came from an anonymous engineer at NVIDIA, who had early access to the model:

                                      «Losing access to GPT-5.5 feels like I’ve had a limb amputated».

                                      This sentiment is echoed in the scientific community. Derya Unutmaz, a professor at the Jackson Laboratory for Genomic Medicine, used GPT-5.5 Pro to analyze a dataset of 28,000 genes, producing a report in minutes that would have normally taken his team months.

                                      Brandon White, CEO of Axiom Bio, went further, stating that if OpenAI continues this pace, «the foundations of drug discovery will change by the end of the year».

                                      GPT-5.5 is more than an incremental update; it is a tool designed for a world where humans delegate entire workflows rather than single prompts. While the costs are higher and the safety guardrails tighter, the performance gains in agentic work suggest that AI is finally moving from the chat box and into the operating system.

                                      Perhaps most astonishingly of all, it’s not even hearing the end of the scaling limits — whereupon models are trained on more and more GPUs — according to researchers at the company.

                                      «We actually still have headroom to train significantly smarter models than this,» said OpenAI chief scientist Jakub Pachocki.

                                      Tours Colombia Todo el año Tours Colombia Todo el año Tours Colombia Todo el año

                                      After months of rumors and reports that OpenAI was developing a new, more powerful AI large language model for use in ChatGPT and through its application programming interface (API), allegedly codenamed «Spud» internally, the company has today unveiled its latest offering under the more formal name GPT-5.5.

                                      And to likely no one’s surprise, it’s hardly a «potato» in the disparaging sense of the word: GPT-5.5 retakes the lead for OpenAI in generally available LLMs, coming ahead of rivals Anthropic’s and Google’s latest public offerings, and even beating the private Anthropic Claude Mythos Preview model narrowly on one benchmark (essentially a statistical tie).

                                      «It’s definitely our strongest model yet on coding, both measured by benchmarks and based on the feedback that we’ve gotten from trusted partners, as well as our own experience,» explained Amelia «Mia» Glaese, VP of Research at OpenAI, in a video call with journalists ahead of the launch earlier today.

                                      OpenAI positions GPT-5.5 as a fundamental redesign of how intelligence interacts with a computer’s operating system and professional software stacks.

                                      «What is really special about this model is how much more it can do with less guidance,» said OpenAI co-founder and president Greg Brockman on the same call. «It’s way more intuitive to use. It can look at an unclear problem and figure out what needs to happen next.»

                                      Brockman proceeded to emphasize the areas in which users can expect to see gains from using GPT-5.5 compared to OpenAI’s prior state-of-the-art model, GPT-5.4, which remains available (for now) to users and enterprises at half the API cost of its new successor.

                                      «It’s extremely good at coding,» Brockman said of GPT-5.5. «It’s also great at broader computer work, computer use, scientific research—these kinds of applications that are very intelligent bottlenecks.»

                                      OpenAI CEO and-cofounder Sam Altman also weighed in on the launch and the company’s philosophy in a post on X, writing, in part: «We want our users to have access to the best technology and for everyone to have equal opportunity.»

                                      The model is available in two variants: GPT-5.5 and GPT-5.5 Pro, distinguished by the latter offering enhanced precision and specialized logic for handling the most rigorous cognitive demands.

                                      While the standard version serves as the versatile flagship for general intelligence tasks, the Pro model is architected specifically for high-stakes environments such as legal research, data science, and advanced business analytics where accuracy is paramount. This premium tier provides noticeably more comprehensive and better-structured responses, supported by specialized latency optimizations that ensure high-quality performance during complex, multi-step workflows.

                                      Unfortunately for third-party software developers, API access is not yet available for either GPT-5.5 nor GPT-5.5 Pro and will be coming «very soon,» according to the company’s announcement blog post.

                                      «API deployments require different safeguards and we are working closely with partners and customers on the safety and security requirements for serving it at scale,» OpenAI writes.

                                      For the time being, GPT-5.5 is available only to paying subscribers of the ChatGPT Plus ($20 monthly), Pro ($100-$200 monthly), Business, and Enterprise users, with GPT-5.5 Pro access starting at the Pro tier and upwards.

                                      A focus on agency

                                      At the core of GPT-5.5 is a focus on «agentic» performance—specifically in coding, computer use, and scientific research.

                                      Unlike its predecessors, which often required granular, step-by-step prompting to avoid «hallucinating» a path forward, GPT-5.5 is designed to handle messy, multi-part tasks autonomously.

                                      It excels at researching online, debugging complex codebases, and moving between documents and spreadsheets without human intervention.

                                      One of the most significant technical leaps is the model’s efficiency. While larger models typically suffer from increased latency, GPT-5.5 matches the per-token latency of the previous GPT-5.4 while delivering a higher level of intelligence.

                                      This was achieved through a deep hardware-software co-design. OpenAI served GPT-5.5 on NVIDIA GB200 and GB300 NVL72 systems, utilizing custom heuristic algorithms—written by the AI itself—to partition and balance work across GPU cores.

                                      This optimization reportedly increased token generation speeds by over 20%.For high-stakes reasoning, the «GPT-5.5 Thinking» mode in ChatGPT provides smarter, more concise answers by allowing the model more internal «compute time» to verify its own assumptions before responding.

                                      This capability is particularly visible in the model’s performance on «Expert-SWE,» an internal OpenAI benchmark for long-horizon coding tasks with a median human completion time of 20 hours. GPT-5.5 notably outperformed GPT-5.4 on this metric while using significantly fewer tokens.

                                      Benchmarks show OpenAI has retaken the lead in most powerful publicly available LLM over Claude Opus 4.7 (but the unreleased Mythos still outperforms it)

                                      The market for leading U.S.-made frontier models has become an increasingly tight race between OpenAI, Anthropic, and Google.

                                      Literally a week ago to the date, OpenAI rival Anthropic released Opus 4.7, its most powerful generally available model, to the public, taking over the leaderboard in terms of the number of third-party benchmark tests in which it has the lead.

                                      Yet today, GPT-5.5 has surpassed it and even Anthropic’s heavily restricted, more powerful model Claude Mythos Preview, albeit only on one benchmark, Terminal-Bench 2.0, which tests «a model’s ability to navigate and complete tasks in a sandboxed terminal environment.»

                                      GPT-5.5 achieved 82.7% accuracy on Terminal-Bench 2.0, easily surpassing Opus 4.7 (69.4%) and narrowly beating the Mythos Preview (82.0%).

                                      OpenAI GPT-5.5 benchmark comparison table. Credit: OpenAI

                                      However, in multidisciplinary reasoning without tools, the landscape is more competitive. On Humanity’s Last Exam without tools, GPT-5.5 Pro scored 43.1%, trailing behind Opus 4.7 (46.9%) and Mythos Preview (56.8%).

                                      Benchmark

                                      GPT-5.5

                                      Claude Opus 4.7

                                      Gemini 3.1 Pro

                                      Mythos Preview*

                                      Terminal-Bench 2.0

                                      82.7

                                      69.4

                                      68.5

                                      82.0

                                      Expert-SWE (Internal)

                                      73.1

                                      —

                                      —

                                      —

                                      GDPval (wins or ties)

                                      84.9

                                      80.3

                                      67.3

                                      —

                                      OSWorld-Verified

                                      78.7

                                      78.0

                                      —

                                      79.6

                                      Toolathlon

                                      55.6

                                      —

                                      48.8

                                      —

                                      BrowseComp

                                      84.4

                                      79.3

                                      85.9

                                      86.9

                                      FrontierMath Tier 1–3

                                      51.7

                                      43.8

                                      36.9

                                      —

                                      FrontierMath Tier 4

                                      35.4

                                      22.9

                                      16.7

                                      —

                                      CyberGym

                                      81.8

                                      73.1

                                      —

                                      83.1

                                      Tau2-bench Telecom (original prompts)

                                      98.0

                                      —

                                      —

                                      —

                                      OfficeQA Pro

                                      54.1

                                      43.6

                                      18.1

                                      —

                                      Investment Banking Modeling Tasks (Internal)

                                      88.5

                                      —

                                      —

                                      —

                                      MMMU Pro (no tools)

                                      81.2

                                      —

                                      80.5

                                      —

                                      MMMU Pro (with tools)

                                      83.2

                                      —

                                      —

                                      —

                                      GeneBench

                                      25.0

                                      —

                                      —

                                      —

                                      BixBench

                                      80.5

                                      —

                                      —

                                      —

                                      Capture-the-Flags challenge tasks (Internal)

                                      88.1

                                      —

                                      —

                                      —

                                      ARC-AGI-2 (Verified)

                                      85.0

                                      75.8

                                      77.1

                                      —

                                      SWE-bench Pro (Public)

                                      58.6

                                      64.3

                                      54.2

                                      77.8

                                      This suggests that while OpenAI is winning on «computer use» and «agency,» other models may still hold an edge in pure, zero-shot academic knowledge.

                                      It is important to clarify that Mythos Preview is not a generally available product; Anthropic has classified it as a strategic defensive asset due to its high cybersecurity risks, restricting its access to a small, limited audience of trusted partners and government agencies.

                                      Because Mythos is excluded from broad commercial use, the primary market competition remains between GPT-5.5, Gemini 3.1 Pro, and Claude Opus 4.7.

                                      So when it comes to models that the general public can access, GPT-5.5 has retaken the crown for OpenAI, achieving the state-of-the-art across 14 benchmarks compared to 4 for Claude Opus 4.7 and 2 for Google Gemini 3.1 Pro.

                                      It dominates in agentic computer use, economic knowledge work (GDPval), specialized cybersecurity (CyberGym), and complex mathematics (Frontier Math).

                                      In comparison, Claude Opus 4.7 leads on software engineering and reasoning without tools, while Gemini 3.1 Pro leads in three categories, specifically excelling in academic reasoning and financial analysis.

                                      Increased costs for users

                                      The shift in intelligence comes with a significant price increase for API developers, according to material OpenAI shared ahead of the model’s public release.

                                      OpenAI has effectively doubled the entry price for its flagship model compared to the previous generation, and again double it from there for the most-cutting edge variant of the model, GPT-5.5 Pro:

                                      Model

                                      Input Price (per 1M tokens)

                                      Output Price (per 1M tokens)

                                      GPT-5.4

                                      $2.50

                                      $15.00

                                      GPT-5.5

                                      $5.00

                                      $30.00

                                      GPT-5.5 Pro

                                      $30.00

                                      $180.00

                                      To mitigate these costs, OpenAI emphasizes that GPT-5.5 is more «token efficient,» meaning it uses fewer tokens to complete the same task compared to GPT-5.4.

                                      For users requiring speed over depth, OpenAI also introduced a Fast mode in Codex, which generates tokens 1.5x faster but at a 2.5x price premium.

                                      The «mini» and «nano» tiers seen in the GPT-5.4 era (priced at $0.75 and $0.20 per 1M input tokens respectively) currently have no GPT-5.5 equivalent, though the company notes that GPT-5.5 is rolling out to all subscription tiers, including Plus, Pro, and Enterprise.

                                      Licensing and the ‘cyber-permissive’ frontier

                                      OpenAI’s approach to safety and licensing for GPT-5.5 introduces a novel concept: Trusted Access for Cyber. Because the model is now capable of identifying and patching advanced security vulnerabilities, OpenAI has implemented stricter «cyber-risk classifiers» for general users.

                                      For legitimate security professionals, however, OpenAI is offering a specialized «cyber-permissive» license. This program allows verified defenders—those responsible for critical infrastructure like power grids or water supplies—to use models like GPT-5.4-Cyber or unrestricted versions of GPT-5.5 with fewer refusals for security-related prompts.

                                      This dual-use framework acknowledges that while AI can accelerate cyber defense, it can also be weaponized. Under OpenAI’s Preparedness Framework, GPT-5.5 is classified as «High» risk for biological and cybersecurity capabilities.

                                      To manage this, API deployments currently require different safeguards than the consumer-facing ChatGPT, and OpenAI is working with government partners to ensure these tools are used to strengthen—not undermine—digital resilience.

                                      Initial reactions: losing access feels like having a ‘limp amputated’

                                      The early feedback from power users and engineers suggests that GPT-5.5 has crossed a psychological threshold in AI utility. For developers, the model’s ability to maintain «conceptual clarity» across massive codebases is its standout feature.

                                      «The first coding model I’ve used that has serious conceptual clarity,» noted Dan Shipper, CEO of Every.

                                      Shipper tested the model by asking it to debug a complex system failure that had previously required a team of human engineers to rewrite; GPT-5.5 produced the same fix autonomously. Similarly, Pietro Schirano, CEO of MagicPath, described a «step change» in performance when the model successfully merged a branch with hundreds of refactor changes into a main branch in a single, 20-minute pass.Perhaps the most visceral reaction came from an anonymous engineer at NVIDIA, who had early access to the model:

                                      «Losing access to GPT-5.5 feels like I’ve had a limb amputated».

                                      This sentiment is echoed in the scientific community. Derya Unutmaz, a professor at the Jackson Laboratory for Genomic Medicine, used GPT-5.5 Pro to analyze a dataset of 28,000 genes, producing a report in minutes that would have normally taken his team months.

                                      Brandon White, CEO of Axiom Bio, went further, stating that if OpenAI continues this pace, «the foundations of drug discovery will change by the end of the year».

                                      GPT-5.5 is more than an incremental update; it is a tool designed for a world where humans delegate entire workflows rather than single prompts. While the costs are higher and the safety guardrails tighter, the performance gains in agentic work suggest that AI is finally moving from the chat box and into the operating system.

                                      Perhaps most astonishingly of all, it’s not even hearing the end of the scaling limits — whereupon models are trained on more and more GPUs — according to researchers at the company.

                                      «We actually still have headroom to train significantly smarter models than this,» said OpenAI chief scientist Jakub Pachocki.

                                      Tour Cayo Arena Día Feriado Tour Cayo Arena Día Feriado Tour Cayo Arena Día Feriado

                                      After months of rumors and reports that OpenAI was developing a new, more powerful AI large language model for use in ChatGPT and through its application programming interface (API), allegedly codenamed «Spud» internally, the company has today unveiled its latest offering under the more formal name GPT-5.5.

                                      And to likely no one’s surprise, it’s hardly a «potato» in the disparaging sense of the word: GPT-5.5 retakes the lead for OpenAI in generally available LLMs, coming ahead of rivals Anthropic’s and Google’s latest public offerings, and even beating the private Anthropic Claude Mythos Preview model narrowly on one benchmark (essentially a statistical tie).

                                      «It’s definitely our strongest model yet on coding, both measured by benchmarks and based on the feedback that we’ve gotten from trusted partners, as well as our own experience,» explained Amelia «Mia» Glaese, VP of Research at OpenAI, in a video call with journalists ahead of the launch earlier today.

                                      OpenAI positions GPT-5.5 as a fundamental redesign of how intelligence interacts with a computer’s operating system and professional software stacks.

                                      «What is really special about this model is how much more it can do with less guidance,» said OpenAI co-founder and president Greg Brockman on the same call. «It’s way more intuitive to use. It can look at an unclear problem and figure out what needs to happen next.»

                                      Brockman proceeded to emphasize the areas in which users can expect to see gains from using GPT-5.5 compared to OpenAI’s prior state-of-the-art model, GPT-5.4, which remains available (for now) to users and enterprises at half the API cost of its new successor.

                                      «It’s extremely good at coding,» Brockman said of GPT-5.5. «It’s also great at broader computer work, computer use, scientific research—these kinds of applications that are very intelligent bottlenecks.»

                                      OpenAI CEO and-cofounder Sam Altman also weighed in on the launch and the company’s philosophy in a post on X, writing, in part: «We want our users to have access to the best technology and for everyone to have equal opportunity.»

                                      The model is available in two variants: GPT-5.5 and GPT-5.5 Pro, distinguished by the latter offering enhanced precision and specialized logic for handling the most rigorous cognitive demands.

                                      While the standard version serves as the versatile flagship for general intelligence tasks, the Pro model is architected specifically for high-stakes environments such as legal research, data science, and advanced business analytics where accuracy is paramount. This premium tier provides noticeably more comprehensive and better-structured responses, supported by specialized latency optimizations that ensure high-quality performance during complex, multi-step workflows.

                                      Unfortunately for third-party software developers, API access is not yet available for either GPT-5.5 nor GPT-5.5 Pro and will be coming «very soon,» according to the company’s announcement blog post.

                                      «API deployments require different safeguards and we are working closely with partners and customers on the safety and security requirements for serving it at scale,» OpenAI writes.

                                      For the time being, GPT-5.5 is available only to paying subscribers of the ChatGPT Plus ($20 monthly), Pro ($100-$200 monthly), Business, and Enterprise users, with GPT-5.5 Pro access starting at the Pro tier and upwards.

                                      A focus on agency

                                      At the core of GPT-5.5 is a focus on «agentic» performance—specifically in coding, computer use, and scientific research.

                                      Unlike its predecessors, which often required granular, step-by-step prompting to avoid «hallucinating» a path forward, GPT-5.5 is designed to handle messy, multi-part tasks autonomously.

                                      It excels at researching online, debugging complex codebases, and moving between documents and spreadsheets without human intervention.

                                      One of the most significant technical leaps is the model’s efficiency. While larger models typically suffer from increased latency, GPT-5.5 matches the per-token latency of the previous GPT-5.4 while delivering a higher level of intelligence.

                                      This was achieved through a deep hardware-software co-design. OpenAI served GPT-5.5 on NVIDIA GB200 and GB300 NVL72 systems, utilizing custom heuristic algorithms—written by the AI itself—to partition and balance work across GPU cores.

                                      This optimization reportedly increased token generation speeds by over 20%.For high-stakes reasoning, the «GPT-5.5 Thinking» mode in ChatGPT provides smarter, more concise answers by allowing the model more internal «compute time» to verify its own assumptions before responding.

                                      This capability is particularly visible in the model’s performance on «Expert-SWE,» an internal OpenAI benchmark for long-horizon coding tasks with a median human completion time of 20 hours. GPT-5.5 notably outperformed GPT-5.4 on this metric while using significantly fewer tokens.

                                      Benchmarks show OpenAI has retaken the lead in most powerful publicly available LLM over Claude Opus 4.7 (but the unreleased Mythos still outperforms it)

                                      The market for leading U.S.-made frontier models has become an increasingly tight race between OpenAI, Anthropic, and Google.

                                      Literally a week ago to the date, OpenAI rival Anthropic released Opus 4.7, its most powerful generally available model, to the public, taking over the leaderboard in terms of the number of third-party benchmark tests in which it has the lead.

                                      Yet today, GPT-5.5 has surpassed it and even Anthropic’s heavily restricted, more powerful model Claude Mythos Preview, albeit only on one benchmark, Terminal-Bench 2.0, which tests «a model’s ability to navigate and complete tasks in a sandboxed terminal environment.»

                                      GPT-5.5 achieved 82.7% accuracy on Terminal-Bench 2.0, easily surpassing Opus 4.7 (69.4%) and narrowly beating the Mythos Preview (82.0%).

                                      OpenAI GPT-5.5 benchmark comparison table. Credit: OpenAI

                                      However, in multidisciplinary reasoning without tools, the landscape is more competitive. On Humanity’s Last Exam without tools, GPT-5.5 Pro scored 43.1%, trailing behind Opus 4.7 (46.9%) and Mythos Preview (56.8%).

                                      Benchmark

                                      GPT-5.5

                                      Claude Opus 4.7

                                      Gemini 3.1 Pro

                                      Mythos Preview*

                                      Terminal-Bench 2.0

                                      82.7

                                      69.4

                                      68.5

                                      82.0

                                      Expert-SWE (Internal)

                                      73.1

                                      —

                                      —

                                      —

                                      GDPval (wins or ties)

                                      84.9

                                      80.3

                                      67.3

                                      —

                                      OSWorld-Verified

                                      78.7

                                      78.0

                                      —

                                      79.6

                                      Toolathlon

                                      55.6

                                      —

                                      48.8

                                      —

                                      BrowseComp

                                      84.4

                                      79.3

                                      85.9

                                      86.9

                                      FrontierMath Tier 1–3

                                      51.7

                                      43.8

                                      36.9

                                      —

                                      FrontierMath Tier 4

                                      35.4

                                      22.9

                                      16.7

                                      —

                                      CyberGym

                                      81.8

                                      73.1

                                      —

                                      83.1

                                      Tau2-bench Telecom (original prompts)

                                      98.0

                                      —

                                      —

                                      —

                                      OfficeQA Pro

                                      54.1

                                      43.6

                                      18.1

                                      —

                                      Investment Banking Modeling Tasks (Internal)

                                      88.5

                                      —

                                      —

                                      —

                                      MMMU Pro (no tools)

                                      81.2

                                      —

                                      80.5

                                      —

                                      MMMU Pro (with tools)

                                      83.2

                                      —

                                      —

                                      —

                                      GeneBench

                                      25.0

                                      —

                                      —

                                      —

                                      BixBench

                                      80.5

                                      —

                                      —

                                      —

                                      Capture-the-Flags challenge tasks (Internal)

                                      88.1

                                      —

                                      —

                                      —

                                      ARC-AGI-2 (Verified)

                                      85.0

                                      75.8

                                      77.1

                                      —

                                      SWE-bench Pro (Public)

                                      58.6

                                      64.3

                                      54.2

                                      77.8

                                      This suggests that while OpenAI is winning on «computer use» and «agency,» other models may still hold an edge in pure, zero-shot academic knowledge.

                                      It is important to clarify that Mythos Preview is not a generally available product; Anthropic has classified it as a strategic defensive asset due to its high cybersecurity risks, restricting its access to a small, limited audience of trusted partners and government agencies.

                                      Because Mythos is excluded from broad commercial use, the primary market competition remains between GPT-5.5, Gemini 3.1 Pro, and Claude Opus 4.7.

                                      So when it comes to models that the general public can access, GPT-5.5 has retaken the crown for OpenAI, achieving the state-of-the-art across 14 benchmarks compared to 4 for Claude Opus 4.7 and 2 for Google Gemini 3.1 Pro.

                                      It dominates in agentic computer use, economic knowledge work (GDPval), specialized cybersecurity (CyberGym), and complex mathematics (Frontier Math).

                                      In comparison, Claude Opus 4.7 leads on software engineering and reasoning without tools, while Gemini 3.1 Pro leads in three categories, specifically excelling in academic reasoning and financial analysis.

                                      Increased costs for users

                                      The shift in intelligence comes with a significant price increase for API developers, according to material OpenAI shared ahead of the model’s public release.

                                      OpenAI has effectively doubled the entry price for its flagship model compared to the previous generation, and again double it from there for the most-cutting edge variant of the model, GPT-5.5 Pro:

                                      Model

                                      Input Price (per 1M tokens)

                                      Output Price (per 1M tokens)

                                      GPT-5.4

                                      $2.50

                                      $15.00

                                      GPT-5.5

                                      $5.00

                                      $30.00

                                      GPT-5.5 Pro

                                      $30.00

                                      $180.00

                                      To mitigate these costs, OpenAI emphasizes that GPT-5.5 is more «token efficient,» meaning it uses fewer tokens to complete the same task compared to GPT-5.4.

                                      For users requiring speed over depth, OpenAI also introduced a Fast mode in Codex, which generates tokens 1.5x faster but at a 2.5x price premium.

                                      The «mini» and «nano» tiers seen in the GPT-5.4 era (priced at $0.75 and $0.20 per 1M input tokens respectively) currently have no GPT-5.5 equivalent, though the company notes that GPT-5.5 is rolling out to all subscription tiers, including Plus, Pro, and Enterprise.

                                      Licensing and the ‘cyber-permissive’ frontier

                                      OpenAI’s approach to safety and licensing for GPT-5.5 introduces a novel concept: Trusted Access for Cyber. Because the model is now capable of identifying and patching advanced security vulnerabilities, OpenAI has implemented stricter «cyber-risk classifiers» for general users.

                                      For legitimate security professionals, however, OpenAI is offering a specialized «cyber-permissive» license. This program allows verified defenders—those responsible for critical infrastructure like power grids or water supplies—to use models like GPT-5.4-Cyber or unrestricted versions of GPT-5.5 with fewer refusals for security-related prompts.

                                      This dual-use framework acknowledges that while AI can accelerate cyber defense, it can also be weaponized. Under OpenAI’s Preparedness Framework, GPT-5.5 is classified as «High» risk for biological and cybersecurity capabilities.

                                      To manage this, API deployments currently require different safeguards than the consumer-facing ChatGPT, and OpenAI is working with government partners to ensure these tools are used to strengthen—not undermine—digital resilience.

                                      Initial reactions: losing access feels like having a ‘limp amputated’

                                      The early feedback from power users and engineers suggests that GPT-5.5 has crossed a psychological threshold in AI utility. For developers, the model’s ability to maintain «conceptual clarity» across massive codebases is its standout feature.

                                      «The first coding model I’ve used that has serious conceptual clarity,» noted Dan Shipper, CEO of Every.

                                      Shipper tested the model by asking it to debug a complex system failure that had previously required a team of human engineers to rewrite; GPT-5.5 produced the same fix autonomously. Similarly, Pietro Schirano, CEO of MagicPath, described a «step change» in performance when the model successfully merged a branch with hundreds of refactor changes into a main branch in a single, 20-minute pass.Perhaps the most visceral reaction came from an anonymous engineer at NVIDIA, who had early access to the model:

                                      «Losing access to GPT-5.5 feels like I’ve had a limb amputated».

                                      This sentiment is echoed in the scientific community. Derya Unutmaz, a professor at the Jackson Laboratory for Genomic Medicine, used GPT-5.5 Pro to analyze a dataset of 28,000 genes, producing a report in minutes that would have normally taken his team months.

                                      Brandon White, CEO of Axiom Bio, went further, stating that if OpenAI continues this pace, «the foundations of drug discovery will change by the end of the year».

                                      GPT-5.5 is more than an incremental update; it is a tool designed for a world where humans delegate entire workflows rather than single prompts. While the costs are higher and the safety guardrails tighter, the performance gains in agentic work suggest that AI is finally moving from the chat box and into the operating system.

                                      Perhaps most astonishingly of all, it’s not even hearing the end of the scaling limits — whereupon models are trained on more and more GPUs — according to researchers at the company.

                                      «We actually still have headroom to train significantly smarter models than this,» said OpenAI chief scientist Jakub Pachocki.

                                      ¡No te pierdas las noticias destacadas!

                                      Suscríbete y recibe las historias más importantes del día.

                                      Al suscribirte aceptas nuestros términos y condiciones y política de privacidad.

                                      After months of rumors and reports that OpenAI was developing a new, more powerful AI large language model for use in ChatGPT and through its application programming interface (API), allegedly codenamed «Spud» internally, the company has today unveiled its latest offering under the more formal name GPT-5.5.

                                      And to likely no one’s surprise, it’s hardly a «potato» in the disparaging sense of the word: GPT-5.5 retakes the lead for OpenAI in generally available LLMs, coming ahead of rivals Anthropic’s and Google’s latest public offerings, and even beating the private Anthropic Claude Mythos Preview model narrowly on one benchmark (essentially a statistical tie).

                                      «It’s definitely our strongest model yet on coding, both measured by benchmarks and based on the feedback that we’ve gotten from trusted partners, as well as our own experience,» explained Amelia «Mia» Glaese, VP of Research at OpenAI, in a video call with journalists ahead of the launch earlier today.

                                      OpenAI positions GPT-5.5 as a fundamental redesign of how intelligence interacts with a computer’s operating system and professional software stacks.

                                      «What is really special about this model is how much more it can do with less guidance,» said OpenAI co-founder and president Greg Brockman on the same call. «It’s way more intuitive to use. It can look at an unclear problem and figure out what needs to happen next.»

                                      Brockman proceeded to emphasize the areas in which users can expect to see gains from using GPT-5.5 compared to OpenAI’s prior state-of-the-art model, GPT-5.4, which remains available (for now) to users and enterprises at half the API cost of its new successor.

                                      «It’s extremely good at coding,» Brockman said of GPT-5.5. «It’s also great at broader computer work, computer use, scientific research—these kinds of applications that are very intelligent bottlenecks.»

                                      OpenAI CEO and-cofounder Sam Altman also weighed in on the launch and the company’s philosophy in a post on X, writing, in part: «We want our users to have access to the best technology and for everyone to have equal opportunity.»

                                      The model is available in two variants: GPT-5.5 and GPT-5.5 Pro, distinguished by the latter offering enhanced precision and specialized logic for handling the most rigorous cognitive demands.

                                      While the standard version serves as the versatile flagship for general intelligence tasks, the Pro model is architected specifically for high-stakes environments such as legal research, data science, and advanced business analytics where accuracy is paramount. This premium tier provides noticeably more comprehensive and better-structured responses, supported by specialized latency optimizations that ensure high-quality performance during complex, multi-step workflows.

                                      Unfortunately for third-party software developers, API access is not yet available for either GPT-5.5 nor GPT-5.5 Pro and will be coming «very soon,» according to the company’s announcement blog post.

                                      «API deployments require different safeguards and we are working closely with partners and customers on the safety and security requirements for serving it at scale,» OpenAI writes.

                                      For the time being, GPT-5.5 is available only to paying subscribers of the ChatGPT Plus ($20 monthly), Pro ($100-$200 monthly), Business, and Enterprise users, with GPT-5.5 Pro access starting at the Pro tier and upwards.

                                      A focus on agency

                                      At the core of GPT-5.5 is a focus on «agentic» performance—specifically in coding, computer use, and scientific research.

                                      Unlike its predecessors, which often required granular, step-by-step prompting to avoid «hallucinating» a path forward, GPT-5.5 is designed to handle messy, multi-part tasks autonomously.

                                      It excels at researching online, debugging complex codebases, and moving between documents and spreadsheets without human intervention.

                                      One of the most significant technical leaps is the model’s efficiency. While larger models typically suffer from increased latency, GPT-5.5 matches the per-token latency of the previous GPT-5.4 while delivering a higher level of intelligence.

                                      This was achieved through a deep hardware-software co-design. OpenAI served GPT-5.5 on NVIDIA GB200 and GB300 NVL72 systems, utilizing custom heuristic algorithms—written by the AI itself—to partition and balance work across GPU cores.

                                      This optimization reportedly increased token generation speeds by over 20%.For high-stakes reasoning, the «GPT-5.5 Thinking» mode in ChatGPT provides smarter, more concise answers by allowing the model more internal «compute time» to verify its own assumptions before responding.

                                      This capability is particularly visible in the model’s performance on «Expert-SWE,» an internal OpenAI benchmark for long-horizon coding tasks with a median human completion time of 20 hours. GPT-5.5 notably outperformed GPT-5.4 on this metric while using significantly fewer tokens.

                                      Benchmarks show OpenAI has retaken the lead in most powerful publicly available LLM over Claude Opus 4.7 (but the unreleased Mythos still outperforms it)

                                      The market for leading U.S.-made frontier models has become an increasingly tight race between OpenAI, Anthropic, and Google.

                                      Literally a week ago to the date, OpenAI rival Anthropic released Opus 4.7, its most powerful generally available model, to the public, taking over the leaderboard in terms of the number of third-party benchmark tests in which it has the lead.

                                      Yet today, GPT-5.5 has surpassed it and even Anthropic’s heavily restricted, more powerful model Claude Mythos Preview, albeit only on one benchmark, Terminal-Bench 2.0, which tests «a model’s ability to navigate and complete tasks in a sandboxed terminal environment.»

                                      GPT-5.5 achieved 82.7% accuracy on Terminal-Bench 2.0, easily surpassing Opus 4.7 (69.4%) and narrowly beating the Mythos Preview (82.0%).

                                      OpenAI GPT-5.5 benchmark comparison table. Credit: OpenAI

                                      However, in multidisciplinary reasoning without tools, the landscape is more competitive. On Humanity’s Last Exam without tools, GPT-5.5 Pro scored 43.1%, trailing behind Opus 4.7 (46.9%) and Mythos Preview (56.8%).

                                      Benchmark

                                      GPT-5.5

                                      Claude Opus 4.7

                                      Gemini 3.1 Pro

                                      Mythos Preview*

                                      Terminal-Bench 2.0

                                      82.7

                                      69.4

                                      68.5

                                      82.0

                                      Expert-SWE (Internal)

                                      73.1

                                      —

                                      —

                                      —

                                      GDPval (wins or ties)

                                      84.9

                                      80.3

                                      67.3

                                      —

                                      OSWorld-Verified

                                      78.7

                                      78.0

                                      —

                                      79.6

                                      Toolathlon

                                      55.6

                                      —

                                      48.8

                                      —

                                      BrowseComp

                                      84.4

                                      79.3

                                      85.9

                                      86.9

                                      FrontierMath Tier 1–3

                                      51.7

                                      43.8

                                      36.9

                                      —

                                      FrontierMath Tier 4

                                      35.4

                                      22.9

                                      16.7

                                      —

                                      CyberGym

                                      81.8

                                      73.1

                                      —

                                      83.1

                                      Tau2-bench Telecom (original prompts)

                                      98.0

                                      —

                                      —

                                      —

                                      OfficeQA Pro

                                      54.1

                                      43.6

                                      18.1

                                      —

                                      Investment Banking Modeling Tasks (Internal)

                                      88.5

                                      —

                                      —

                                      —

                                      MMMU Pro (no tools)

                                      81.2

                                      —

                                      80.5

                                      —

                                      MMMU Pro (with tools)

                                      83.2

                                      —

                                      —

                                      —

                                      GeneBench

                                      25.0

                                      —

                                      —

                                      —

                                      BixBench

                                      80.5

                                      —

                                      —

                                      —

                                      Capture-the-Flags challenge tasks (Internal)

                                      88.1

                                      —

                                      —

                                      —

                                      ARC-AGI-2 (Verified)

                                      85.0

                                      75.8

                                      77.1

                                      —

                                      SWE-bench Pro (Public)

                                      58.6

                                      64.3

                                      54.2

                                      77.8

                                      This suggests that while OpenAI is winning on «computer use» and «agency,» other models may still hold an edge in pure, zero-shot academic knowledge.

                                      It is important to clarify that Mythos Preview is not a generally available product; Anthropic has classified it as a strategic defensive asset due to its high cybersecurity risks, restricting its access to a small, limited audience of trusted partners and government agencies.

                                      Because Mythos is excluded from broad commercial use, the primary market competition remains between GPT-5.5, Gemini 3.1 Pro, and Claude Opus 4.7.

                                      So when it comes to models that the general public can access, GPT-5.5 has retaken the crown for OpenAI, achieving the state-of-the-art across 14 benchmarks compared to 4 for Claude Opus 4.7 and 2 for Google Gemini 3.1 Pro.

                                      It dominates in agentic computer use, economic knowledge work (GDPval), specialized cybersecurity (CyberGym), and complex mathematics (Frontier Math).

                                      In comparison, Claude Opus 4.7 leads on software engineering and reasoning without tools, while Gemini 3.1 Pro leads in three categories, specifically excelling in academic reasoning and financial analysis.

                                      Increased costs for users

                                      The shift in intelligence comes with a significant price increase for API developers, according to material OpenAI shared ahead of the model’s public release.

                                      OpenAI has effectively doubled the entry price for its flagship model compared to the previous generation, and again double it from there for the most-cutting edge variant of the model, GPT-5.5 Pro:

                                      Model

                                      Input Price (per 1M tokens)

                                      Output Price (per 1M tokens)

                                      GPT-5.4

                                      $2.50

                                      $15.00

                                      GPT-5.5

                                      $5.00

                                      $30.00

                                      GPT-5.5 Pro

                                      $30.00

                                      $180.00

                                      To mitigate these costs, OpenAI emphasizes that GPT-5.5 is more «token efficient,» meaning it uses fewer tokens to complete the same task compared to GPT-5.4.

                                      For users requiring speed over depth, OpenAI also introduced a Fast mode in Codex, which generates tokens 1.5x faster but at a 2.5x price premium.

                                      The «mini» and «nano» tiers seen in the GPT-5.4 era (priced at $0.75 and $0.20 per 1M input tokens respectively) currently have no GPT-5.5 equivalent, though the company notes that GPT-5.5 is rolling out to all subscription tiers, including Plus, Pro, and Enterprise.

                                      Licensing and the ‘cyber-permissive’ frontier

                                      OpenAI’s approach to safety and licensing for GPT-5.5 introduces a novel concept: Trusted Access for Cyber. Because the model is now capable of identifying and patching advanced security vulnerabilities, OpenAI has implemented stricter «cyber-risk classifiers» for general users.

                                      For legitimate security professionals, however, OpenAI is offering a specialized «cyber-permissive» license. This program allows verified defenders—those responsible for critical infrastructure like power grids or water supplies—to use models like GPT-5.4-Cyber or unrestricted versions of GPT-5.5 with fewer refusals for security-related prompts.

                                      This dual-use framework acknowledges that while AI can accelerate cyber defense, it can also be weaponized. Under OpenAI’s Preparedness Framework, GPT-5.5 is classified as «High» risk for biological and cybersecurity capabilities.

                                      To manage this, API deployments currently require different safeguards than the consumer-facing ChatGPT, and OpenAI is working with government partners to ensure these tools are used to strengthen—not undermine—digital resilience.

                                      Initial reactions: losing access feels like having a ‘limp amputated’

                                      The early feedback from power users and engineers suggests that GPT-5.5 has crossed a psychological threshold in AI utility. For developers, the model’s ability to maintain «conceptual clarity» across massive codebases is its standout feature.

                                      «The first coding model I’ve used that has serious conceptual clarity,» noted Dan Shipper, CEO of Every.

                                      Shipper tested the model by asking it to debug a complex system failure that had previously required a team of human engineers to rewrite; GPT-5.5 produced the same fix autonomously. Similarly, Pietro Schirano, CEO of MagicPath, described a «step change» in performance when the model successfully merged a branch with hundreds of refactor changes into a main branch in a single, 20-minute pass.Perhaps the most visceral reaction came from an anonymous engineer at NVIDIA, who had early access to the model:

                                      «Losing access to GPT-5.5 feels like I’ve had a limb amputated».

                                      This sentiment is echoed in the scientific community. Derya Unutmaz, a professor at the Jackson Laboratory for Genomic Medicine, used GPT-5.5 Pro to analyze a dataset of 28,000 genes, producing a report in minutes that would have normally taken his team months.

                                      Brandon White, CEO of Axiom Bio, went further, stating that if OpenAI continues this pace, «the foundations of drug discovery will change by the end of the year».

                                      GPT-5.5 is more than an incremental update; it is a tool designed for a world where humans delegate entire workflows rather than single prompts. While the costs are higher and the safety guardrails tighter, the performance gains in agentic work suggest that AI is finally moving from the chat box and into the operating system.

                                      Perhaps most astonishingly of all, it’s not even hearing the end of the scaling limits — whereupon models are trained on more and more GPUs — according to researchers at the company.

                                      «We actually still have headroom to train significantly smarter models than this,» said OpenAI chief scientist Jakub Pachocki.

                                      Tour Cayo Arena Día Feriado Tour Cayo Arena Día Feriado Tour Cayo Arena Día Feriado

                                      After months of rumors and reports that OpenAI was developing a new, more powerful AI large language model for use in ChatGPT and through its application programming interface (API), allegedly codenamed «Spud» internally, the company has today unveiled its latest offering under the more formal name GPT-5.5.

                                      And to likely no one’s surprise, it’s hardly a «potato» in the disparaging sense of the word: GPT-5.5 retakes the lead for OpenAI in generally available LLMs, coming ahead of rivals Anthropic’s and Google’s latest public offerings, and even beating the private Anthropic Claude Mythos Preview model narrowly on one benchmark (essentially a statistical tie).

                                      «It’s definitely our strongest model yet on coding, both measured by benchmarks and based on the feedback that we’ve gotten from trusted partners, as well as our own experience,» explained Amelia «Mia» Glaese, VP of Research at OpenAI, in a video call with journalists ahead of the launch earlier today.

                                      OpenAI positions GPT-5.5 as a fundamental redesign of how intelligence interacts with a computer’s operating system and professional software stacks.

                                      «What is really special about this model is how much more it can do with less guidance,» said OpenAI co-founder and president Greg Brockman on the same call. «It’s way more intuitive to use. It can look at an unclear problem and figure out what needs to happen next.»

                                      Brockman proceeded to emphasize the areas in which users can expect to see gains from using GPT-5.5 compared to OpenAI’s prior state-of-the-art model, GPT-5.4, which remains available (for now) to users and enterprises at half the API cost of its new successor.

                                      «It’s extremely good at coding,» Brockman said of GPT-5.5. «It’s also great at broader computer work, computer use, scientific research—these kinds of applications that are very intelligent bottlenecks.»

                                      OpenAI CEO and-cofounder Sam Altman also weighed in on the launch and the company’s philosophy in a post on X, writing, in part: «We want our users to have access to the best technology and for everyone to have equal opportunity.»

                                      The model is available in two variants: GPT-5.5 and GPT-5.5 Pro, distinguished by the latter offering enhanced precision and specialized logic for handling the most rigorous cognitive demands.

                                      While the standard version serves as the versatile flagship for general intelligence tasks, the Pro model is architected specifically for high-stakes environments such as legal research, data science, and advanced business analytics where accuracy is paramount. This premium tier provides noticeably more comprehensive and better-structured responses, supported by specialized latency optimizations that ensure high-quality performance during complex, multi-step workflows.

                                      Unfortunately for third-party software developers, API access is not yet available for either GPT-5.5 nor GPT-5.5 Pro and will be coming «very soon,» according to the company’s announcement blog post.

                                      «API deployments require different safeguards and we are working closely with partners and customers on the safety and security requirements for serving it at scale,» OpenAI writes.

                                      For the time being, GPT-5.5 is available only to paying subscribers of the ChatGPT Plus ($20 monthly), Pro ($100-$200 monthly), Business, and Enterprise users, with GPT-5.5 Pro access starting at the Pro tier and upwards.

                                      A focus on agency

                                      At the core of GPT-5.5 is a focus on «agentic» performance—specifically in coding, computer use, and scientific research.

                                      Unlike its predecessors, which often required granular, step-by-step prompting to avoid «hallucinating» a path forward, GPT-5.5 is designed to handle messy, multi-part tasks autonomously.

                                      It excels at researching online, debugging complex codebases, and moving between documents and spreadsheets without human intervention.

                                      One of the most significant technical leaps is the model’s efficiency. While larger models typically suffer from increased latency, GPT-5.5 matches the per-token latency of the previous GPT-5.4 while delivering a higher level of intelligence.

                                      This was achieved through a deep hardware-software co-design. OpenAI served GPT-5.5 on NVIDIA GB200 and GB300 NVL72 systems, utilizing custom heuristic algorithms—written by the AI itself—to partition and balance work across GPU cores.

                                      This optimization reportedly increased token generation speeds by over 20%.For high-stakes reasoning, the «GPT-5.5 Thinking» mode in ChatGPT provides smarter, more concise answers by allowing the model more internal «compute time» to verify its own assumptions before responding.

                                      This capability is particularly visible in the model’s performance on «Expert-SWE,» an internal OpenAI benchmark for long-horizon coding tasks with a median human completion time of 20 hours. GPT-5.5 notably outperformed GPT-5.4 on this metric while using significantly fewer tokens.

                                      Benchmarks show OpenAI has retaken the lead in most powerful publicly available LLM over Claude Opus 4.7 (but the unreleased Mythos still outperforms it)

                                      The market for leading U.S.-made frontier models has become an increasingly tight race between OpenAI, Anthropic, and Google.

                                      Literally a week ago to the date, OpenAI rival Anthropic released Opus 4.7, its most powerful generally available model, to the public, taking over the leaderboard in terms of the number of third-party benchmark tests in which it has the lead.

                                      Yet today, GPT-5.5 has surpassed it and even Anthropic’s heavily restricted, more powerful model Claude Mythos Preview, albeit only on one benchmark, Terminal-Bench 2.0, which tests «a model’s ability to navigate and complete tasks in a sandboxed terminal environment.»

                                      GPT-5.5 achieved 82.7% accuracy on Terminal-Bench 2.0, easily surpassing Opus 4.7 (69.4%) and narrowly beating the Mythos Preview (82.0%).

                                      OpenAI GPT-5.5 benchmark comparison table. Credit: OpenAI

                                      However, in multidisciplinary reasoning without tools, the landscape is more competitive. On Humanity’s Last Exam without tools, GPT-5.5 Pro scored 43.1%, trailing behind Opus 4.7 (46.9%) and Mythos Preview (56.8%).

                                      Benchmark

                                      GPT-5.5

                                      Claude Opus 4.7

                                      Gemini 3.1 Pro

                                      Mythos Preview*

                                      Terminal-Bench 2.0

                                      82.7

                                      69.4

                                      68.5

                                      82.0

                                      Expert-SWE (Internal)

                                      73.1

                                      —

                                      —

                                      —

                                      GDPval (wins or ties)

                                      84.9

                                      80.3

                                      67.3

                                      —

                                      OSWorld-Verified

                                      78.7

                                      78.0

                                      —

                                      79.6

                                      Toolathlon

                                      55.6

                                      —

                                      48.8

                                      —

                                      BrowseComp

                                      84.4

                                      79.3

                                      85.9

                                      86.9

                                      FrontierMath Tier 1–3

                                      51.7

                                      43.8

                                      36.9

                                      —

                                      FrontierMath Tier 4

                                      35.4

                                      22.9

                                      16.7

                                      —

                                      CyberGym

                                      81.8

                                      73.1

                                      —

                                      83.1

                                      Tau2-bench Telecom (original prompts)

                                      98.0

                                      —

                                      —

                                      —

                                      OfficeQA Pro

                                      54.1

                                      43.6

                                      18.1

                                      —

                                      Investment Banking Modeling Tasks (Internal)

                                      88.5

                                      —

                                      —

                                      —

                                      MMMU Pro (no tools)

                                      81.2

                                      —

                                      80.5

                                      —

                                      MMMU Pro (with tools)

                                      83.2

                                      —

                                      —

                                      —

                                      GeneBench

                                      25.0

                                      —

                                      —

                                      —

                                      BixBench

                                      80.5

                                      —

                                      —

                                      —

                                      Capture-the-Flags challenge tasks (Internal)

                                      88.1

                                      —

                                      —

                                      —

                                      ARC-AGI-2 (Verified)

                                      85.0

                                      75.8

                                      77.1

                                      —

                                      SWE-bench Pro (Public)

                                      58.6

                                      64.3

                                      54.2

                                      77.8

                                      This suggests that while OpenAI is winning on «computer use» and «agency,» other models may still hold an edge in pure, zero-shot academic knowledge.

                                      It is important to clarify that Mythos Preview is not a generally available product; Anthropic has classified it as a strategic defensive asset due to its high cybersecurity risks, restricting its access to a small, limited audience of trusted partners and government agencies.

                                      Because Mythos is excluded from broad commercial use, the primary market competition remains between GPT-5.5, Gemini 3.1 Pro, and Claude Opus 4.7.

                                      So when it comes to models that the general public can access, GPT-5.5 has retaken the crown for OpenAI, achieving the state-of-the-art across 14 benchmarks compared to 4 for Claude Opus 4.7 and 2 for Google Gemini 3.1 Pro.

                                      It dominates in agentic computer use, economic knowledge work (GDPval), specialized cybersecurity (CyberGym), and complex mathematics (Frontier Math).

                                      In comparison, Claude Opus 4.7 leads on software engineering and reasoning without tools, while Gemini 3.1 Pro leads in three categories, specifically excelling in academic reasoning and financial analysis.

                                      Increased costs for users

                                      The shift in intelligence comes with a significant price increase for API developers, according to material OpenAI shared ahead of the model’s public release.

                                      OpenAI has effectively doubled the entry price for its flagship model compared to the previous generation, and again double it from there for the most-cutting edge variant of the model, GPT-5.5 Pro:

                                      Model

                                      Input Price (per 1M tokens)

                                      Output Price (per 1M tokens)

                                      GPT-5.4

                                      $2.50

                                      $15.00

                                      GPT-5.5

                                      $5.00

                                      $30.00

                                      GPT-5.5 Pro

                                      $30.00

                                      $180.00

                                      To mitigate these costs, OpenAI emphasizes that GPT-5.5 is more «token efficient,» meaning it uses fewer tokens to complete the same task compared to GPT-5.4.

                                      For users requiring speed over depth, OpenAI also introduced a Fast mode in Codex, which generates tokens 1.5x faster but at a 2.5x price premium.

                                      The «mini» and «nano» tiers seen in the GPT-5.4 era (priced at $0.75 and $0.20 per 1M input tokens respectively) currently have no GPT-5.5 equivalent, though the company notes that GPT-5.5 is rolling out to all subscription tiers, including Plus, Pro, and Enterprise.

                                      Licensing and the ‘cyber-permissive’ frontier

                                      OpenAI’s approach to safety and licensing for GPT-5.5 introduces a novel concept: Trusted Access for Cyber. Because the model is now capable of identifying and patching advanced security vulnerabilities, OpenAI has implemented stricter «cyber-risk classifiers» for general users.

                                      For legitimate security professionals, however, OpenAI is offering a specialized «cyber-permissive» license. This program allows verified defenders—those responsible for critical infrastructure like power grids or water supplies—to use models like GPT-5.4-Cyber or unrestricted versions of GPT-5.5 with fewer refusals for security-related prompts.

                                      This dual-use framework acknowledges that while AI can accelerate cyber defense, it can also be weaponized. Under OpenAI’s Preparedness Framework, GPT-5.5 is classified as «High» risk for biological and cybersecurity capabilities.

                                      To manage this, API deployments currently require different safeguards than the consumer-facing ChatGPT, and OpenAI is working with government partners to ensure these tools are used to strengthen—not undermine—digital resilience.

                                      Initial reactions: losing access feels like having a ‘limp amputated’

                                      The early feedback from power users and engineers suggests that GPT-5.5 has crossed a psychological threshold in AI utility. For developers, the model’s ability to maintain «conceptual clarity» across massive codebases is its standout feature.

                                      «The first coding model I’ve used that has serious conceptual clarity,» noted Dan Shipper, CEO of Every.

                                      Shipper tested the model by asking it to debug a complex system failure that had previously required a team of human engineers to rewrite; GPT-5.5 produced the same fix autonomously. Similarly, Pietro Schirano, CEO of MagicPath, described a «step change» in performance when the model successfully merged a branch with hundreds of refactor changes into a main branch in a single, 20-minute pass.Perhaps the most visceral reaction came from an anonymous engineer at NVIDIA, who had early access to the model:

                                      «Losing access to GPT-5.5 feels like I’ve had a limb amputated».

                                      This sentiment is echoed in the scientific community. Derya Unutmaz, a professor at the Jackson Laboratory for Genomic Medicine, used GPT-5.5 Pro to analyze a dataset of 28,000 genes, producing a report in minutes that would have normally taken his team months.

                                      Brandon White, CEO of Axiom Bio, went further, stating that if OpenAI continues this pace, «the foundations of drug discovery will change by the end of the year».

                                      GPT-5.5 is more than an incremental update; it is a tool designed for a world where humans delegate entire workflows rather than single prompts. While the costs are higher and the safety guardrails tighter, the performance gains in agentic work suggest that AI is finally moving from the chat box and into the operating system.

                                      Perhaps most astonishingly of all, it’s not even hearing the end of the scaling limits — whereupon models are trained on more and more GPUs — according to researchers at the company.

                                      «We actually still have headroom to train significantly smarter models than this,» said OpenAI chief scientist Jakub Pachocki.

                                      Tours Colombia Todo el año Tours Colombia Todo el año Tours Colombia Todo el año

                                      After months of rumors and reports that OpenAI was developing a new, more powerful AI large language model for use in ChatGPT and through its application programming interface (API), allegedly codenamed «Spud» internally, the company has today unveiled its latest offering under the more formal name GPT-5.5.

                                      And to likely no one’s surprise, it’s hardly a «potato» in the disparaging sense of the word: GPT-5.5 retakes the lead for OpenAI in generally available LLMs, coming ahead of rivals Anthropic’s and Google’s latest public offerings, and even beating the private Anthropic Claude Mythos Preview model narrowly on one benchmark (essentially a statistical tie).

                                      «It’s definitely our strongest model yet on coding, both measured by benchmarks and based on the feedback that we’ve gotten from trusted partners, as well as our own experience,» explained Amelia «Mia» Glaese, VP of Research at OpenAI, in a video call with journalists ahead of the launch earlier today.

                                      OpenAI positions GPT-5.5 as a fundamental redesign of how intelligence interacts with a computer’s operating system and professional software stacks.

                                      «What is really special about this model is how much more it can do with less guidance,» said OpenAI co-founder and president Greg Brockman on the same call. «It’s way more intuitive to use. It can look at an unclear problem and figure out what needs to happen next.»

                                      Brockman proceeded to emphasize the areas in which users can expect to see gains from using GPT-5.5 compared to OpenAI’s prior state-of-the-art model, GPT-5.4, which remains available (for now) to users and enterprises at half the API cost of its new successor.

                                      «It’s extremely good at coding,» Brockman said of GPT-5.5. «It’s also great at broader computer work, computer use, scientific research—these kinds of applications that are very intelligent bottlenecks.»

                                      OpenAI CEO and-cofounder Sam Altman also weighed in on the launch and the company’s philosophy in a post on X, writing, in part: «We want our users to have access to the best technology and for everyone to have equal opportunity.»

                                      The model is available in two variants: GPT-5.5 and GPT-5.5 Pro, distinguished by the latter offering enhanced precision and specialized logic for handling the most rigorous cognitive demands.

                                      While the standard version serves as the versatile flagship for general intelligence tasks, the Pro model is architected specifically for high-stakes environments such as legal research, data science, and advanced business analytics where accuracy is paramount. This premium tier provides noticeably more comprehensive and better-structured responses, supported by specialized latency optimizations that ensure high-quality performance during complex, multi-step workflows.

                                      Unfortunately for third-party software developers, API access is not yet available for either GPT-5.5 nor GPT-5.5 Pro and will be coming «very soon,» according to the company’s announcement blog post.

                                      «API deployments require different safeguards and we are working closely with partners and customers on the safety and security requirements for serving it at scale,» OpenAI writes.

                                      For the time being, GPT-5.5 is available only to paying subscribers of the ChatGPT Plus ($20 monthly), Pro ($100-$200 monthly), Business, and Enterprise users, with GPT-5.5 Pro access starting at the Pro tier and upwards.

                                      A focus on agency

                                      At the core of GPT-5.5 is a focus on «agentic» performance—specifically in coding, computer use, and scientific research.

                                      Unlike its predecessors, which often required granular, step-by-step prompting to avoid «hallucinating» a path forward, GPT-5.5 is designed to handle messy, multi-part tasks autonomously.

                                      It excels at researching online, debugging complex codebases, and moving between documents and spreadsheets without human intervention.

                                      One of the most significant technical leaps is the model’s efficiency. While larger models typically suffer from increased latency, GPT-5.5 matches the per-token latency of the previous GPT-5.4 while delivering a higher level of intelligence.

                                      This was achieved through a deep hardware-software co-design. OpenAI served GPT-5.5 on NVIDIA GB200 and GB300 NVL72 systems, utilizing custom heuristic algorithms—written by the AI itself—to partition and balance work across GPU cores.

                                      This optimization reportedly increased token generation speeds by over 20%.For high-stakes reasoning, the «GPT-5.5 Thinking» mode in ChatGPT provides smarter, more concise answers by allowing the model more internal «compute time» to verify its own assumptions before responding.

                                      This capability is particularly visible in the model’s performance on «Expert-SWE,» an internal OpenAI benchmark for long-horizon coding tasks with a median human completion time of 20 hours. GPT-5.5 notably outperformed GPT-5.4 on this metric while using significantly fewer tokens.

                                      Benchmarks show OpenAI has retaken the lead in most powerful publicly available LLM over Claude Opus 4.7 (but the unreleased Mythos still outperforms it)

                                      The market for leading U.S.-made frontier models has become an increasingly tight race between OpenAI, Anthropic, and Google.

                                      Literally a week ago to the date, OpenAI rival Anthropic released Opus 4.7, its most powerful generally available model, to the public, taking over the leaderboard in terms of the number of third-party benchmark tests in which it has the lead.

                                      Yet today, GPT-5.5 has surpassed it and even Anthropic’s heavily restricted, more powerful model Claude Mythos Preview, albeit only on one benchmark, Terminal-Bench 2.0, which tests «a model’s ability to navigate and complete tasks in a sandboxed terminal environment.»

                                      GPT-5.5 achieved 82.7% accuracy on Terminal-Bench 2.0, easily surpassing Opus 4.7 (69.4%) and narrowly beating the Mythos Preview (82.0%).

                                      OpenAI GPT-5.5 benchmark comparison table. Credit: OpenAI

                                      However, in multidisciplinary reasoning without tools, the landscape is more competitive. On Humanity’s Last Exam without tools, GPT-5.5 Pro scored 43.1%, trailing behind Opus 4.7 (46.9%) and Mythos Preview (56.8%).

                                      Benchmark

                                      GPT-5.5

                                      Claude Opus 4.7

                                      Gemini 3.1 Pro

                                      Mythos Preview*

                                      Terminal-Bench 2.0

                                      82.7

                                      69.4

                                      68.5

                                      82.0

                                      Expert-SWE (Internal)

                                      73.1

                                      —

                                      —

                                      —

                                      GDPval (wins or ties)

                                      84.9

                                      80.3

                                      67.3

                                      —

                                      OSWorld-Verified

                                      78.7

                                      78.0

                                      —

                                      79.6

                                      Toolathlon

                                      55.6

                                      —

                                      48.8

                                      —

                                      BrowseComp

                                      84.4

                                      79.3

                                      85.9

                                      86.9

                                      FrontierMath Tier 1–3

                                      51.7

                                      43.8

                                      36.9

                                      —

                                      FrontierMath Tier 4

                                      35.4

                                      22.9

                                      16.7

                                      —

                                      CyberGym

                                      81.8

                                      73.1

                                      —

                                      83.1

                                      Tau2-bench Telecom (original prompts)

                                      98.0

                                      —

                                      —

                                      —

                                      OfficeQA Pro

                                      54.1

                                      43.6

                                      18.1

                                      —

                                      Investment Banking Modeling Tasks (Internal)

                                      88.5

                                      —

                                      —

                                      —

                                      MMMU Pro (no tools)

                                      81.2

                                      —

                                      80.5

                                      —

                                      MMMU Pro (with tools)

                                      83.2

                                      —

                                      —

                                      —

                                      GeneBench

                                      25.0

                                      —

                                      —

                                      —

                                      BixBench

                                      80.5

                                      —

                                      —

                                      —

                                      Capture-the-Flags challenge tasks (Internal)

                                      88.1

                                      —

                                      —

                                      —

                                      ARC-AGI-2 (Verified)

                                      85.0

                                      75.8

                                      77.1

                                      —

                                      SWE-bench Pro (Public)

                                      58.6

                                      64.3

                                      54.2

                                      77.8

                                      This suggests that while OpenAI is winning on «computer use» and «agency,» other models may still hold an edge in pure, zero-shot academic knowledge.

                                      It is important to clarify that Mythos Preview is not a generally available product; Anthropic has classified it as a strategic defensive asset due to its high cybersecurity risks, restricting its access to a small, limited audience of trusted partners and government agencies.

                                      Because Mythos is excluded from broad commercial use, the primary market competition remains between GPT-5.5, Gemini 3.1 Pro, and Claude Opus 4.7.

                                      So when it comes to models that the general public can access, GPT-5.5 has retaken the crown for OpenAI, achieving the state-of-the-art across 14 benchmarks compared to 4 for Claude Opus 4.7 and 2 for Google Gemini 3.1 Pro.

                                      It dominates in agentic computer use, economic knowledge work (GDPval), specialized cybersecurity (CyberGym), and complex mathematics (Frontier Math).

                                      In comparison, Claude Opus 4.7 leads on software engineering and reasoning without tools, while Gemini 3.1 Pro leads in three categories, specifically excelling in academic reasoning and financial analysis.

                                      Increased costs for users

                                      The shift in intelligence comes with a significant price increase for API developers, according to material OpenAI shared ahead of the model’s public release.

                                      OpenAI has effectively doubled the entry price for its flagship model compared to the previous generation, and again double it from there for the most-cutting edge variant of the model, GPT-5.5 Pro:

                                      Model

                                      Input Price (per 1M tokens)

                                      Output Price (per 1M tokens)

                                      GPT-5.4

                                      $2.50

                                      $15.00

                                      GPT-5.5

                                      $5.00

                                      $30.00

                                      GPT-5.5 Pro

                                      $30.00

                                      $180.00

                                      To mitigate these costs, OpenAI emphasizes that GPT-5.5 is more «token efficient,» meaning it uses fewer tokens to complete the same task compared to GPT-5.4.

                                      For users requiring speed over depth, OpenAI also introduced a Fast mode in Codex, which generates tokens 1.5x faster but at a 2.5x price premium.

                                      The «mini» and «nano» tiers seen in the GPT-5.4 era (priced at $0.75 and $0.20 per 1M input tokens respectively) currently have no GPT-5.5 equivalent, though the company notes that GPT-5.5 is rolling out to all subscription tiers, including Plus, Pro, and Enterprise.

                                      Licensing and the ‘cyber-permissive’ frontier

                                      OpenAI’s approach to safety and licensing for GPT-5.5 introduces a novel concept: Trusted Access for Cyber. Because the model is now capable of identifying and patching advanced security vulnerabilities, OpenAI has implemented stricter «cyber-risk classifiers» for general users.

                                      For legitimate security professionals, however, OpenAI is offering a specialized «cyber-permissive» license. This program allows verified defenders—those responsible for critical infrastructure like power grids or water supplies—to use models like GPT-5.4-Cyber or unrestricted versions of GPT-5.5 with fewer refusals for security-related prompts.

                                      This dual-use framework acknowledges that while AI can accelerate cyber defense, it can also be weaponized. Under OpenAI’s Preparedness Framework, GPT-5.5 is classified as «High» risk for biological and cybersecurity capabilities.

                                      To manage this, API deployments currently require different safeguards than the consumer-facing ChatGPT, and OpenAI is working with government partners to ensure these tools are used to strengthen—not undermine—digital resilience.

                                      Initial reactions: losing access feels like having a ‘limp amputated’

                                      The early feedback from power users and engineers suggests that GPT-5.5 has crossed a psychological threshold in AI utility. For developers, the model’s ability to maintain «conceptual clarity» across massive codebases is its standout feature.

                                      «The first coding model I’ve used that has serious conceptual clarity,» noted Dan Shipper, CEO of Every.

                                      Shipper tested the model by asking it to debug a complex system failure that had previously required a team of human engineers to rewrite; GPT-5.5 produced the same fix autonomously. Similarly, Pietro Schirano, CEO of MagicPath, described a «step change» in performance when the model successfully merged a branch with hundreds of refactor changes into a main branch in a single, 20-minute pass.Perhaps the most visceral reaction came from an anonymous engineer at NVIDIA, who had early access to the model:

                                      «Losing access to GPT-5.5 feels like I’ve had a limb amputated».

                                      This sentiment is echoed in the scientific community. Derya Unutmaz, a professor at the Jackson Laboratory for Genomic Medicine, used GPT-5.5 Pro to analyze a dataset of 28,000 genes, producing a report in minutes that would have normally taken his team months.

                                      Brandon White, CEO of Axiom Bio, went further, stating that if OpenAI continues this pace, «the foundations of drug discovery will change by the end of the year».

                                      GPT-5.5 is more than an incremental update; it is a tool designed for a world where humans delegate entire workflows rather than single prompts. While the costs are higher and the safety guardrails tighter, the performance gains in agentic work suggest that AI is finally moving from the chat box and into the operating system.

                                      Perhaps most astonishingly of all, it’s not even hearing the end of the scaling limits — whereupon models are trained on more and more GPUs — according to researchers at the company.

                                      «We actually still have headroom to train significantly smarter models than this,» said OpenAI chief scientist Jakub Pachocki.

                                      Tour Cayo Arena Día Feriado Tour Cayo Arena Día Feriado Tour Cayo Arena Día Feriado

                                      After months of rumors and reports that OpenAI was developing a new, more powerful AI large language model for use in ChatGPT and through its application programming interface (API), allegedly codenamed «Spud» internally, the company has today unveiled its latest offering under the more formal name GPT-5.5.

                                      And to likely no one’s surprise, it’s hardly a «potato» in the disparaging sense of the word: GPT-5.5 retakes the lead for OpenAI in generally available LLMs, coming ahead of rivals Anthropic’s and Google’s latest public offerings, and even beating the private Anthropic Claude Mythos Preview model narrowly on one benchmark (essentially a statistical tie).

                                      «It’s definitely our strongest model yet on coding, both measured by benchmarks and based on the feedback that we’ve gotten from trusted partners, as well as our own experience,» explained Amelia «Mia» Glaese, VP of Research at OpenAI, in a video call with journalists ahead of the launch earlier today.

                                      OpenAI positions GPT-5.5 as a fundamental redesign of how intelligence interacts with a computer’s operating system and professional software stacks.

                                      «What is really special about this model is how much more it can do with less guidance,» said OpenAI co-founder and president Greg Brockman on the same call. «It’s way more intuitive to use. It can look at an unclear problem and figure out what needs to happen next.»

                                      Brockman proceeded to emphasize the areas in which users can expect to see gains from using GPT-5.5 compared to OpenAI’s prior state-of-the-art model, GPT-5.4, which remains available (for now) to users and enterprises at half the API cost of its new successor.

                                      «It’s extremely good at coding,» Brockman said of GPT-5.5. «It’s also great at broader computer work, computer use, scientific research—these kinds of applications that are very intelligent bottlenecks.»

                                      OpenAI CEO and-cofounder Sam Altman also weighed in on the launch and the company’s philosophy in a post on X, writing, in part: «We want our users to have access to the best technology and for everyone to have equal opportunity.»

                                      The model is available in two variants: GPT-5.5 and GPT-5.5 Pro, distinguished by the latter offering enhanced precision and specialized logic for handling the most rigorous cognitive demands.

                                      While the standard version serves as the versatile flagship for general intelligence tasks, the Pro model is architected specifically for high-stakes environments such as legal research, data science, and advanced business analytics where accuracy is paramount. This premium tier provides noticeably more comprehensive and better-structured responses, supported by specialized latency optimizations that ensure high-quality performance during complex, multi-step workflows.

                                      Unfortunately for third-party software developers, API access is not yet available for either GPT-5.5 nor GPT-5.5 Pro and will be coming «very soon,» according to the company’s announcement blog post.

                                      «API deployments require different safeguards and we are working closely with partners and customers on the safety and security requirements for serving it at scale,» OpenAI writes.

                                      For the time being, GPT-5.5 is available only to paying subscribers of the ChatGPT Plus ($20 monthly), Pro ($100-$200 monthly), Business, and Enterprise users, with GPT-5.5 Pro access starting at the Pro tier and upwards.

                                      A focus on agency

                                      At the core of GPT-5.5 is a focus on «agentic» performance—specifically in coding, computer use, and scientific research.

                                      Unlike its predecessors, which often required granular, step-by-step prompting to avoid «hallucinating» a path forward, GPT-5.5 is designed to handle messy, multi-part tasks autonomously.

                                      It excels at researching online, debugging complex codebases, and moving between documents and spreadsheets without human intervention.

                                      One of the most significant technical leaps is the model’s efficiency. While larger models typically suffer from increased latency, GPT-5.5 matches the per-token latency of the previous GPT-5.4 while delivering a higher level of intelligence.

                                      This was achieved through a deep hardware-software co-design. OpenAI served GPT-5.5 on NVIDIA GB200 and GB300 NVL72 systems, utilizing custom heuristic algorithms—written by the AI itself—to partition and balance work across GPU cores.

                                      This optimization reportedly increased token generation speeds by over 20%.For high-stakes reasoning, the «GPT-5.5 Thinking» mode in ChatGPT provides smarter, more concise answers by allowing the model more internal «compute time» to verify its own assumptions before responding.

                                      This capability is particularly visible in the model’s performance on «Expert-SWE,» an internal OpenAI benchmark for long-horizon coding tasks with a median human completion time of 20 hours. GPT-5.5 notably outperformed GPT-5.4 on this metric while using significantly fewer tokens.

                                      Benchmarks show OpenAI has retaken the lead in most powerful publicly available LLM over Claude Opus 4.7 (but the unreleased Mythos still outperforms it)

                                      The market for leading U.S.-made frontier models has become an increasingly tight race between OpenAI, Anthropic, and Google.

                                      Literally a week ago to the date, OpenAI rival Anthropic released Opus 4.7, its most powerful generally available model, to the public, taking over the leaderboard in terms of the number of third-party benchmark tests in which it has the lead.

                                      Yet today, GPT-5.5 has surpassed it and even Anthropic’s heavily restricted, more powerful model Claude Mythos Preview, albeit only on one benchmark, Terminal-Bench 2.0, which tests «a model’s ability to navigate and complete tasks in a sandboxed terminal environment.»

                                      GPT-5.5 achieved 82.7% accuracy on Terminal-Bench 2.0, easily surpassing Opus 4.7 (69.4%) and narrowly beating the Mythos Preview (82.0%).

                                      OpenAI GPT-5.5 benchmark comparison table. Credit: OpenAI

                                      However, in multidisciplinary reasoning without tools, the landscape is more competitive. On Humanity’s Last Exam without tools, GPT-5.5 Pro scored 43.1%, trailing behind Opus 4.7 (46.9%) and Mythos Preview (56.8%).

                                      Benchmark

                                      GPT-5.5

                                      Claude Opus 4.7

                                      Gemini 3.1 Pro

                                      Mythos Preview*

                                      Terminal-Bench 2.0

                                      82.7

                                      69.4

                                      68.5

                                      82.0

                                      Expert-SWE (Internal)

                                      73.1

                                      —

                                      —

                                      —

                                      GDPval (wins or ties)

                                      84.9

                                      80.3

                                      67.3

                                      —

                                      OSWorld-Verified

                                      78.7

                                      78.0

                                      —

                                      79.6

                                      Toolathlon

                                      55.6

                                      —

                                      48.8

                                      —

                                      BrowseComp

                                      84.4

                                      79.3

                                      85.9

                                      86.9

                                      FrontierMath Tier 1–3

                                      51.7

                                      43.8

                                      36.9

                                      —

                                      FrontierMath Tier 4

                                      35.4

                                      22.9

                                      16.7

                                      —

                                      CyberGym

                                      81.8

                                      73.1

                                      —

                                      83.1

                                      Tau2-bench Telecom (original prompts)

                                      98.0

                                      —

                                      —

                                      —

                                      OfficeQA Pro

                                      54.1

                                      43.6

                                      18.1

                                      —

                                      Investment Banking Modeling Tasks (Internal)

                                      88.5

                                      —

                                      —

                                      —

                                      MMMU Pro (no tools)

                                      81.2

                                      —

                                      80.5

                                      —

                                      MMMU Pro (with tools)

                                      83.2

                                      —

                                      —

                                      —

                                      GeneBench

                                      25.0

                                      —

                                      —

                                      —

                                      BixBench

                                      80.5

                                      —

                                      —

                                      —

                                      Capture-the-Flags challenge tasks (Internal)

                                      88.1

                                      —

                                      —

                                      —

                                      ARC-AGI-2 (Verified)

                                      85.0

                                      75.8

                                      77.1

                                      —

                                      SWE-bench Pro (Public)

                                      58.6

                                      64.3

                                      54.2

                                      77.8

                                      This suggests that while OpenAI is winning on «computer use» and «agency,» other models may still hold an edge in pure, zero-shot academic knowledge.

                                      It is important to clarify that Mythos Preview is not a generally available product; Anthropic has classified it as a strategic defensive asset due to its high cybersecurity risks, restricting its access to a small, limited audience of trusted partners and government agencies.

                                      Because Mythos is excluded from broad commercial use, the primary market competition remains between GPT-5.5, Gemini 3.1 Pro, and Claude Opus 4.7.

                                      So when it comes to models that the general public can access, GPT-5.5 has retaken the crown for OpenAI, achieving the state-of-the-art across 14 benchmarks compared to 4 for Claude Opus 4.7 and 2 for Google Gemini 3.1 Pro.

                                      It dominates in agentic computer use, economic knowledge work (GDPval), specialized cybersecurity (CyberGym), and complex mathematics (Frontier Math).

                                      In comparison, Claude Opus 4.7 leads on software engineering and reasoning without tools, while Gemini 3.1 Pro leads in three categories, specifically excelling in academic reasoning and financial analysis.

                                      Increased costs for users

                                      The shift in intelligence comes with a significant price increase for API developers, according to material OpenAI shared ahead of the model’s public release.

                                      OpenAI has effectively doubled the entry price for its flagship model compared to the previous generation, and again double it from there for the most-cutting edge variant of the model, GPT-5.5 Pro:

                                      Model

                                      Input Price (per 1M tokens)

                                      Output Price (per 1M tokens)

                                      GPT-5.4

                                      $2.50

                                      $15.00

                                      GPT-5.5

                                      $5.00

                                      $30.00

                                      GPT-5.5 Pro

                                      $30.00

                                      $180.00

                                      To mitigate these costs, OpenAI emphasizes that GPT-5.5 is more «token efficient,» meaning it uses fewer tokens to complete the same task compared to GPT-5.4.

                                      For users requiring speed over depth, OpenAI also introduced a Fast mode in Codex, which generates tokens 1.5x faster but at a 2.5x price premium.

                                      The «mini» and «nano» tiers seen in the GPT-5.4 era (priced at $0.75 and $0.20 per 1M input tokens respectively) currently have no GPT-5.5 equivalent, though the company notes that GPT-5.5 is rolling out to all subscription tiers, including Plus, Pro, and Enterprise.

                                      Licensing and the ‘cyber-permissive’ frontier

                                      OpenAI’s approach to safety and licensing for GPT-5.5 introduces a novel concept: Trusted Access for Cyber. Because the model is now capable of identifying and patching advanced security vulnerabilities, OpenAI has implemented stricter «cyber-risk classifiers» for general users.

                                      For legitimate security professionals, however, OpenAI is offering a specialized «cyber-permissive» license. This program allows verified defenders—those responsible for critical infrastructure like power grids or water supplies—to use models like GPT-5.4-Cyber or unrestricted versions of GPT-5.5 with fewer refusals for security-related prompts.

                                      This dual-use framework acknowledges that while AI can accelerate cyber defense, it can also be weaponized. Under OpenAI’s Preparedness Framework, GPT-5.5 is classified as «High» risk for biological and cybersecurity capabilities.

                                      To manage this, API deployments currently require different safeguards than the consumer-facing ChatGPT, and OpenAI is working with government partners to ensure these tools are used to strengthen—not undermine—digital resilience.

                                      Initial reactions: losing access feels like having a ‘limp amputated’

                                      The early feedback from power users and engineers suggests that GPT-5.5 has crossed a psychological threshold in AI utility. For developers, the model’s ability to maintain «conceptual clarity» across massive codebases is its standout feature.

                                      «The first coding model I’ve used that has serious conceptual clarity,» noted Dan Shipper, CEO of Every.

                                      Shipper tested the model by asking it to debug a complex system failure that had previously required a team of human engineers to rewrite; GPT-5.5 produced the same fix autonomously. Similarly, Pietro Schirano, CEO of MagicPath, described a «step change» in performance when the model successfully merged a branch with hundreds of refactor changes into a main branch in a single, 20-minute pass.Perhaps the most visceral reaction came from an anonymous engineer at NVIDIA, who had early access to the model:

                                      «Losing access to GPT-5.5 feels like I’ve had a limb amputated».

                                      This sentiment is echoed in the scientific community. Derya Unutmaz, a professor at the Jackson Laboratory for Genomic Medicine, used GPT-5.5 Pro to analyze a dataset of 28,000 genes, producing a report in minutes that would have normally taken his team months.

                                      Brandon White, CEO of Axiom Bio, went further, stating that if OpenAI continues this pace, «the foundations of drug discovery will change by the end of the year».

                                      GPT-5.5 is more than an incremental update; it is a tool designed for a world where humans delegate entire workflows rather than single prompts. While the costs are higher and the safety guardrails tighter, the performance gains in agentic work suggest that AI is finally moving from the chat box and into the operating system.

                                      Perhaps most astonishingly of all, it’s not even hearing the end of the scaling limits — whereupon models are trained on more and more GPUs — according to researchers at the company.

                                      «We actually still have headroom to train significantly smarter models than this,» said OpenAI chief scientist Jakub Pachocki.

                                      ● Canal oficial · Gratis
                                      ¡Recibe las noticias antes que nadie!
                                      Únete a nuestro canal de WhatsApp y mantente informado al instante, sin spam.
                                      Unirme ahora →
                                      ● Noticias al instante ● Cobertura nacional ● Periodismo real Despertar Matinal
                                      — Redacción Despertar Matinal

                                      — Redacción Despertar Matinal

                                      Programa radial que te conecta con la información desde temprano en la mañana.

                                      Next Post
                                      Digemaps detecta irregularidades en la entrega de suplementos a niños con autismo

                                      Digemaps detecta irregularidades en la entrega de suplementos a niños con autismo

                                      Deja una respuesta Cancelar la respuesta

                                      Tu dirección de correo electrónico no será publicada. Los campos obligatorios están marcados con *

                                      Canal de WhatsApp

                                      WhatsApp logo WhatsApp

                                      Canal · Despertar Matinal

                                      Únete a nuestro
                                      Canal

                                      Seguir ahora

                                      El clima

                                      Canal de YouTube

                                      YouTube

                                      Canal · Despertar Matinal

                                      Mira nuestro
                                      Canal

                                      Ver ahora

                                      Escúchanos en Spotify

                                      Spotify

                                      Podcast · Despertar Matinal

                                      Escucha nuestro
                                      Podcast

                                      Escuchar ahora

                                      Noticias Populares

                                      • Mauricio Macri intentó relanzar el PRO en Jujuy pero no fue nadie

                                        Mauricio Macri intentó relanzar el PRO en Jujuy pero no fue nadie

                                        0 shares
                                        Share 0 Tweet 0
                                      • Uno por uno: así son los 16 estadios que recibirán el Mundial 2026

                                        0 shares
                                        Share 0 Tweet 0
                                      • Eutanasia en Canadá: investigan la muerte de una abuela que habría sido sometida al procedimiento contra su voluntad

                                        0 shares
                                        Share 0 Tweet 0
                                      • El voto evangélico para Lula da Silva en las elecciones de Brasil

                                        0 shares
                                        Share 0 Tweet 0
                                      • CONAP PLD niega maniobra para sacar 523 mil de padrón

                                        0 shares
                                        Share 0 Tweet 0

                                      Medio digital independiente con análisis, opinión y periodismo responsable desde República Dominicana.

                                      Secciones populares

                                      • Política
                                      • Economía & Negocios
                                      • Justicia
                                      • Turismo
                                      • Tecnología
                                      • Entretenimiento
                                      • Mundo
                                      • Cine y Series
                                      • Música
                                      • Moda

                                      Contenido

                                      • Titulares del Día
                                      • Mundo
                                      • Nacionales
                                      • Política
                                      • Deportes
                                      • Economía & Negocios
                                      • Ciencia
                                      • Entretenimiento
                                      • Podcast
                                      • Opinión
                                      • Despertar Matinal TV
                                      • Editoriales

                                      Corporativo

                                      • Sobre nosotros
                                      • Publicidad
                                      • Sala de prensa
                                      • Contacto
                                      • Política de Privacidad
                                      • Eliminación de Datos

                                      Boletines

                                      Suscríbete a nuestro boletín
                                      Recibe las noticias más importantes cada mañana.

                                      • Nosotros
                                      • Publicidad
                                      • Trabaja con nosotros
                                      • Contactos

                                      © 2025 Despertar Matinal. Aviso Legal - comunícate con nuestra redacción y obtén más información sobre Despertar Matinal..

                                      No Result
                                      View All Result
                                      • Home

                                      © 2025 Despertar Matinal. Aviso Legal - comunícate con nuestra redacción y obtén más información sobre Despertar Matinal..

                                      Welcome Back!

                                      Login to your account below

                                      Forgotten Password?

                                      Retrieve your password

                                      Please enter your username or email address to reset your password.

                                      Log In

                                      Desarrollado por
                                      ►
                                      Las cookies necesarias habilitan funciones esenciales del sitio como inicios de sesión seguros y ajustes de preferencias de consentimiento. No almacenan datos personales.
                                      Ninguno
                                      ►
                                      Las cookies funcionales soportan funciones como compartir contenido en redes sociales, recopilar comentarios y habilitar herramientas de terceros.
                                      Ninguno
                                      ►
                                      Las cookies analíticas rastrean las interacciones de los visitantes, proporcionando información sobre métricas como el número de visitantes, la tasa de rebote y las fuentes de tráfico.
                                      Ninguno
                                      ►
                                      Las cookies de publicidad ofrecen anuncios personalizados basados en tus visitas anteriores y analizan la efectividad de las campañas publicitarias.
                                      Ninguno
                                      ►
                                      Las cookies no clasificadas son aquellas que estamos en proceso de clasificar, junto con los proveedores de cookies individuales.
                                      Ninguno
                                      Desarrollado por